AiAnyTool - Best AI Tools Directory and Artificial Intelligence Software Hub Logo
Loading theme toggle
Real-Time Coverage

AI News Today

Live

33214 stories from 30+ sources, refreshed continuously.

arXiv cs.LGResearch

Valdi: Value Diffusion World Models

arXiv:2607.00917v1 Announce Type: new Abstract: World models can enable Model Predictive Control (MPC), but this requires dynamics prediction that is both fast enough for online use and expressive enough to represent uncertain futures. Diffusion models offer a natural mechanism for modeling uncertain dynamics, yet their iterative inference procedure makes them difficult to use for low-latency latent planning. We bridge this gap with Value Diffusion World Models (Valdi), combining end-to-end onli

Read source article
arXiv cs.LGResearch

Human-Machine Collaboration on Generative Meta-Learning: Model and Algorithm

arXiv:2607.00926v1 Announce Type: new Abstract: Generalizing machine learning models to environments that differ from their training distribution remains a critical hurdle, particularly when data from the target domain is entirely or partially unavailable. We propose Generative Meta-Learning with Human Feedback (GMHF), a novel framework that bridges this domain gap by leveraging expert intuition to guide data synthesis. Grounded in a theoretical analysis of generalization error, we derive bounds

Read source article
arXiv cs.LGResearch

CausalMix: Data Mixture as Causal Inference for Language Model Training

arXiv:2607.01104v1 Announce Type: new Abstract: In Large Language Model (LLM) training, data mixing plays a pivotal role in determining model performance. Recent methods optimize mixture weights via proxy models, but they rely on the assumption of static data distributions. As a result, when the underlying data pool shifts, these methods require costly retraining from scratch. This limitation restricts their ability to scale seamlessly from small settings to larger data pools and model sizes. In

Read source article
arXiv cs.LGResearch

Muon as a Residual Connection

arXiv:2607.01124v1 Announce Type: new Abstract: Muon has recently emerged as one of the most effective optimizers for training large neural networks, yet its empirical success has been explained from several different perspectives. In this paper, we propose a simple mechanistic interpretation: Muon can be understood as an implicit residual connection during training. Specifically, orthogonalizing the update can sacrifice some immediate gradient fidelity while improving representation preservatio

Read source article
arXiv cs.LGResearch

Sequentially-Controlled Interactive Multi-Particle Flow-Maps for Online Feedback-Driven Search

arXiv:2607.01144v1 Announce Type: new Abstract: While generative models have enabled training-free reward alignment, current methods typically excel in local exploration within narrow regions of the underlying distribution. These approaches struggle when preferences are unknown a priori and only revealed through sequential feedback-a scenario demanding broad exploration to uncover high-utility regions. To address this, we propose Sequentially-Controlled Interactive Multi-Particle Flow-Maps (IMPF

Read source article
arXiv cs.LGResearch

Right in the Right Way: LM Training with Verifiable Rewards and Human Demonstrations

arXiv:2607.01181v1 Announce Type: new Abstract: RL with verifiable rewards (RLVR) has emerged as a powerful paradigm for training LMs on tasks with well-defined success metrics, such as code generation and mathematical reasoning. However, current RLVR methods optimize only what can be objectively scored, often neglecting subjective, non-verifiable aspects of human-like outputs, such as style and structure. This limitation leads to well-documented failure modes such as diversity collapse, unnatur

Read source article
arXiv cs.LGResearch

Logit-Contribution Scoring Identifies Non-Literal Retrieval Heads

arXiv:2607.01002v1 Announce Type: cross Abstract: In long-context use, large language models frequently synthesize answers from the meaning of a relevant context span rather than literally copy-pasting them. Identifying which attention heads perform this synthesis matters for interpreting long-context model behavior. Yet existing detectors miss these heads by construction: they reward heads whose attended token matches the generated token, a literal-copy criterion that captures where a head read

Read source article
arXiv cs.LGResearch

FAR: Failure-Aware Retry for Test-Time Recovery and Continual Policy Improvement

arXiv:2607.01111v1 Announce Type: cross Abstract: Robot policies inevitably encounter failures when deployed in real environments. Naive retries often repeat the same mistakes, while many existing recovery methods rely on human intervention. In this paper, we propose Failure-Aware Retry (FAR), a framework that enables robots to learn from previous failures at test time, adapt their behavior accordingly, and eventually complete the task autonomously. FAR combines Failure-Contrastive Preference Ad

Read source article
arXiv cs.LGResearch

GPU-Parallel Linearization Error Bounds for Real-Time Robust Optimal Control of Nonlinear and Neural Network Dynamics

arXiv:2607.01203v1 Announce Type: cross Abstract: This paper studies real-time robust optimal control for uncertain nonlinear systems, where linear time-varying (LTV) approximations make planning tractable but require sound linearization error bounds (LEBs) to guarantee robust constraint satisfaction. We develop tight, differentiable, GPU-parallel LEBs for LTV approximations of nonlinear and neural network (NN) dynamics. For analytic dynamics, we introduce path-based Hessian bounds that are tigh

Read source article
arXiv cs.LGResearch

The State-Prediction Separation Hypothesis

arXiv:2607.01218v1 Announce Type: cross Abstract: Transformers use the same forward computation stream to both predict the next token and store useful state for future token predictions. We formulate the \emph{state-prediction separation hypothesis}: disentangling the two roles yields better language modeling performance. We design a Transformer variant that uses two computation streams to separate the two functions, and conduct pretraining experiments across various scales. Our experiments show

Read source article
arXiv cs.LGResearch

Enhancing Hardware Fault Tolerance in Machines with Reinforcement Learning Policy Gradient Algorithms

arXiv:2407.15283v2 Announce Type: replace Abstract: Industry is moving toward autonomous, network-connected machines that detect and adapt to changing conditions, including hardware faults. Conventional fault-tolerant design duplicates hardware and reroutes control logic; reinforcement learning (RL) offers a learning-based alternative. This paper presents the first systematic comparison of two RL algorithms -- Proximal Policy Optimization (PPO) and Soft Actor-Critic (SAC) -- for integrating faul

Read source article
arXiv cs.LGResearch

Multiplicity is an Inevitable and Inherent Challenge in Multimodal Learning

arXiv:2505.19614v2 Announce Type: replace Abstract: Multimodal learning has seen remarkable progress, particularly with large-scale pre-training across various modalities. Most current approaches are built on the assumption of a deterministic one-to-one alignment between modalities. However, this oversimplifies real-world multimodal relationships, where their nature is inherently many-to-many. The many-to-many property, or multiplicity, is not a side-effect of noise or annotation error, but an i

Read source article
arXiv cs.LGResearch

scDataset: Scalable Data Loading for Deep Learning on Large-Scale Single-Cell Omics

arXiv:2506.01883v3 Announce Type: replace Abstract: Training deep learning models on single-cell datasets with hundreds of millions of cells requires loading data from disk, as these datasets exceed available memory. While random sampling provides the data diversity needed for effective training, it is prohibitively slow due to the random access pattern overhead, whereas sequential streaming achieves high throughput but introduces biases that degrade model performance. We present scDataset, a Py

Read source article
arXiv cs.LGResearch

Fraud is Not Just Rarity: A Causal Prototype Attention Approach to Realistic Synthetic Oversampling

arXiv:2507.14706v2 Announce Type: replace Abstract: Detecting fraudulent credit card transactions remains a significant challenge, due to the extreme class imbalance in real-world data and the often subtle patterns that separate fraud from legitimate activity. Existing research commonly attempts to address this by generating synthetic samples for the minority class using approaches such as GANs, VAEs (Variational Autoencoders), or hybrid generative models. However, these techniques, particularly

Read source article
arXiv cs.LGResearch

TANDEM: Temporal Attention-guided Neural Differential Equations for Missingness in Time Series Classification

arXiv:2508.17519v3 Announce Type: replace Abstract: Handling missing data in time series classification remains a significant challenge in various domains. Traditional methods often rely on imputation, which may introduce bias or fail to capture the underlying temporal dynamics. In this paper, we propose TANDEM (Temporal Attention-guided Neural Differential Equations for Missingness), an attention-guided neural differential equation framework that effectively classifies time series data with mis

Read source article
arXiv cs.LGResearch

Predicting LLM Reasoning Performance with Small Proxy Model

arXiv:2509.21013v4 Announce Type: replace Abstract: Given the prohibitive cost of pre-training large language models, it is essential to leverage smaller proxy models to optimize datasets before scaling up. However, this approach becomes challenging for reasoning capabilities, which exhibit emergent behavior that only appear reliably at larger model sizes, often exceeding 7B parameters. To address this, we introduce rBridge, showing that small proxies ($\leq$1B) can effectively predict large-mod

Read source article
arXiv cs.LGResearch

K-Merge: Online Continual Merging of Adapters for On-device Large Language Models

arXiv:2510.13537v2 Announce Type: replace Abstract: On-device deployment of Large Language Models (LLMs) frequently leverages Low-Rank Adapters (LoRAs) to support diverse downstream tasks under tight resource constraints. To address the limited storage capacity of mobile devices, recent works have explored model merging techniques to fuse multiple LoRAs into a single one. In practice, however, LoRAs are often delivered incrementally, as users request support for new tasks (e.g., novel problem ty

Read source article
arXiv cs.LGResearch

FlowPath: Learning Data-Driven Manifolds with Invertible Flows for Robust Irregularly-sampled Time Series Classification

arXiv:2511.10841v3 Announce Type: replace Abstract: Modeling continuous-time dynamics from sparse and irregularly-sampled time series remains a fundamental challenge. Neural controlled differential equations provide a principled framework for such tasks, yet their performance is highly sensitive to the choice of control path constructed from discrete observations. Existing methods commonly employ fixed interpolation schemes, which impose simplistic geometric assumptions that often misrepresent t

Read source article
arXiv cs.LGResearch

When Less is More: 8-bit Quantization Improves Continual Learning in Large Language Models

arXiv:2512.18934v2 Announce Type: replace Abstract: Catastrophic forgetting poses a fundamental challenge in continual learning, particularly when models are quantized for deployment efficiency. We systematically investigate the interplay between quantization precision (FP16, INT8, INT4) and replay buffer strategies in large language models, revealing unexpected dynamics. While FP16 achieves superior initial task performance (74.44% on NLU), we observe a striking inversion on subsequent tasks: q

Read source article
arXiv cs.LGResearch

Utilizing Earth Foundation Models to Enhance the Simulation Performance of Hydrological Models with AlphaEarth Embeddings

arXiv:2601.01558v2 Announce Type: replace Abstract: Predicting river flow in places without streamflow records is challenging because basins respond differently to climate, terrain, vegetation, and soils. Traditional basin attributes describe some of these differences, but they cannot fully represent the complexity of natural environments. This study examines whether AlphaEarth Foundation embeddings, which are learned from large collections of satellite images rather than designed by experts, of

Read source article
Hacker News Ask

Ask HN: What things might help me to become inference engineer?

I used to work as a full-stack engineer, but it started to burn me out, and I lost interest in building SaaS products. Instead, I began looking for areas that would challenge me, which led me to Infrastructure Engineering. Specifically, I chose the Inference field because I want to remain relevant in the age of AI. I would appreciate advice from AI Infra engineers or anyone with relevant experience on how I can become a strong Inference engineer Comments URL: https://news.ycombinator.com/item?id

Read source article
Machine Learning

SentryCode: Real-time Auditor + Honeytokens for AI Coding Agents [P]

<!-- SC_OFF --><div class="md"><p>In light of recent privacy concerns arising from local AI coding agents performing telemetry, environmental scanning, and hidden cue fingerprinting, I've open-sourced SentryCode—a kernel-level behavior auditing tool.</p> <p>It logs file/network/cue activity, uses honeypot tokens for zero-false-positive data breach detection, detects steganographically encrypted covert channels, provides tamper-proof audit logs, and supports policy enforcement. All functions run

Read source article
Product Hunt — The best new products, every day

PodcastorAI

<p> Your AI twin hosts your video podcast </p> <p> <a href="https://www.producthunt.com/products/podcastorai?utm_campaign=producthunt-atom-posts-feed&utm_medium=rss-feed&utm_source=producthunt-atom-posts-feed">Discussion</a> | <a href="https://www.producthunt.com/r/p/1185996?app_id=339">Link</a> </p>

Read source article
OpenClaw Commits

fix(fal): route grok-imagine and nano-banana-2-lite edits to correct …

<pre style='white-space:pre-wrap;width:81ex'>fix(fal): route grok-imagine and nano-banana-2-lite edits to correct endpoints (#98688) * fix(fal): route grok-imagine and nano-banana-2-lite edits to correct endpoints The fal image-generation provider appends '/image-to-image' to any model that isn't 'openai/gpt-image-*' or 'fal-ai/nano-banana-*' when reference images are supplied. That's wrong for two models fal serves: - `xai/grok-imagine-image`: fal 404s on '/image-to-image'. The real edit endpoi

Read source article
NVIDIA BlogResearch

NVIDIA Unlocks AI Compute at Scale, Inviting Capital Partners to Power the AI Infrastructure Buildout

As AI moves from model development to production inference, compute demand is accelerating and shifting toward continuously operating AI factories that generate tokens at scale. This shift requires access to large‑scale, multi‑tenant accelerated computing that can come online quickly, stay highly utilized and support the economics of token‑scale AI services. Emerging AI companies historically have […]

Read source article
NVIDIA Unlocks AI Compute at Scale, Inviting Capital Partners to Power the AI Infrastructure Buildout
Hacker News Ask

Ask HN: noticed how HN performs sentiment-analysis on everything posted here?

...and then punishes one for having any kind of negative sentiment? I never realized how severely his is being done on this site and I don't know how I feel about it - such 1984 vibes and its just growing and getting more widespread due to AI, no doubt. meh. nothing we the underclass can do about it I suppose. Comments URL: https://news.ycombinator.com/item?id=48756146 Points: 1 # Comments: 6

Read source article
ScienceAlert

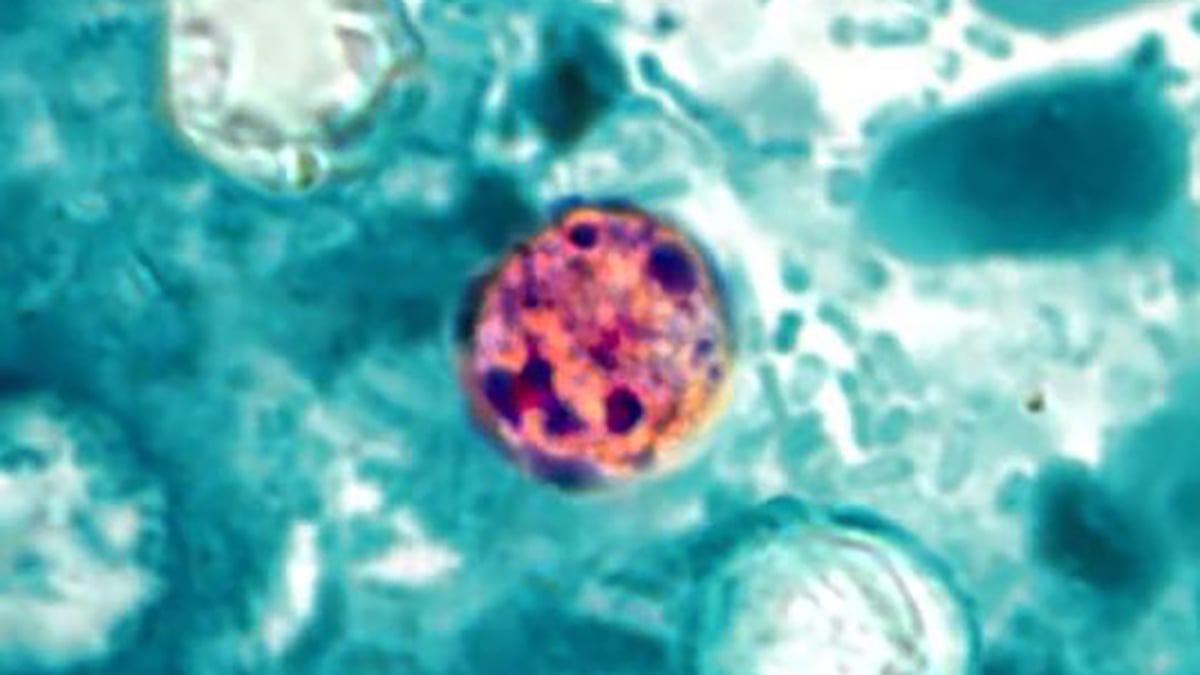
Explosive Diarrhea Is Surging Across The US Right Now

Researchers are hunting down the source of infection. ScienceAlert stories are written, fact-checked, and edited by humans, never generated by AI. Don't miss a story, subscribe here.

Read source article
Explosive Diarrhea Is Surging Across The US Right Now
Hacker News AILLMs

I'm Begging You to Leave Your AI Note-Taker at Home

Article URL: https://www.joanwestenberg.com/p/im-begging-you-to-leave-your-ai-note Comments URL: https://news.ycombinator.com/item?id=48755439 Points: 7 # Comments: 5

Read source article
Dev.to

How to Build a "Communication Profile" That Makes AI Write Exactly Like You

<p>You've tried this. You pasted a few emails into ChatGPT, told it to "write in my style," and got back something that reads like a polished LinkedIn post from a stranger. The vocabulary was close. The tone was off. The result felt like someone doing an impression of you at a party — recognizable, but wrong in ways you can't quite articulate.</p> <p>The problem isn't the model. The problem is that "mimic my style" is not an instruction. It's a wish. And language models don't grant wishes — they

Read source article
OpenClaw Commits

fix(memory-wiki): retry transient existing-page reads in wiki_apply a…

<pre style='white-space:pre-wrap;width:81ex'>fix(memory-wiki): retry transient existing-page reads in wiki_apply and chatgpt import (#98787) * fix(memory-wiki): retry transient existing-page reads in wiki_apply and chatgpt import A create_synthesis re-run and a ChatGPT conversations re-import swallowed every existing-page read error and treated the page as brand-new, so one transient read failure silently emptied the user's ## Notes block and dropped hand-added frontmatter. Route both reads thro

Read source article
Dev.to

11 Free No-Key APIs Your AI Agent Can Use to Read the Web

<p>An AI agent doesn't need a paid data vendor to read the web. These eleven REST APIs return real data with no API key and no credit card, just a plain HTTP GET. Every one was re-verified with a live curl on July 1, 2026, and the responses below are the actual output, trimmed for length, not paraphrased.</p> <p>I build tool layers for agents. The plumbing that lets an agent fetch a page, check a fact, or pull a live number before it answers. My last post here was an <a href="https://blog.spinov

Read source article