AiAnyTool - Best AI Tools Directory and Artificial Intelligence Software Hub Logo
Loading theme toggle
Real-Time Coverage

AI News Today

Live

31239 stories from 30+ sources, refreshed continuously.

arXiv cs.AIResearch

Anatomically Faithful but Temporally Blind: Auditing Attribution for Left-Ventricular Ejection-Fraction Estimation from Echocardiography

arXiv:2607.13738v1 Announce Type: cross Abstract: Background and Objective: Deep video models estimate left-ventricular ejection fraction (EF) from echocardiography with near-expert accuracy, and post-hoc attribution (Chefer relevance for transformers, Grad-CAM for CNNs) is increasingly used to certify that models "look at the right place." Yet whether these explanations are faithful both spatially and temporally is unaudited. Because EF is defined by the end-systolic (ES) and end-diastolic (ED)

Read source article
arXiv cs.AIResearch

MxGPS: Multiplex Graph Transformers for a Power Grid Foundation Model

arXiv:2607.13763v1 Announce Type: cross Abstract: Single-task fine-tuning of graph neural networks (GNNs) for power grid problems exhibits a systematic failure mode: models that achieve the lowest in-distribution error degrade the most under topology shift. We term this topology overfitting: the tendency of task-specific gradient signals to encode relational structure particular to the training topologies rather than the underlying physics, causing models to fail on unseen grids despite strong i

Read source article
arXiv cs.AIResearch

Kaleido: Algorithm-Hardware Co-Design for Video Diffusion Transformers by Exploiting Latent Space Correlations

arXiv:2607.13770v1 Announce Type: cross Abstract: Video diffusion transformers (vDiTs) generate high quality video but introduce extremely high compute cost due to the long diffusion timesteps and self attention computation. As diffusion timesteps are reduced, the computation cost of self attention becomes the dominant bottleneck. Existing acceleration approaches largely inherit sparse attention techniques from large language models, which fail to consider the unique spatiotemporal correlation o

Read source article
arXiv cs.AIResearch

Traffic-Aware Randomized Smoothing for LLM-Based Network Intrusion Detection

arXiv:2607.13801v1 Announce Type: cross Abstract: Large language model (LLM)-based intrusion detection systems (IDS) are increasingly studied for security monitoring, yet their robustness against feasible traffic manipulation remains largely empirical. We present Traffic-Aware Randomized Smoothing (TA-RS), a classifier-agnostic certified defense that injects Gaussian noise exclusively into the directly controllable (DC) subspace -- features a remote attacker can modify -- during both fine-tuning

Read source article
arXiv cs.AIResearch

Multimodal Assessment of Pancreatic Cancer Resectability Using Deep Learning

arXiv:2607.13826v1 Announce Type: cross Abstract: Accurate determination of pancreatic ductal adenocarcinoma (PDAC) resectability relies on evaluating how the tumor interacts with major peripancreatic vessels on CT imaging, yet expert assessment often shows substantial variability. We introduce a fully automated multimodal deep learning framework that jointly analyzes 3D contrast enhanced CT and structured clinical information to classify patients into the three National Comprehensive Cancer Net

Read source article
arXiv cs.AIResearch

NodeImport: Imbalanced Node Classification with Node Importance Assessment

arXiv:2607.13837v1 Announce Type: cross Abstract: In real-world applications, node classification on graphs often faces the challenge of class imbalance, where majority classes dominate training, resulting in biased model performance. Traditional GNNs often struggle in such scenarios, as they tend to overfit to majority classes while underrepresenting minority classes. Existing solutions, which either prioritize nodes based on class size or synthesize new nodes for minority classes, often fall s

Read source article
arXiv cs.AIResearch

AI-Augmented Human Resource Management? Insights from German companies

arXiv:2607.13839v1 Announce Type: cross Abstract: This study examines the integration of AI into Human Resource Management in German companies. We ask if and how AI-based technologies are \enquote{augmenting} human resource management. Organisations employ generative AI or predictive analytics to transform traditional human resource functions, to streamline routine tasks and to reallocate resources toward strategic, people-centred activities. Our findings from interviews and group discussions an

Read source article
arXiv cs.AIResearch

Unleashing Multimodal Large Language Models for Training-free HOI Detection in the Wild

arXiv:2607.13881v1 Announce Type: cross Abstract: Human-object interaction detection (HOID) has traditionally been formulated as a supervised detection problem over predefined interaction categories. While such paradigms achieve strong performance on closed-set benchmarks, they fundamentally entangle interaction understanding with dataset-specific supervision, limiting their ability to generalize to open-world and compositional scenarios. Recent HOI detectors attempt to leverage MLLMs through pr

Read source article
arXiv cs.CVResearch

Beyond Description: Cognitively Benchmarking Fine-Grained Action for Embodied Agents

arXiv:2511.18685v4 Announce Type: replace Abstract: Multimodal Large Language Models (MLLMs) show promising results as decision-making engines for embodied agents operating in complex, physical environments. However, existing benchmarks often prioritize high-level planning or spatial reasoning, leaving the fine-grained action intelligence required for embodied physical interaction underexplored. To address this gap, we introduce CFG-Bench, a new benchmark designed to systematically evaluate this

Read source article
arXiv cs.CVResearch

Track and Caption Any Motion: Open-Vocabulary Spatiotemporal Captioning via Trajectory-Conditioned Generation

arXiv:2512.10607v2 Announce Type: replace Abstract: We present TCAM (Track and Caption Any Motion), a generative framework that watches a video and with no text query and no region prompt decides what is moving, describes each motion in open vocabulary, locates it in time, and points to the exact trajectories that carry it. Two mature lines of work make this possible yet leave it unsolved: dense point trackers follow pixels with sub-object precision but emit no language, while video-language mod

Read source article
arXiv cs.CVResearch

GeCo: Evaluating Geometric Consistency for Video Generation via Motion and Structure

arXiv:2512.22274v3 Announce Type: replace Abstract: We introduce GeCo, a geometry-grounded metric for jointly detecting geometric deformation and occlusion-inconsistency artifacts in static scenes. By fusing residual motion and depth priors, GeCo produces interpretable, dense consistency maps that reveal these artifacts. We use GeCo to systematically benchmark recent video generation models, uncovering common failure modes, and further employ it as a training-free guidance loss to reduce deforma

Read source article
arXiv cs.CVResearch

Attentive multilayer fusion for vision transformers

arXiv:2601.09322v2 Announce Type: replace Abstract: With the rise of large-scale foundation models, efficiently adapting them to downstream tasks remains a central challenge. Linear probing, which freezes the backbone and trains a lightweight head, is computationally efficient but often restricted to last-layer representations. We show that task-relevant information is distributed across the network hierarchy rather than encoded solely in the last layers. To leverage this distribution of informa

Read source article
arXiv cs.CVResearch

When Vision Overrides Language: Evaluating and Mitigating Counterfactual Failures in VLAs

arXiv:2602.17659v2 Announce Type: replace Abstract: Vision-Language-Action models (VLAs) promise to ground language instructions in robot control, yet in practice often fail to faithfully follow language. When presented with instructions that lack strong scene-specific supervision, VLAs suffer from counterfactual failures: they act based on vision shortcuts induced by dataset biases, repeatedly executing well-learned behaviors and selecting objects frequently seen during training regardless of l

Read source article
arXiv cs.CVResearch

Low-latency Event-based Object Detection with Spatially-Sparse Linear Attention

arXiv:2603.06228v2 Announce Type: replace Abstract: Event cameras provide sequential visual data with spatial sparsity and high temporal resolution, making them attractive for low-latency object detection. Existing asynchronous event-based neural networks exploit this low-latency advantage by updating predictions event by event, but still suffer from two bottlenecks: recurrent architectures are difficult to train efficiently on long sequences, and improving accuracy often increases per-event com

Read source article
arXiv cs.CVResearch

OccTrack360: 4D Panoptic Occupancy Tracking from Surround-View Fisheye Cameras

arXiv:2603.08521v2 Announce Type: replace Abstract: Understanding dynamic 3D environments in a spatially continuous and temporally consistent manner is fundamental for robotics and autonomous driving. While recent advances in occupancy prediction provide a unified representation of scene geometry and semantics, progress in 4D panoptic occupancy tracking remains limited by the lack of benchmarks that support surround-view fisheye sensing, long temporal sequences, and instance-level voxel tracking

Read source article
arXiv cs.CVResearch

NanoGS: Training-Free Gaussian Splat Simplification

arXiv:2603.16103v2 Announce Type: replace Abstract: 3D Gaussian Splat (3DGS) enables high-fidelity, real-time novel view synthesis by representing scenes with large sets of anisotropic primitives, but often requires millions of Splats, incurring significant storage and transmission costs. Most existing compression methods rely on GPU-intensive post-training optimization with calibrated images, limiting practical deployment. We introduce \textbf{NanoGS}, a training-free and lightweight framework

Read source article
arXiv cs.CVResearch

Evaluating Vision Foundation Models for Pixel and Object Classification in Microscopy

arXiv:2603.19802v2 Announce Type: replace Abstract: Deep learning underlies most modern approaches and tools in computer vision, including biomedical imaging. However, for interactive semantic segmentation (often called pixel classification in this context) and interactive object-level classification (object classification), feature-based shallow learning remains widely used. This is due to the diversity of data in this domain, the lack of large pretraining datasets, and the need for computation

Read source article
arXiv cs.CVResearch

Holistic Optimal Label Selection for Robust Prompt Learning under Partial Labels

arXiv:2604.06614v2 Announce Type: replace Abstract: Prompt learning has gained significant attention as a parameter-efficient approach for adapting large pre-trained vision-language models to downstream tasks. However, when only partial labels are available, its performance is often limited by label ambiguity and insufficient supervisory information. To address this issue, we propose Holistic Optimal Label Selection (HopS), leveraging the generalization ability of pre-trained feature encoders th

Read source article
arXiv cs.CVResearch

When W4A4 Breaks Camouflaged Object Detection: Token-Group Dual-Constraint Activation Quantization

arXiv:2604.16855v2 Announce Type: replace Abstract: Camouflaged object detection (COD) segments objects that intentionally blend with the background, so predictions depend on subtle texture and boundary cues. COD is often needed under tight on-device memory and latency budgets, making low-bit inference highly desirable. However, COD is unusually hard to quantize aggressively. We study post-training W4A4 quantization of Transformer-based COD and find a task-specific cliff: heavy-tailed background

Read source article
arXiv cs.CVResearch

Vision Transformers and Convolutional Neural Networks for Land Use Scene Classification

arXiv:2605.21268v3 Announce Type: replace Abstract: Land Use Scene Classification (LUSC) from remote sensing imagery plays a critical role in environmental monitoring, urban planning, and sustainable resource management. In recent years, deep learning methods have significantly advanced the state of the art, with Convolutional Neural Networks (CNNs) dominating the field because of their strong ability to capture local spatial features. However, the emergence of Vision Transformers (ViTs) has int

Read source article
arXiv cs.CVResearch

Inverting the Streaming-Diffusion Bottleneck: Video-Rate MLLM-Conditioned Edit Diffusion on a Consumer GPU

arXiv:2606.05981v2 Announce Type: replace Abstract: Aggressive distillation of the diffusion U-Net inverts the per-frame bottleneck of real-time text-to-image pipelines: once the denoiser is a 4-step or 1-step distilled student, the text encoder becomes the critical path. This inversion is most acute in vision-aware edit diffusion, where the encoder is a multimodal large language model (MLLM). We study a 0.39B distilled edit U-Net paired with a 2.13B MLLM text encoder (Qwen3-VL) and present a st

Read source article
arXiv cs.CVResearch

Your Data Manifold is Secretly a Reward Model: Shell-LCC for Text-to-Video Generation

arXiv:2606.30248v2 Announce Type: replace Abstract: Recent text-to-video (T2V) diffusion models rely heavily on auxiliary reward signals (e.g., via reward models or DPO) to align generated content with human aesthetics and improve realism. These signals, however, incur substantial computational overhead, require costly human annotations, and often yield limited improvement in fine-grained local details. In this paper, we argue that your data manifold is secretly a reward model. By explicitly mod

Read source article
arXiv cs.LGResearch

RF-Informed Graph Neural Networks for Accurate and Data-Efficient Circuit Performance Prediction

arXiv:2508.16403v3 Announce Type: replace Abstract: Accurately predicting the performance of active radio frequency (RF) circuits is essential for modern wireless systems but remains challenging due to highly nonlinear behavior and the high computational cost of traditional simulation tools. Existing machine learning (ML) surrogates often require large datasets to generalize across various topologies or are not accurate on held-out circuits. This work presents a lightweight, data-efficient, and

Read source article
arXiv cs.LGResearch

Computation-aware Energy-harvesting Federated Learning with Pipelined Cyclic Scheduling

arXiv:2511.11949v2 Announce Type: replace Abstract: Federated learning (FL) is a powerful paradigm for distributed learning, but increasing model complexity leads to significant energy consumption from client-side computations for local training. This challenge is critical in energy-harvesting FL (EHFL) systems, where the participation availability of each device fluctuates because of limited energy. To address this, we propose PipeCycle, a battery-aware distributed learning framework that organ

Read source article
arXiv cs.LGResearch

Survival Dynamics of Neural and Programmatic Policies in Evolutionary Reinforcement Learning

arXiv:2601.04365v2 Announce Type: replace Abstract: In evolutionary reinforcement learning tasks (ERL), agent policies are often encoded as small artificial neural networks (NERL). Such representations lack explicit modular structure, limiting behavioral interpretation. We investigate whether programmatic policies (PERL), implemented as soft, differentiable decision lists (SDDL), can match the performance of NERL. To support reproducible evaluation, we provide the first fully specified and open-

Read source article
arXiv cs.LGResearch

Overcoming the Modality Gap in Context-Aided Forecasting

arXiv:2603.12451v4 Announce Type: replace Abstract: Context-aided forecasting (CAF) holds promise for integrating domain knowledge and forward-looking information, enabling AI systems to surpass traditional statistical methods. However, recent empirical studies reveal a puzzling gap: multimodal models often fail to outperform their unimodal counterparts. We hypothesize that this underperformance stems from poor context quality in existing datasets, as verification is challenging. To address thes

Read source article
arXiv cs.LGResearch

A Generalised Exponentiated Gradient Approach to Enhance Fairness in Binary and Multi-class Classification Tasks

arXiv:2603.21393v2 Announce Type: replace Abstract: The widespread use of AI and ML models in sensitive areas raises significant concerns about fairness. While the research community has introduced various methods for bias mitigation in binary classification tasks, the issue remains under-explored in multi-class classification settings. To address this limitation, in this paper, we first formulate the problem of fair learning in multi-class classification as a multi-objective problem between eff

Read source article
arXiv cs.LGResearch

Test-Time Learning with an Evolving Library

arXiv:2605.14477v2 Announce Type: replace Abstract: We introduce EvoLib, a test-time learning framework that enables large language models to accumulate, reuse, and evolve knowledge across problem instances without parameter updates or external supervision. Instead of adapting model parameters, our approach maintains a shared library of knowledge abstractions, including modular skills and reflective insights, automatically extracted from the model's own inference trajectories. To support continu

Read source article
arXiv cs.LGResearch

Foundation Models for Credit Risk Prediction: A Game Changer?

arXiv:2605.18147v2 Announce Type: replace Abstract: Predictive models play a pivotal role in credit risk management, guiding critical decisions through accurate estimation of default probabilities and losses. Extensive research has introduced new modeling techniques, complemented by large-scale benchmarking studies consolidating the state-of-the-art. Today, quasi-standards such as gradient-boosting models paired with SHAP explainers have emerged, yet continuous improvement of risk models remains

Read source article
arXiv cs.LGResearch

AvAtar: Learning to Align via Active Optimal Transport

arXiv:2605.24395v2 Announce Type: replace Abstract: Alignment plays a fundamental role in many machine learning problems, such as multi-network analysis, multimodal learning, and point cloud registration. Recent works increasingly leverage optimal transport (OT) for distributional alignment, whose effectiveness largely depends on sparse supervision that is hard or costly to obtain in practice. Existing works, however, largely overlook how to actively acquire high-quality supervision to improve t

Read source article
arXiv cs.LGResearch

Variational Inference for Evidential Deep Learning

arXiv:2605.26477v2 Announce Type: replace Abstract: While Deep Neural Networks (DNNs) achieve remarkable performance, their tendency to produce overconfident predictions. Evidential Deep Learning (EDL) mitigates this by formulating predictions as a Dirichlet distribution over class probabilities to explicitly quantify epistemic uncertainty. However, we found that the conventional EDL suffers from two fundamental limitations: a Kullback-Leibler (KL) penalty that only suppresses the evidence of ne

Read source article
arXiv cs.LGResearch

Algorithmic Recourse of In-Context Learning for Tabular Data

arXiv:2605.31272v2 Announce Type: replace Abstract: As predictive models are increasingly deployed in high-stakes settings such as credit approval, there is a growing need for post-hoc methods that provide recourse to affected individuals. Many such models operate on tabular data, where features correspond to real-world attributes. Recently, in-context learning (ICL) has enabled large language models to perform tabular prediction by conditioning on labeled examples at inference time, without exp

Read source article
arXiv cs.LGResearch

New universal operator approximation theorem for encoder-decoder architectures

arXiv:2503.24092v2 Announce Type: replace-cross Abstract: Motivated by the rapidly growing field of mathematics for operator approximation with neural networks, we present a novel universal operator approximation theorem for broad classes of encoder-decoder architectures and a wide range of input and output spaces. In this study, we focus on the approximation of continuous operators between infinite-dimensional normed or metric spaces in the topology of uniform convergence on compact sets. Unlik

Read source article
Hacker News: Show HN

Show HN: Forall – An AI coding agent that generates machine-checkable proofs

We've been working on an open-source coding agent that generates code alongside machine-checkable proofs. We'd love feedback from the HN community, especially from people interested in formal verification, Lean, Dafny, or AI coding agents. Currently, only 3 langauges can be verified. Comments URL: https://news.ycombinator.com/item?id=48929654 Points: 5 # Comments: 0

Read source article
The Guardian AIBusiness

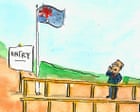
Will the new AI roadmap keep the tech giants in line? | Fiona Katauskas

<p>Or will they forge a path of their own?</p><ul><li><p>See more of <a href="https://www.theguardian.com/profile/fiona-katauskas">Fiona Katauskas’s cartoons here</a></p></li></ul> <a href="https://www.theguardian.com/commentisfree/picture/2026/jul/16/will-the-new-ai-roadmap-keep-the-tech-giants-in-line">Continue reading...</a>

Read source article
Will the new AI roadmap keep the tech giants in line? | Fiona Katauskas