
Moz
The New (AI) SEO Playbook — Whiteboard Friday
Discover how AI is changing the top-of-funnel SEO playbook. Learn four new strategies to adapt to AI search, build third-party citations, and measure success effectively.
Read source article
Discover how AI is changing the top-of-funnel SEO playbook. Learn four new strategies to adapt to AI search, build third-party citations, and measure success effectively.
Redis shipped seven security releases on July 23 after researchers published authenticated RCE PoCs for stock Redis 6.2.22, 7.4.9, 8.6.4, and 8.8.0. All four chains require RESTORE. The Streams chains also need EVAL and XGROUP; the 8.8.0 chain needs EVAL and the bundled RedisBloom module. Redis says the underlying memory flaws may lead to remote code execution. Redis 6.2.23, 7.2.15, and 7.4.10

Chipzilla changes PC biz name to reflect belief edge and robots could be as valuable one day
Article URL: https://platform.claude.com/cookbook/ Comments URL: https://news.ycombinator.com/item?id=49031409 Points: 326 # Comments: 163
The science behind that infuriating tickle. ScienceAlert stories are written, fact-checked, and edited by humans, never generated by AI. Don't miss a story, subscribe here.
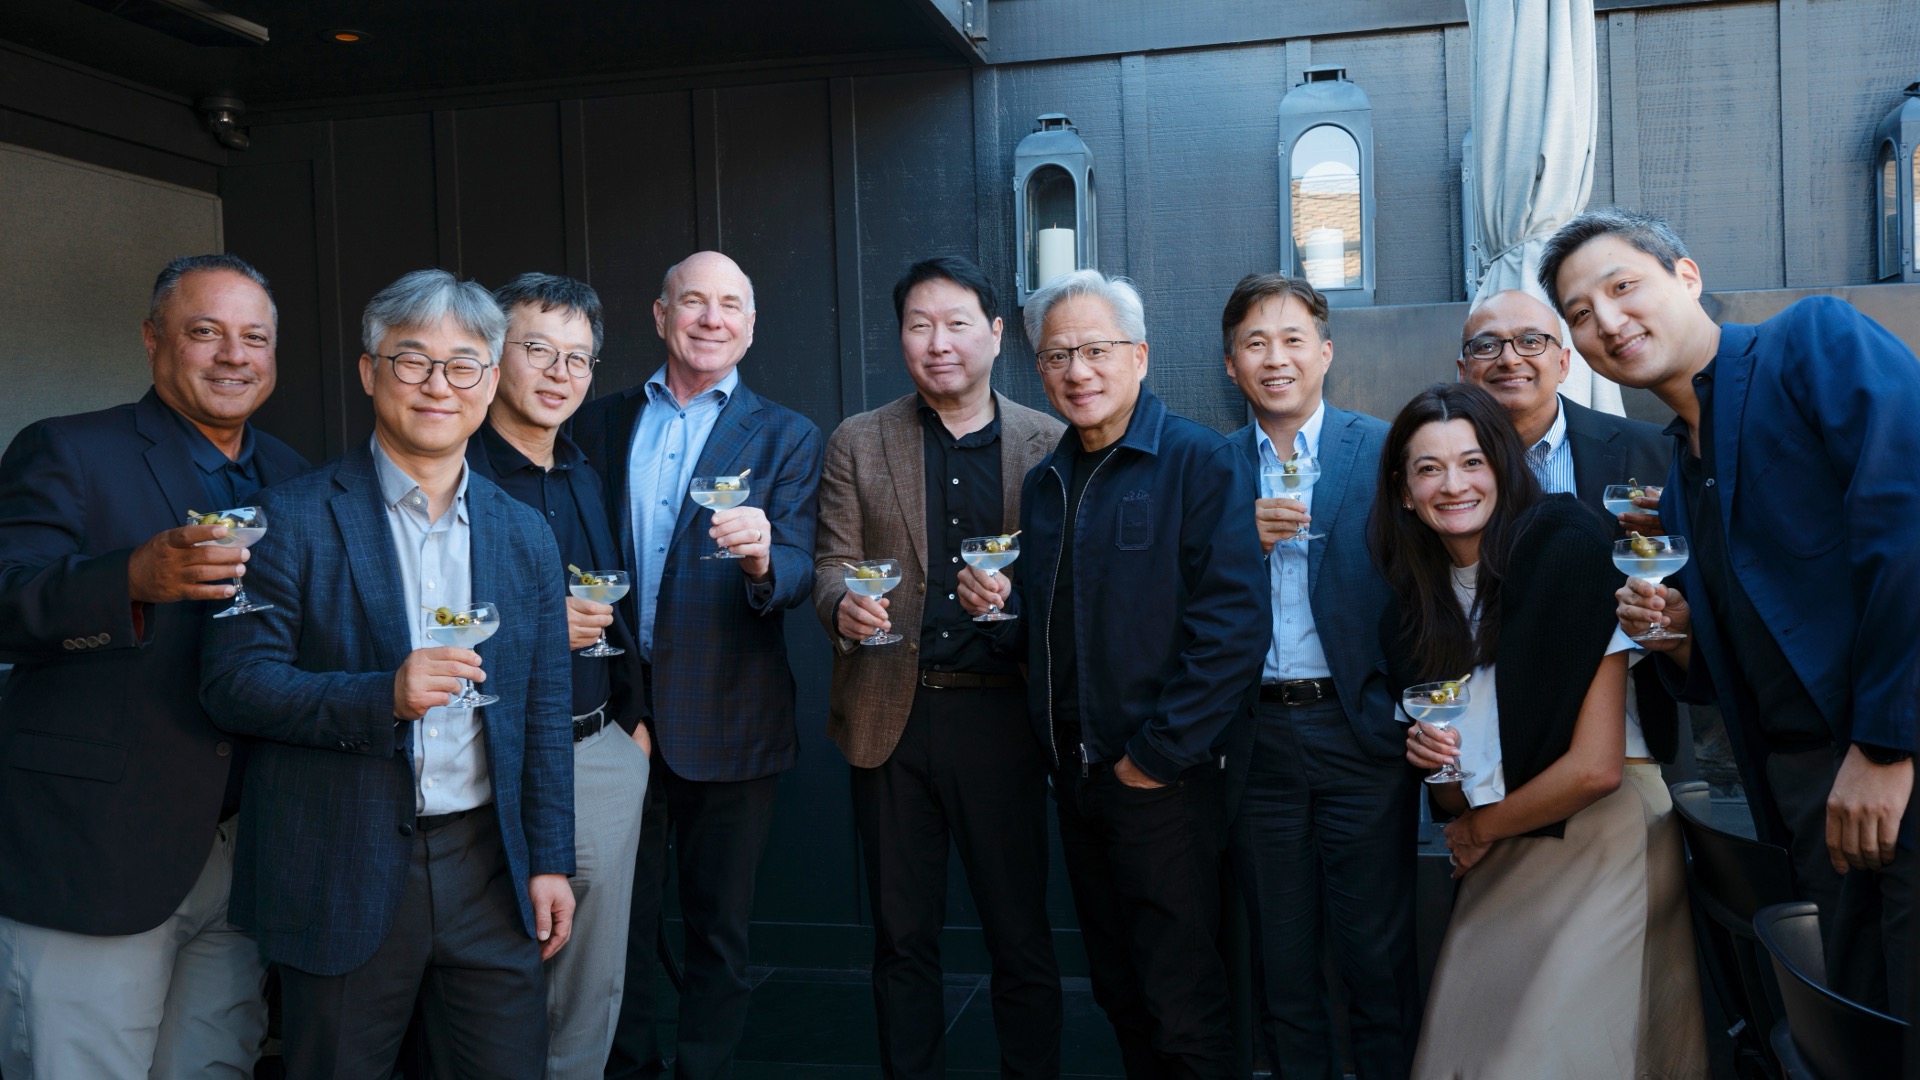
At this week’s AI Summit in San Francisco, South Korean President Jae Myung Lee and some of the country’s top business leaders and researchers are meeting with NVIDIA and ecosystem partners to chart Korea’s AI progress. Building on NVIDIA founder and CEO Jensen Huang’s visit to Korea last month, this week’s discussions and announcements advance […]
Hackers, We wanted to share our newly-added recurring Free tier for cloro.dev, the leading AI UI scraping platform in the world. We extract structured data from ChatGPT, Perplexity, Grok, Gemini, Google Search, Google News, Copilot, and AI Overview through one API, with low latency across any country. We have recently crossed 200+ customers, most of them the large Enterprises behind GEO and SEO. From now on, every user gets 500 free credits every month, which is great for hobby projects you may
arXiv:2607.20452v1 Announce Type: new Abstract: Modern software quality assurance demands intelligent, autonomous systems capable of adaptive decision-making across distributed cloud environments. This paper presents AINTMA (Agentic Intelligent Test Management Architecture), a multi-agent agentic AI system that transforms traditional test management into an autonomous quality intelligence ecosystem. AINTMA deploys six specialized AI agents (Test Discovery, Risk Assessment, Reinforcement Learning
arXiv:2607.20462v1 Announce Type: new Abstract: Large language models (LLMs) are increasingly integrated into clinical workflows, stressing the need for reliable traceability of model-generated output with watermarking. Yet, most watermarks are evaluated on general-purpose benchmarks, leaving domains like medicine, where small token-level perturbations can result in significant semantic changes, underexplored. In this work, we present the first rigorous study of how LLM watermarks affect medical
arXiv:2607.20463v1 Announce Type: new Abstract: This paper presents an AI-driven browser extension that identifies clickbait to help users avoid misleading Internet articles. Moving beyond traditional detection, the application employs a hybrid machine learning architecture that combines transformer-based embeddings with linguistically motivated features and a custom "baitness" score. After evaluating various natural language processing techniques -- from classic vectorizers to large language mo
arXiv:2607.20466v1 Announce Type: new Abstract: Rigorous benchmarks have driven progress in autonomous GPU kernel performance optimization by establishing a shared target to hillclimb on, but no equivalent exists for TPUs. We present JAXBench, a TPU-native benchmark suite for AI-generated kernel optimization on Google Cloud TPUs. JAXBench comprises 50 JAX workloads that are both relevant and provide headroom for optimization. We extract 17 production ML operators from architectures in the public
arXiv:2607.20467v1 Announce Type: new Abstract: While parallel decoding is central to the efficiency of Diffusion Large Language Models (dLLMs), current strategies are often hindered by overly conservative confidence thresholds. These thresholds, necessitated by the Joint Probability Dependence Error (JPDE), result in redundant denoising iterations and suboptimal inference speeds. To overcome this, we propose DC-Leap, a training-free framework that enables reliable acceleration of dLLMs in the m
arXiv:2607.20468v1 Announce Type: new Abstract: AI agents are increasingly used to automate research and development tasks, yet existing benchmarks typically evaluate them on prescribed workflows or narrow action spaces. Even nominally open-ended tasks can often be solved by retrieving a well-known recipe and tuning a few hyperparameters, making it unclear whether strong results reflect genuine optimization or memorized solutions. We introduce InferenceBench, where an agent must deploy an OpenAI
arXiv:2607.20469v1 Announce Type: new Abstract: Large language models (LLMs) handle many tasks with one set of parameters, but under KV-cached inference it is unclear what task-general structure, if any, is used at decode time rather than during prefill. We propose DecodeShare, a protocol that identifies a low-dimensional subspace consistently shared across tasks in decode-time hidden states, and then tests its causal role by removing that subspace only during decoding. In our experiments, distu
arXiv:2607.20470v1 Announce Type: new Abstract: Enhancing the task-specific capabilities of Large Language Models (LLMs) primarily requires substantial instruction-tuning datasets. However, the sheer volume of such data imposes a considerable annotation cost, and a lack of optimization methods for tailoring LLMs to specific tasks. To address the above issues, we propose a \textbf{Plan}ning framework for constructing \textbf{E}xtractive-based LLMs called \textbf{PlanE}, which includes data decomp
arXiv:2607.20471v1 Announce Type: new Abstract: Personalization, the act of varying a message to induce action from a specific receiver while keeping sender, channel, and time fixed, has a long tradition in psychology and marketing as a two-party problem in which sender and receiver have independent objectives. Large language models remove the bounded-inventory constraint of classical retrieval-and-ranking approaches by generating a continuum of message variants conditioned on inferred receiver
arXiv:2607.20472v1 Announce Type: new Abstract: When a user asks a language model something harmful, is it a genuine attack or a misunderstood but well-meaning question? This ambiguity is one of the central challenges of LLM safety. A model that assumes the worst harms legitimate users; one that assumes the best is easily exploited. The problem is compounded in multi-turn dialogue, where an attacker's true intent may only reveal itself gradually across many exchanges, yet existing safety framewo
arXiv:2607.20473v1 Announce Type: new Abstract: Large language models (LLMs) are increasingly released as open-weight models with safeguards against harmful requests. Nevertheless, sentence completion remains vulnerable to incomplete harmful prompts. In this work, we formalize this phenomenon as incomplete prompt jailbreaks (IPJ) and provide a systematic empirical characterization of when and how incomplete prompts elicit harmful continuations. We analyze diverse attractor types associated with
arXiv:2607.20474v1 Announce Type: new Abstract: Natural language interfaces can greatly benefit the accessibility and usability of optimization modeling, and recent advances in large language models (LLMs) show promise in automatically translating textual problem descriptions into executable solver formulations. However, a key challenge for existing approaches is to ensure that the inferred formulation correctly implements the intended task, even if it may execute without errors. We introduce Ve
arXiv:2607.20475v1 Announce Type: new Abstract: Sampling in LLM inference comprises a combinatorial set of logit processing, token selection, and verification operations for speculative decoding. However, existing implementations either accelerate only subsets of this pipeline, rely on multiple kernel launches, or assume homogeneous sampling behavior across a batch, limiting support for dynamic serving workloads and preventing efficient CUDA Graph execution. We present $\textbf{SonicSampler}$, a
arXiv:2607.20476v1 Announce Type: new Abstract: We present an empirical benchmark evaluating how five large language models assess multisensor physical hazard data. Testing 60 scenarios across three categories - multi-sensor joint assessment, response proportionality, and pattern disambiguation - with 1,800 API calls at temperature 0.0, we find that all tested models consistently produced no precautionary warning signal across the tested scenarios where multiple sensors are simultaneously elevat
arXiv:2607.20477v1 Announce Type: new Abstract: {\em Text-Attributed Graphs} (TAGs) have emerged as an expressive data model for integrating graph topology with rich textual semantics. Existing representation learning methods over TAGs suffer from severe scalability bottlenecks, particularly together with {\em Large Language Models} (LLMs). While data distillation offers a promising data-centric solution, existing methods fail to capture the complex interplay between graph and text modalities, s
arXiv:2607.20479v1 Announce Type: new Abstract: Training probes to detect deceptive outputs from large language models is still an open problem. Recent work has demonstrated that detection probes fail especially in out-of-domain scenarios -- training on one type of lie does not transfer well to deception scenarios involving other types of lies. In this work, we conduct a systematic study on how various factors impact detection performance: representation depth, probe expressivity, sparse feature
arXiv:2607.20480v1 Announce Type: new Abstract: Accurate distribution system topology is essential for outage localization, voltage analytics, and operation of distribution grids, yet maintaining reliable connectivity records remains challenging in practice due to heterogeneous and imperfect utility data. Existing topology identification methods often rely primarily on electrical similarity or spatial records alone, which become unreliable in dense feeders and under inconsistent metadata conditi
arXiv:2607.20481v1 Announce Type: new Abstract: Local-cloud collaboration is a practical way to deploy large language models under resource constraints, but existing methods often rely on trained routers or collaboration-aware finetuning that tie routing behavior to a particular operating regime. In this work, we show that such training may be unnecessary: the local model's own inference-time agreement across sampled responses already provides a strong signal for deciding when to trust local exe
arXiv:2607.20482v1 Announce Type: new Abstract: Recent advances in large language models have enabled web agents to autonomously execute complex tasks. In practice, users frequently provide underspecified instructions, requiring agents to infer the missing context from their raw browsing histories. Existing benchmarks fail to capture this form of personalization, as they either restrict tasks to fully explicit prompts or abstract web interaction history into simplified forms. To bridge this gap,
arXiv:2607.20483v1 Announce Type: new Abstract: Constraining the generation of autoregressive large language models (LLMs) is an important component of integrating language models into formal systems. In the generation of code and data for tasks like program synthesis, ensuring that language models produce syntactically valid output is a prerequisite for processing such output. These languages (such as SQL or JSON) are often designed as $LR(k)$ context-free grammars. By distilling the LLM to a t
arXiv:2607.20642v1 Announce Type: new Abstract: Computer aided design (CAD) is ubiquitous: virtually any modern object was designed using editable CAD tools. However, with the shortage of available CAD datasets in its native editable and parametric format, boundary representation (B-Rep), it is ever more important to develop data-efficient methods for this domain. We present a new self-supervised pretraining task, Masked Topology Modeling (MTM), that leverages the face-adjacency graph, an induce
arXiv:2607.20660v1 Announce Type: new Abstract: Recent 3D generative models produce high-quality geometry from a single image using large-scale priors and diffusion architectures. However, they assume complete visibility and single-view inputs, limiting applicability in multi-view, occluded, or editing scenarios. Although prior works address these challenges individually, they lack a unified framework for controllable 3D completion under diverse conditioning signals. We present Axolotl3D, a mult
arXiv:2607.20670v1 Announce Type: new Abstract: Modeling continuous object deformation is important for many computer vision and robotics tasks, such as manipulation and simulation. Existing approaches rely on learning-based methods or physics simulators to model shape deformations. However, these approaches either use discrete time steps or are too computationally intensive for real-time applications. We present ODeform, a novel extension of Neural Ordinary Differential Equations to continuous
arXiv:2607.20789v1 Announce Type: new Abstract: Recent advances in 3D scene editing have leveraged iterative diffusion models to update input views. However, this process is computationally expensive and struggles to produce sharp details. Meanwhile, ``hallucination drift'' frequently introduces multi-view inconsistencies, leading to structural artifacts when rendering novel viewpoints. To address this problem, we present 3D-GIMP (3D Gaussian Inpainting Meets Patch Matching), a novel hybrid para
arXiv:2607.20819v1 Announce Type: new Abstract: Stress is a dynamic process characterized by significant individual variability in facial expression. Traditional architectures, such as Recurrent Neural Networks (RNNs) and Convolutional Neural Networks (CNNs), often overlook person-specific baselines or lack the representational capacity to model the non-linear temporal progression of distress due to sequential bottlenecks and rigid grid-based constraints. Furthermore, many deep learning models l
arXiv:2607.20866v1 Announce Type: new Abstract: Generating realistic interior furniture layouts that strictly adhere to architectural constraints (e.g., walls, doors, and windows) remains a fundamental challenge in automated spatial design. Existing approaches, primarily based on one-shot generation using diffusion models or Large Language Models (LLMs), lack explicit mechanisms for intermediate geometric constraint verification, often resulting in structural collisions and functionally infeasib
arXiv:2607.20868v1 Announce Type: new Abstract: Multimodal Large Language Models (MLLMs) have achieved remarkable success across diverse expert-level tasks, but they still struggle with fundamental abilities that humans naturally develop through continuous observation of the real world, such as spatial perception and dynamic reasoning. Recent studies have recognized this gap and introduced dedicated benchmarks to evaluate the spatial-temporal capabilities of MLLMs. However, existing benchmarks m
arXiv:2607.20874v1 Announce Type: new Abstract: Training deep learning models with freely available web images can reduce their dependence on costly manual annotations. Although webly supervised learning has been widely studied for single-label recognition, its multi-label counterpart remains underexplored, partly due to the lack of unified benchmarks and fair comparison protocols. To address this gap, we construct a benchmark for webly supervised multi-label recognition (WS-MLR), including Web-
arXiv:2607.20900v1 Announce Type: new Abstract: With the increasing diversity of spoofing attacks, there is a growing demand for unified Face Anti-Spoofing (FAS) models capable of detecting both physical and digital threats. While existing Vision-Language Models (VLMs) demonstrate high generalization in this context, they heavily rely on complex multimodal fusion and external text encoders. In this paper, we propose DINO-VPT, a lightweight, vision-only framework leveraging hierarchical visual pr
arXiv:2607.20922v1 Announce Type: new Abstract: We propose FA-LAM, a Focus-Aware Large Avatar Model for one-shot animatable Gaussian head creation, while simultaneously enabling static 3D and dynamic 4D full-head recovery. The core of our method lies in a thorough analysis of the attention mechanisms and the entangled reconstruction and animation training pipeline adopted by prior state-of-the-art approaches. Our analysis identifies two main factors that compromise the quality of 3D full-head ge
arXiv:2607.20924v1 Announce Type: new Abstract: Makeup-transfer applies the reference makeup to the source face while preserving the source identity. Despite advances in full-face editing by diffusion-based methods, strong regional controllability, makeup fidelity, and identity preservation remain challenging. The reasons are (i) pixel-to-attention misalignment that causes spillover into non-target areas and weakens regional control; (ii) unclear transfer/preservation concept separation under tw
arXiv:2607.20940v1 Announce Type: new Abstract: Streaming video diffusion models have made substantial progress toward interactive and dynamic world simulation, but the nested autoregressive and denoising loops of conventional next-frame generation hinder real-time deployment. Recent rolling-window methods pipeline denoising across multiple consecutive frames at different noise levels, improving throughput and long-horizon stability. However, they tokenize every state at the same fine spatial gr
arXiv:2607.20947v1 Announce Type: new Abstract: In intelligent transportation systems, roadside 3D object detection provides wide-area perception crucial for traffic understanding, cooperative early warning, and safe autonomous driving. However, existing methods suffer from high sensitivity to camera extrinsics; even slight deviations (whether manifesting as transient jitter or persistent drift) can be significantly amplified by projective geometry. This cascade results in severe feature misalig