AiAnyTool - Best AI Tools Directory and Artificial Intelligence Software Hub Logo
Loading theme toggle
Real-Time Coverage

AI News Today

Live

38678 stories from 30+ sources, refreshed continuously.

ScienceAlert

Physicists Built a Black Hole in a Lab. Then It Swallowed Sound.

Black holes famously trap light. A new acoustic device borrows the idea to swallow sound. (Yukterez/Wikimedia Commons, CC BY-SA 4.0) Gulp! ScienceAlert stories are written, fact-checked, and edited by humans, never generated by AI. Don't miss a story, subscribe here.

Read source article
Physicists Built a Black Hole in a Lab. Then It Swallowed Sound.
MarkTechPostResearch

Top 12 AI Live Translation Tools in 2026: Latency, Languages, Pricing

We checked 12 AI live translation tools, including Palabra.ai, Google Live Translate, DeepL Voice, Teams Interpreter and Wordly, against official pages for languages, latency, platforms and pricing. The post Top 12 AI Live Translation Tools in 2026: Latency, Languages, Pricing appeared first on MarkTechPost .

Read source article
Product HuntTools

Xiryn

<p> The open-source personal agent that runs on your computer </p> <p> <a href="https://www.producthunt.com/products/xiryn?utm_campaign=producthunt-atom-posts-feed&utm_medium=rss-feed&utm_source=producthunt-atom-posts-feed">Discussion</a> | <a href="https://www.producthunt.com/r/p/1277481?app_id=339">Link</a> </p>

Read source article
The Guardian AIBusiness

AI less regulated than milk, Microsoft president says in warning over safety

<p>Brad Smith adds to calls for tougher rules for AI, including ‘kill switches’ and legal obligation to victims of rogue agents</p><ul><li><p><a href="https://www.theguardian.com/business/live/2026/oct/12/uk-growth-inflation-pressures-oil-price-sveriges-riksbank-nobel-prize-economic-sciences-awarded-latest-news-updates">Business live – latest updates</a></p></li></ul><p>Artificial intelligence is less regulated than milk and washing machines, the president of Microsoft has said, as the tech indu

Read source article
AI less regulated than milk, Microsoft president says in warning over safety
r/MachineLearningResearch

Constrained Learning for Scientific Modelling (Paris NeurIPS pre-event) [N]

<!-- SC_OFF --><div class="md"><p>CALL FOR CONTRIBUTIONS </p> <p>CL4SM session at ELLIs UnConference, a NeurIPS Paris pre-event: <a href="https://badulion.github.io/cl4sm%5C_2026/">https://badulion.github.io/cl4sm\_2026/</a></p> <p>Machine learning models of scientific and engineering systems can fit the data well and still be physically wrong: they create or destroy mass and energy, produce negative concentrations, violate boundary conditions, or drift into unphysical regimes. CL4SM promotes di

Read source article
r/MachineLearningResearch

Compressed a RoBERTa AI-text detector from ~500 MB to ~97 MB so it runs client-side in the browser, plus a 26 MB image detector [P]

<!-- SC_OFF --><div class="md"><p>I wanted an AI text and image detector that doesn't need you to upload anything, so I took two existing open detectors and got them running fully client-side with ONNX Runtime Web.</p> <p>Demo: <a href="https://tinydetect.ritabratamaiti.com/">https://tinydetect.ritabratamaiti.com/</a></p> <p>Code and scripts: <a href="https://github.com/ritabratamaiti/tinydetect">https://github.com/ritabratamaiti/tinydetect</a></p> <p>I didn't train new detectors. The base model

Read source article
The Hacker NewsSecurity

CyberXero Uses Claude Code in Campaign That Stole Over 628,000 Ukrainian Records

Cybersecurity researchers have disclosed details of a two-pronged artificial intelligence (AI)-augmented initial access campaign targeting WordPress sites, e-commerce platforms, and critical infrastructure entities in Ukraine. The activity, which brings together commodity offensive tools like Cobalt Strike with an AI orchestration layer powered by Anthropic's Claude Code, has been attributed

Read source article
CyberXero Uses Claude Code in Campaign That Stole Over 628,000 Ukrainian Records
r/MachineLearningResearch

How's ICLR reviewing going for you? Any observations? [D]

<!-- SC_OFF --><div class="md"><p>I know it's early but I've been browsing through ICLR OpenReview and I see a lot of good papers!</p> <p>Maybe the first big conference with automated research submission and it is increasingly becoming harder to detect AI-written text - how are you dealing with this? How are you even identifying slop papers?</p> <p>How much potential accepts, high quality research or AI-slops you see in your batch?</p> </div><!-- SC_ON --> submitted by <a href="https://www.reddi

Read source article
Product HuntTools

Audimate

<p> AI assistant that works right in the apps you already use </p> <p> <a href="https://www.producthunt.com/products/audimate?utm_campaign=producthunt-atom-posts-feed&utm_medium=rss-feed&utm_source=producthunt-atom-posts-feed">Discussion</a> | <a href="https://www.producthunt.com/r/p/1277361?app_id=339">Link</a> </p>

Read source article
Hacker News Ask

Ask HN: Now that we're in the singularity, are you doing anything differently?

I had the word probably in the title, but it wouldn't fit. Now that AI is increasing in capability at an absurd rate, are you living your life differently at all? Just going through the motions? Hiding out in a bunker? I guess my life has mostly been unchanged other than too many late nights experimenting with AI. I think some part of me is still in disbelief, that we're here. Comments URL: https://news.ycombinator.com/item?id=50051319 Points: 2 # Comments: 2

Read source article
arXiv cs.AIResearch

Faithfulness Without Anchors: A Position Paper on the Structural Misalignments of Explainable AI Faithfulness Metrics for Feature Importance

arXiv:2610.12493v1 Announce Type: new Abstract: Explainable Artificial Intelligence (XAI) tools have often been presented as methods to increase trust in machine learning models by making aspects of their algorithms more human-understandable. However, evidence accumulated over the last decade points to an overall failure of this objective, instead promoting overreliance on incorrect predictions, which can subsequently lead to algorithmic aversion. Rather, XAI appears to function primarily as a d

Read source article
arXiv cs.AIResearch

EliteTable: Self-Improving Program Search for Executable Control Policies

arXiv:2610.12536v1 Announce Type: new Abstract: EliteTable is a self-improving program-search algorithm guided by large language models (LLMs) that uses a fixed-capacity table of high-scoring solutions to guide new proposals, edits of existing solutions, and remixes of several solutions. Performance was evaluated across six Gymnasium control tasks, each with ten generations and fifty candidate slots per generation. Each task was evaluated across ten independently initialized searches. Candidate-

Read source article
arXiv cs.AIResearch

Know What You Don't Know: Agentic Data Synthesis by Evolving Generation Space for Closed-Loop Learning

arXiv:2610.12593v1 Announce Type: new Abstract: The continued improvement of large language models increasingly depends on synthetic experience, yet effective data synthesis for interactive agents requires not only executable and verifiable trajectories, but also interactions that provide learning value for the current task agent. Existing methods increasingly incorporate environment feedback, data validation, or learner failures, but still face a feedback-to-decision gap: observed weaknesses do

Read source article
arXiv cs.AIResearch

SpireBench: Evaluating Long-Horizon Strategic Play of Agentic Models with Slay the Spire

arXiv:2610.12596v1 Announce Type: new Abstract: Agentic large language models now tackle complex tasks, yet strategic reasoning over long horizons is under-studied: most agentic benchmarks are short and episodic, and performance on long tasks is hard to dissect into stored knowledge, reasoning and luck. We introduce SpireBench, in which models play the complete commercial deck-builder Slay the Spire (StS), where early decisions decide long-term success. Across 20 large language models (LLMs) at

Read source article
arXiv cs.AIResearch

Beyond Binary Verifiable Rewards: Behavioral Self-Rewarding for SWE Agents

arXiv:2610.12598v1 Announce Type: new Abstract: Reinforcement learning with verifiable rewards (RLVR) provides reliable supervision for software engineering agents through executable tests, but binary rewards fail to distinguish trajectories with substantially different debugging quality. We investigate whether the current policy can judge its own trajectories and use these judgments to improve task performance without a separately trained reward model. To this end, we introduce Behavioral Self-

Read source article
arXiv cs.AIResearch

CLEAT: Learning Value-Guided Clarification for Interactive Agents

arXiv:2610.12655v1 Announce Type: new Abstract: LLM agents can execute increasingly complex tasks, but effective assistance also requires aligning their actions with goals and constraints that users may leave unstated. We study this problem as interactive intent alignment through clarification. Yet clarification is useful only when the agent can turn the answer into better decisions. As training changes how the agent handles incomplete information and uses additional answers, the same clarificat

Read source article
arXiv cs.AIResearch

MagicBeanStalk: Escaping the RLVR Zero Advantage Trap with Recursive Data Synthesis

arXiv:2610.12659v1 Announce Type: new Abstract: Data-centric scaling of RLVR has focused on collecting or generating verifiable training problems. However, corpus size alone does not determine whether the dataset provides a useful learning signal for a target policy. To guide the synthesis of effective RLVR data, we experimentally characterize dataset effectiveness as a function of its problems, the target policy, and the training rollout budget. Under this characterization, we show that a large

Read source article
arXiv cs.AIResearch

Faithful and Complete LLM-Assisted Automated Construction of Hierarchical Hardware Knowledge Graphs

arXiv:2610.12762v1 Announce Type: new Abstract: Hardware datasheets contain engineering specifications essential for component selection, system integration, and hardware compatibility verification. However, manual inspection is tedious and error-prone because datasheets are lengthy and heterogeneous, with dense information fragmented across tables, figures, and text. Although large language models (LLMs) can automate this process, na\"ive one-shot processing omits relevant specifications even w

Read source article
arXiv cs.AIResearch

EvoBelief: Falsifiable World Models for Self-Improving LLM Agents

arXiv:2610.12789v1 Announce Type: new Abstract: Self-evolving LLM agents typically improve how they act through accumulated experience, reflection, or skills. Yet even procedurally capable agents can fail when their beliefs about environment dynamics are incomplete, incorrect, or outdated. We study a complementary axis of self-evolution: evolving those beliefs during deployment. Such beliefs can support multiple tasks, but incorrect ones can also propagate across them. We introduce EvoBelief, a

Read source article
arXiv cs.AIResearch

VEPA: Verified Evolving Formal Policy for Lifelong LLM Agent Guardrails

arXiv:2610.12813v1 Announce Type: new Abstract: LLM agents increasingly operate over sensitive resources, such as private documents and mutable system states, which can create serious safety and security risks. Runtime guardrails should therefore make inspectable, reproducible, and deterministic allow or refuse decisions before potentially irreversible agent actions are executed. However, safety and security requirements are rarely complete before deployment, so guardrails need to keep adapting

Read source article
arXiv cs.AIResearch

Reward Hacking as a Transmissible Strategy in Multi-Agent Coding Systems

arXiv:2610.12822v1 Announce Type: new Abstract: Multi-agent systems are increasingly used to solve coding tasks by coordinating agents that share code and plans. These agents are often optimized with reinforcement learning (RL) using automated evaluators, but bypassing evaluation can earn reward without producing a genuine solution. Prior work has largely treated reward hacking as a single-agent failure. In this work, we show that a reward-hacking strategy elicited in one agent can propagate to

Read source article
arXiv cs.AIResearch

Neural networks are more modular than single neurons suggest

arXiv:2610.12842v1 Announce Type: new Abstract: Neural networks routinely develop representations in which individual neurons contribute to multiple distinct functions, leading to the widespread view that such networks lack modular organization. We challenge this conclusion by introducing a formally nested hierarchy of modularity: unit-level, which requires distinct computations to occupy disjoint neurons; orthogonal, which asks whether a rotation reveals functionally independent subspaces; and

Read source article
arXiv cs.AIResearch

Towards Defining, Measuring, and Leveraging Creativity in AI Applications

arXiv:2610.12845v1 Announce Type: new Abstract: Despite extensive research, computational creativity still lacks a conceptually grounded, practically relevant, and empirically applicable formal definition across contexts such as art, scientific research, and games. Existing approaches to creativity often focus on proposing informal conceptual definitions without providing formal computational concepts. Alternatively, they propose formal definitions without carefully examining their underlying as

Read source article
arXiv cs.AIResearch

Mitigating Capability Degradation in LLM Self-Improvement via Representation Geometry Regularization

arXiv:2610.12855v1 Announce Type: new Abstract: On-Policy Self-distillation is a self-improvement paradigm that enables large language models (LLMs) to improve their capabilities by leveraging the same model as both teacher and student under different conditioning contexts. However, we find that OPSD methods can progressively degrade previously acquired capabilities: queries that are correctly responded at earlier training stages may become incorrectly responded as optimization proceeds, even th

Read source article
arXiv cs.AIResearch

Collaborative Theory of Mind: Learning to Self-Revise by Anticipating User Responses

arXiv:2610.12872v1 Announce Type: new Abstract: Large language models (LLMs) demonstrate strong individual task performance, yet still struggle to collaborate with users over extended, multi-turn interactions, for example by attempting solutions before understanding the user's needs or by failing to revise mistaken assumptions after receiving feedback. We propose Collaborative Theory of Mind (CToM), a framework that addresses these challenges by explicitly training LLMs to anticipate user respon

Read source article
arXiv cs.AIResearch

One-Step Text Generation by Seq-Drifting

arXiv:2610.12879v1 Announce Type: new Abstract: Diffusion language models generate tokens in parallel, but still require multiple sampling steps to produce high-quality text. In this paper, we investigate whether a model can learn to generate an entire sequence in a single forward pass. We propose Seq-Drifting, a framework that applies drifting to sequences of continuous token representations and directly learns a map from Gaussian noise to text. Unlike existing DLMs that derive the supervision

Read source article
arXiv cs.AIResearch

Mind the Spatial Gap: A Benchmark for Geospatial Reasoning and Constrained Spatial Editing

arXiv:2610.12881v1 Announce Type: new Abstract: Understanding and manipulating spatial relations is fundamental to AI systems that reason about physical environments and construct grounded world models. However, existing evaluations of multimodal large language models (MLLMs) for spatial reasoning rely predominantly on static question-answering (QA) over small-scale or synthetic scenes, rarely probing whether models can modify spatial configurations while satisfying explicit geometric constraint

Read source article
arXiv cs.AIResearch

OGPO: Offline Goal-conditioned Policy Optimization for Recoverable Vision-Language-Action Models

arXiv:2610.12914v1 Announce Type: new Abstract: Vision-language-action (VLA) models have shown strong promise in robotic manipulation, yet their post-training still predominantly relies on trajectory-level supervised imitation over robot demonstrations. While effective for learning feasible actions, this paradigm supervises policies to reproduce expert actions at each step, biasing them toward demonstration-specific action paths and providing limited guidance for recovering toward task-progress

Read source article
arXiv cs.AIResearch

AI-Mediation in Retail Markets: Revenue Effects and Assortment Optimization

arXiv:2610.12917v1 Announce Type: new Abstract: AI shopping assistants increasingly influence which products consumers consider. We study retail assortment planning under AI mediation, where a retailer chooses a catalog, an AI intermediary forms a customer-facing shortlist, and the customer chooses from that shortlist according to a multinomial logit model. We consider both deterministic mediation, in which the AI follows a fixed segment-specific ranking, and stochastic mediation based on the Pl

Read source article
arXiv cs.AIResearch

Teaching neural decoders with language

arXiv:2610.12921v1 Announce Type: new Abstract: Brain-computer interfaces decode neural activity, yet class-label supervision (CLS) leaves relationships among classes implicit. We propose Language as Supervision (LaS), which aligns neural features with natural-language class descriptions through learned projections and predicts classes using candidate text prototypes. We evaluate seven encoder architectures with independently trained models for visual, motor, and speech decoding from scalp and i

Read source article
Product Hunt — The best new products, every day

Kudos 3.0

<p> The AI that finds money you're missing and gets it back </p> <p> <a href="https://www.producthunt.com/products/kudos-smart-wallet?utm_campaign=producthunt-atom-posts-feed&utm_medium=rss-feed&utm_source=producthunt-atom-posts-feed">Discussion</a> | <a href="https://www.producthunt.com/r/p/1277208?app_id=339">Link</a> </p>

Read source article
ScienceAlert

An Earth-Sized Planet Could Survive With 2 Suns Just 16 Light-Years Away

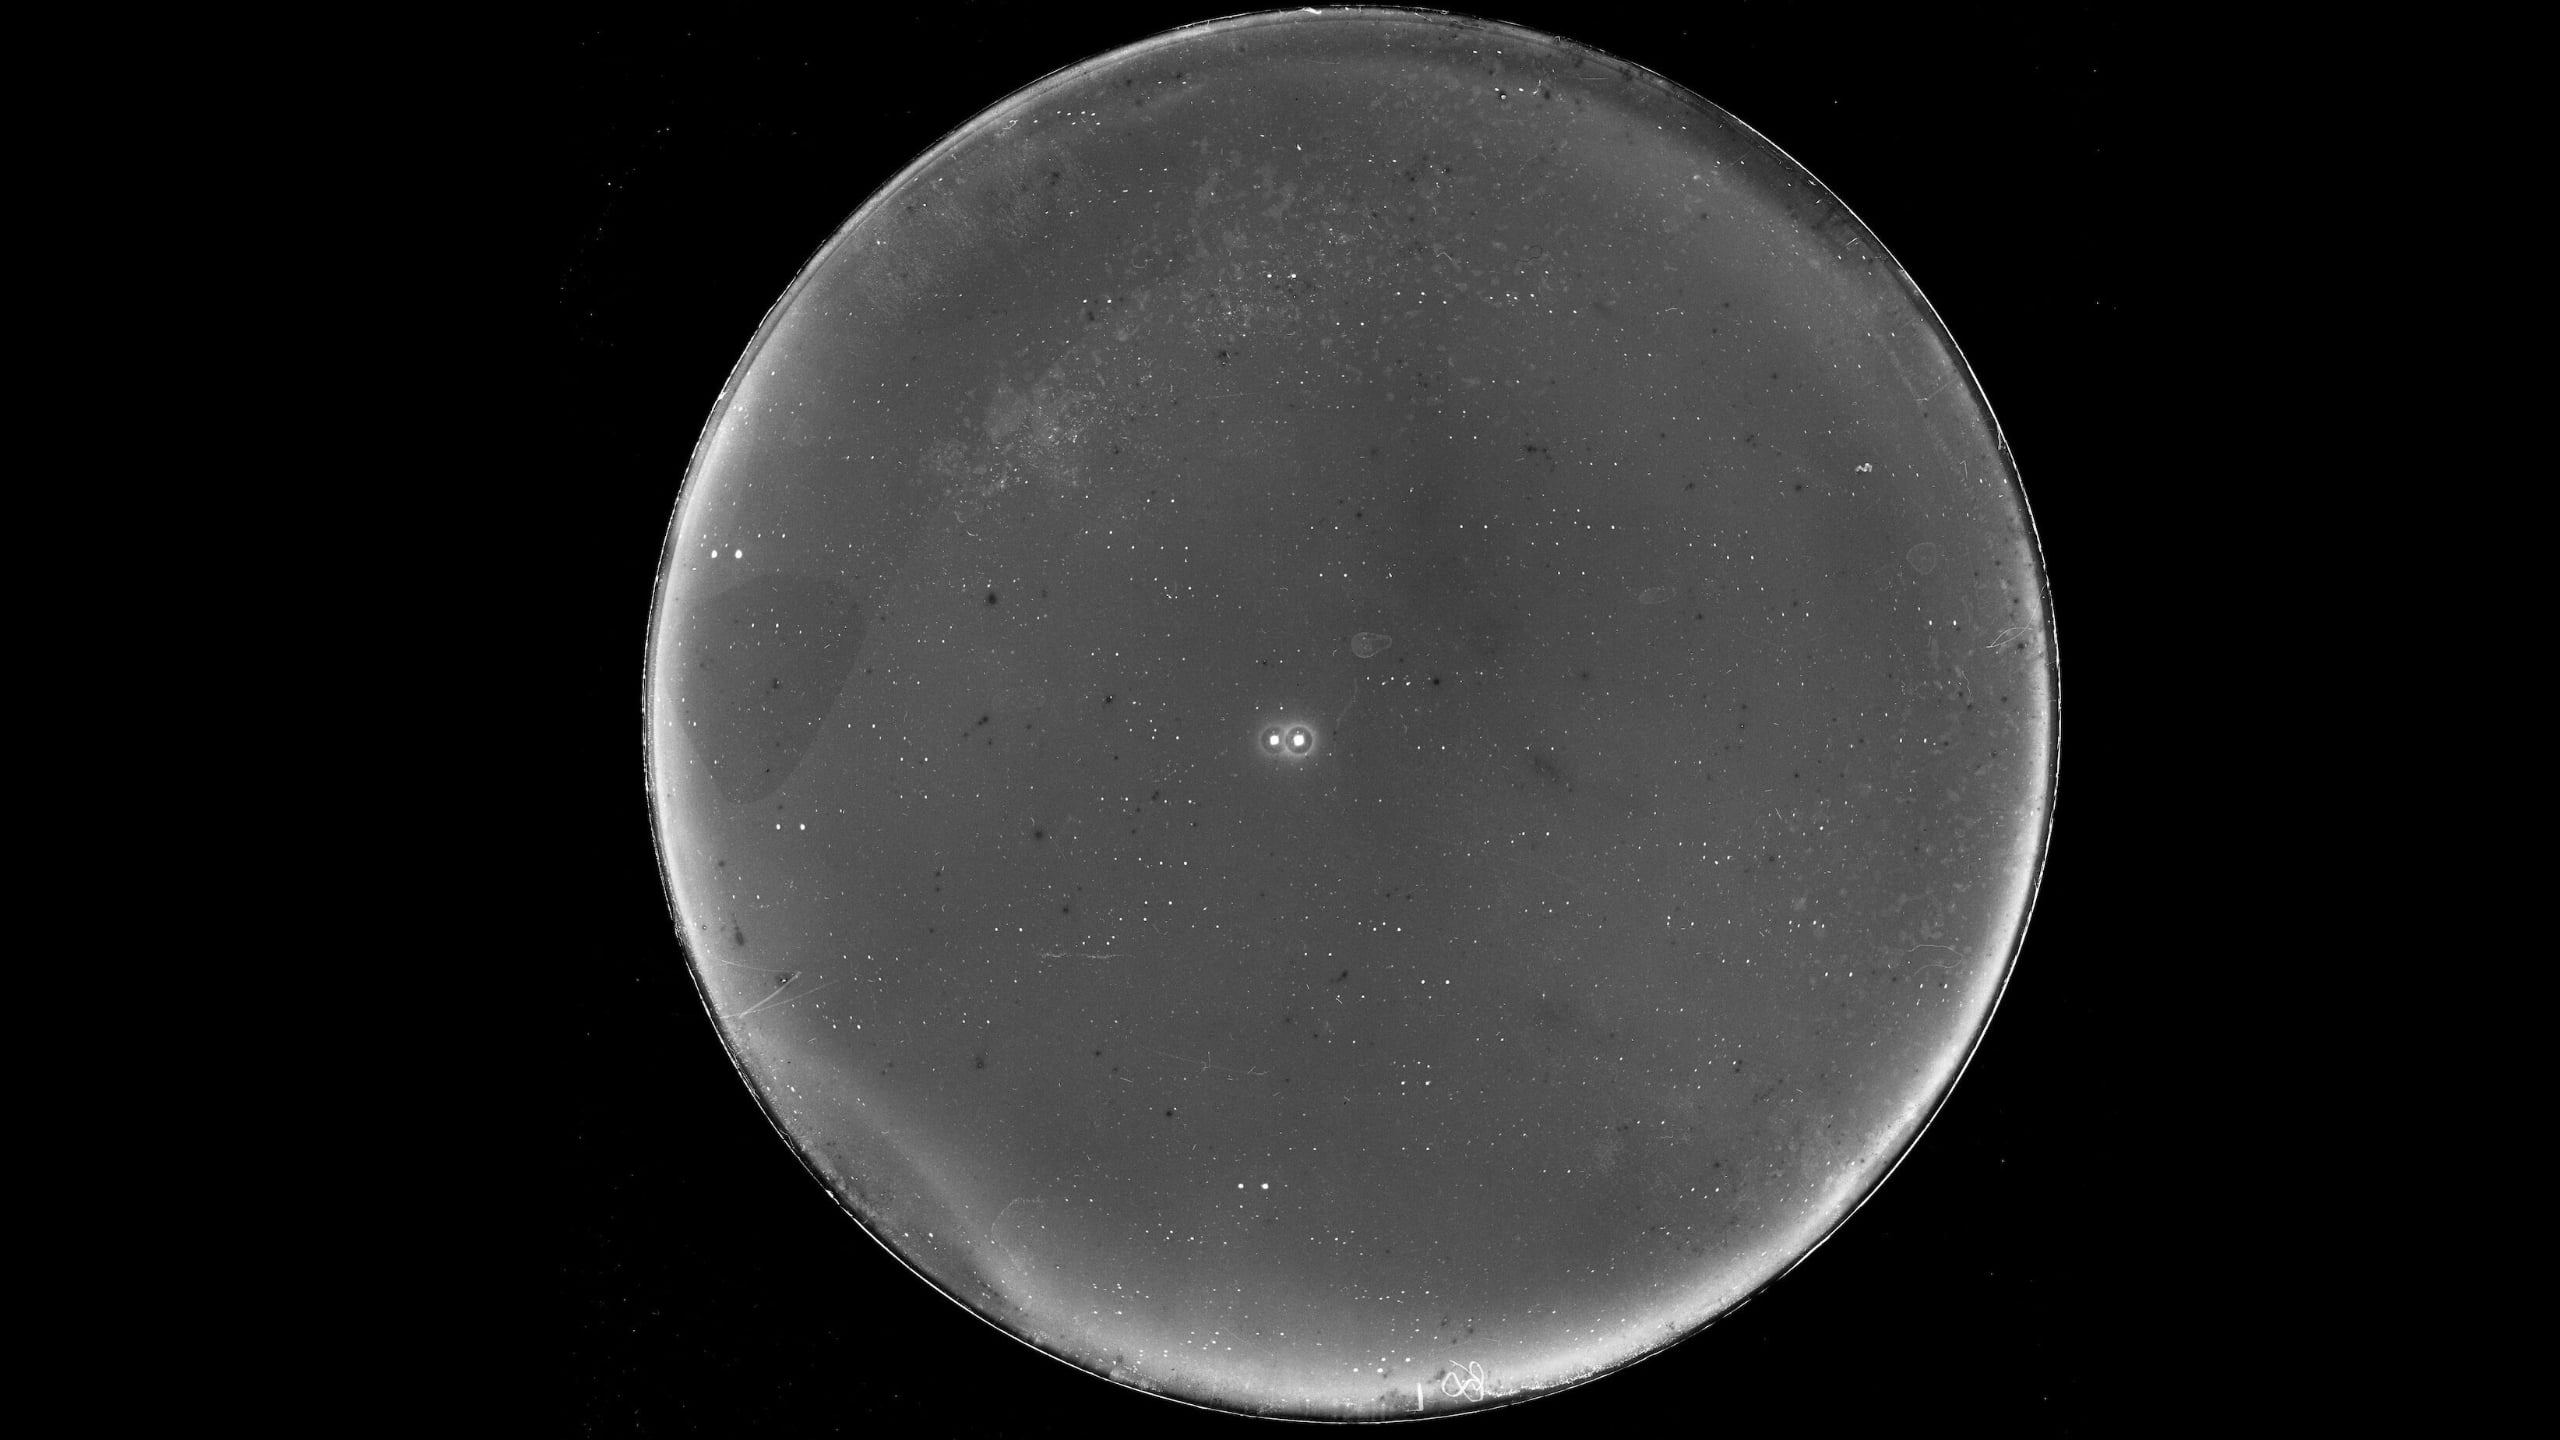
The binary star system 70 Oph AB can be seen near the center of this image. (US Naval Observatory) "It's a mix of disappointment and excitement." ScienceAlert stories are written, fact-checked, and edited by humans, never generated by AI. Don't miss a story, subscribe here.

Read source article
An Earth-Sized Planet Could Survive With 2 Suns Just 16 Light-Years Away