Meet the world's top AI-Pilled Economists
Article URL: https://www.economist.com/finance-and-economics/2026/06/15/meet-the-worlds-top-ai-pilled-economists Comments URL: https://news.ycombinator.com/item?id=48550917 Points: 3 # Comments: 1
Article URL: https://cryptoclarityai.com/ Comments URL: https://news.ycombinator.com/item?id=48550877 Points: 2 # Comments: 0
<p> Deploy sites from AI chat to published HTML </p> <p> <a href="https://www.producthunt.com/products/html-deployer-2?utm_campaign=producthunt-atom-posts-feed&utm_medium=rss-feed&utm_source=producthunt-atom-posts-feed">Discussion</a> | <a href="https://www.producthunt.com/r/p/1172965?app_id=339">Link</a> </p>
Comments URL: https://news.ycombinator.com/item?id=48550725 Points: 2 # Comments: 0
<!-- SC_OFF --><div class="md"><p>Been working on this a while! Should be useful for anyone trying to speed up their tokenization workflows.</p> <p><strong>quicktok</strong> is a fast/exact BPE tokenizer written in C++. Token ids are byte-identical to <code>tiktoken</code> and encoding runs <strong>2–3.6×</strong> faster than <code>bpe-openai</code> (the fastest alternative I know of) and <strong>4–11×</strong> faster than <code>tiktoken</code> itself. It ships cl100k, o200k, GPT-OSS, Llama-3, a
Article URL: https://github.com/wdh107/agent-audit-trail Comments URL: https://news.ycombinator.com/item?id=48550486 Points: 1 # Comments: 0
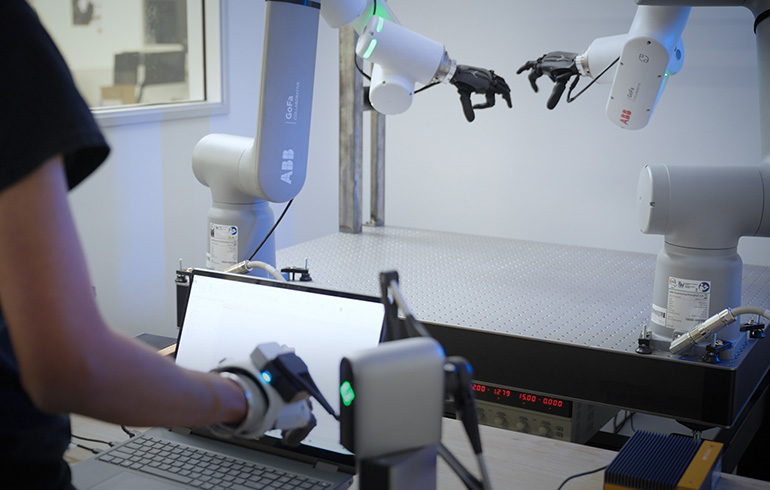
PSYONIC is combining its Ability Hand with ABB Robotics' GoFa cobot arm to apply data from prosthetics users to robotic grasping. The post PSYONIC partners with ABB Robotics to apply human touch to robot dexterity appeared first on The Robot Report .

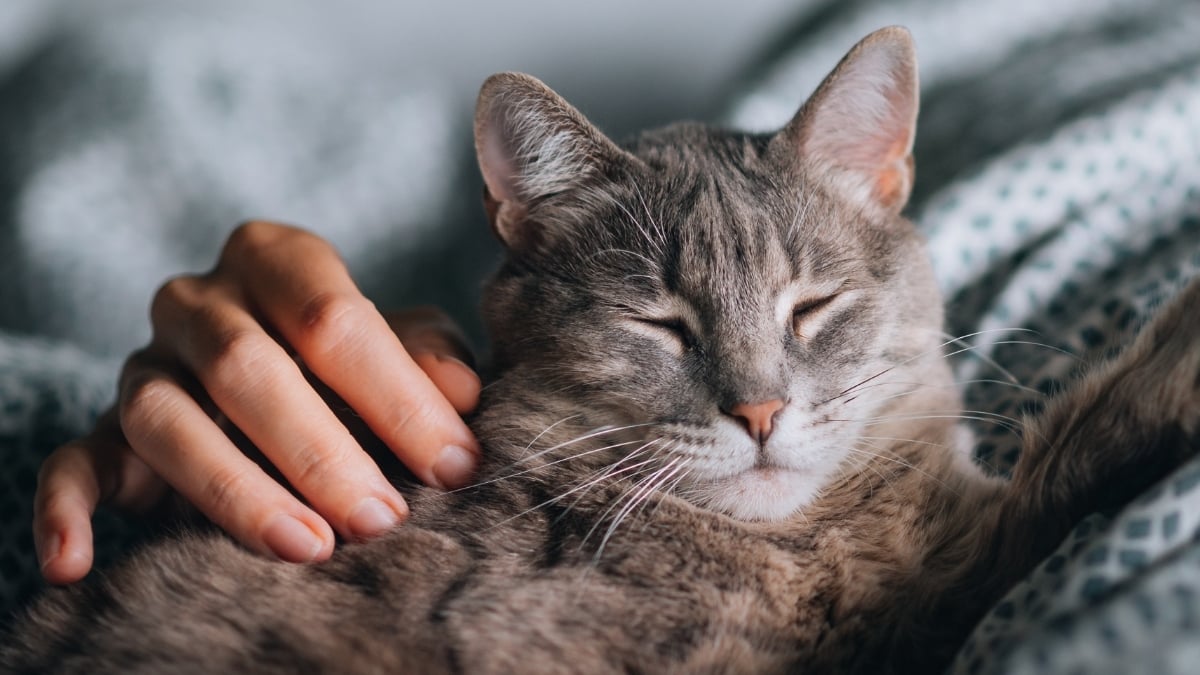
Pets could affect mood in ways scientists didn't expect. ScienceAlert stories are written, fact-checked, and edited by humans, never generated by AI. Don't miss a story, subscribe here.

Article URL: https://digital-strategy.ec.europa.eu/en/policies/eu-icons-labelling-ai-generated-content Comments URL: https://news.ycombinator.com/item?id=48550435 Points: 3 # Comments: 0
arXiv:2606.15236v1 Announce Type: new Abstract: Pixel-space diffusion models are trained on full-bandwidth noisy images, yet the useful signal available to the denoiser is strongly frequency dependent. Under rectified-flow diffusion and natural-image power-law spectra, the per-band data-to-noise contour $k^{*}(t) = (1-t)^{-2/\alpha}$ separates a signal-bearing low-frequency region from a noise-dominated high-frequency region at each time $t$. We show that this implicit coarse-to-fine structure i
arXiv:2606.15253v1 Announce Type: new Abstract: Adapting Detection Transformers to Incremental Object Detection (IOD) poses a systemic challenge, as set-based optimization is inherently destabilized by sequential learning. In this work, we identify Gradient Dilution as the root cause of performance degradation, wherein optimization signals required to preserve old knowledge are progressively weakened. This phenomenon manifests as a cascading erosion of preservation gradients in magnitude, direct
arXiv:2606.15265v1 Announce Type: new Abstract: Congenital heart disease (CHD) refers to the abnormal anatomical structure caused by the abnormal development of the heart and great vessels during embryonic development. Traditional diagnostics often fail to achieve high accuracy and efficiency, especially given the complexity of cardiac anatomy. This study presents a specialized multi-view deep learning framework for CHD binary classification using echocardiographic images. A large-scale CHD data
arXiv:2606.15282v1 Announce Type: new Abstract: This study proposes an overall deep learning architecture for multi-class classification of plant diseases from high-resolution leaf imagery, with a particular interest in investigating the behavior of ResNet-50 and a hybrid ResNet + Vision Transformer (ViT) design. A specially gathered image database with 15,200 training images and 3,800 validation images spanning 38 classes across multiple crops, including tomato, apple, grape etc. were subjected
arXiv:2606.15287v1 Announce Type: new Abstract: Cross-modal place recognition (CMPR) enables camera-only robots to localize against pre-built LiDAR maps in autonomous navigation scenarios. This image-to-point-cloud setting is challenged by two coupled ambiguities: the modality gap between perspective RGB appearance and sparse metric geometry, and perceptual aliasing among urban places with similar roads, facades, intersections, and object arrangements. Instead of treating CMPR as a single global
arXiv:2606.15304v1 Announce Type: new Abstract: Hematoma expansion (HE) after spontaneous intracerebral hemorrhage (ICH) is a major determinant of acute triage and treatment decisions in neurosurgical care. However, most existing methods provide either a binary expansion risk or a single follow-up volume, limiting uncertainty-aware decisions. We introduce HemExp, a clinically-guided latent diffusion model that generates patient-specific follow-up non-contrast CT images, along with segmentations
arXiv:2606.15305v1 Announce Type: new Abstract: Accurate brain tumor segmentation from multiparametric magnetic resonance imaging (MRI) is critical for treatment planning, response assessment, and quantitative neuro-oncology research. However, automated segmentation remains a difficult task in computer vision because of variation in tumor appearance and MRI protocols across patient scans. Moreover, clinically important regions such as enhancing tumor (ET) and tumor core (TC) are often small rela
arXiv:2606.15320v1 Announce Type: new Abstract: Multimodal large language models have made rapid progress in video temporal grounding, yet real-world applications routinely require localizing every event that satisfies compositional temporal and spatial conditions. Existing benchmarks fall short: they localize only a single moment per query, count without temporal conditions, or treat grounding and counting as disjoint tasks. We introduce CoMET-Bench for Conditional Multi-Event Temporal Groundin
arXiv:2606.14838v1 Announce Type: new Abstract: How to define a good explanation is a long-standing philosophical debate which has found recent renewed interest in the context of AI outputs. Explainability is crucial for AI adoption in many contexts, but in order to produce good explanations of AI systems, we must first have an understanding of what good explanations are. In this paper we propose a definition inspired by the notion of counterfactual explanations, however we argue that one must a
arXiv:2606.14885v1 Announce Type: new Abstract: Agentic search over large corpora relies on retriever-mediated interfaces (e.g., BM25 or ColBERT) for scalable candidate discovery. While effective at ranking relevant documents, these interfaces expose evidence only as ranked results or bounded document views, limiting agents' ability to reorganize material and verify constraints across documents. Direct Corpus Interaction (DCI) addresses this limitation by exposing shell-executable corpus operati
arXiv:2606.14892v1 Announce Type: new Abstract: An artificial intelligence must have a model of its environment that is causal, supporting reasoning about interventions and counterfactuals, and also combinatorial, supporting generalization to unseen combinations of objects. In this work, we formally study when and how such a model can be learned. We develop relational structural causal models, extending structural causal models (Pearl 2009) to settings where objects and their relations vary. Fir
arXiv:2606.14923v1 Announce Type: new Abstract: As language-model agents increasingly work in teams, each agent must decide how much to trust its teammates. Yet we lack a standard way to measure trust between AI agents. We propose a behavioral measure based on costly verification. In a cooperative survival game, checking a teammate's work consumes resources, while trusting a wrong answer can be fatal. Relative to a memoryless version of the same model, reduced verification provides an observable
arXiv:2606.14935v1 Announce Type: new Abstract: Frontier reasoning-tuned language models still fail on deductive tasks at depth, and the cost of improved performance through extended internal reasoning scales poorly. Symbolic delegation offers a complementary route: a language model translates the problem, while a solver performs the inference. However, current autoformalization pipelines for logic programming are typically bespoke integrations tied to particular tasks or agents. We introduce Pr
arXiv:2606.14997v1 Announce Type: new Abstract: Memory formation is fundamental to intelligence, yet whether deep neural networks preserve identifiable memory traces analogous to biological memory units remains an open question. This work introduces a geometric framework to identify such "AI engrams" by formalizing the neuroscientific criteria of specificity, reactivation, sufficiency, and necessity into a constrained inverse problem. We derive a closed-form estimator that isolates individual me
arXiv:2606.15029v1 Announce Type: new Abstract: LLM judges are used to reduce the need for costly human labor in evaluating open-ended text generation. However, the reliability of these judges depends critically on their alignment with human raters -- a property that itself depends on costly human annotations. In this work, we develop a method (Metric Match) for estimating correlation-based reliability metrics of LLM judges from limited annotations. Metric Match selects a subset of samples for h
arXiv:2606.15034v1 Announce Type: new Abstract: Computer-use agents are increasingly evaluated by whether they complete realistic desktop and web tasks. However, task success alone can miss failures in which an agent reaches the nominal goal through an unsafe shortcut. We introduce OSGuard, a dual-granularity benchmark suite for evaluating safety in computer-use agents under benign, unchanged user instructions. OSGuard contains an action-level benchmark for local guardrail decisions and a risk-a
arXiv:2606.15038v1 Announce Type: new Abstract: Accurate time-to-event (TTE) prediction from multimodal clinical data remains challenging due to modality imbalance and distribution shift. We introduce a foundation model-driven framework for cross-modal representation alignment between CT imaging and longitudinal EHR data, designed to generalize across tasks and institutions. CT and EHR modalities are encoded independently using domain-specific foundation models and aligned in a shared latent spa
arXiv:2606.15077v1 Announce Type: new Abstract: We present an LLM-driven framework for retrieving remote sensing data from cloud-based geospatial catalogues using natural language queries. The system converts user intent into structured API calls, enabling efficient access to satellite imagery and environmental datasets. The architecture integrates three agents: Guardrail for safety and policy enforcement, General-QA for intent interpretation, and Recommender-Analyst for schema-aware API call ge
arXiv:2606.15078v1 Announce Type: new Abstract: We develop a formal theory of cognitive debt: the stock of unverified reasoning obligations that accumulates when individuals use AI as a substitute rather than a complement for first-principles cognition. The model features two state variables per agent, cognitive capital and cognitive debt, and a multiplicative production technology in which cognitive capital functions as collateral that determines the return to AI adoption. We establish six prop
arXiv:2606.15096v1 Announce Type: new Abstract: The Riemann Hypothesis remains one of the central unsolved problems in mathematics. Rather than claiming proof, we investigate whether a verifiable AI-assisted reasoning system can produce reliable, formally checked partial progress while explicitly identifying the remaining mathematical obstructions. We apply the Verifiable Growing Physical Transformer with Recursive Self-Improvement (VGPT-RSI) to two RH-adjacent certification tasks. First, we con
arXiv:2606.15107v1 Announce Type: new Abstract: Time series data in real-world deployments is overwhelmingly irregular. Observations are asynchronous, missing values are informative rather than random, and sampling frequencies vary across sensors and operational windows. However, existing Time Series Question Answering (TSQA) benchmarks mostly assume regularly sampled inputs, leaving a fundamental gap in understanding how large language models (LLMs) and AI agents perform under irregular conditi
arXiv:2606.15179v1 Announce Type: new Abstract: Retrieval-augmented generation (RAG) has emerged as a pivotal technique for improving language models by incorporating external knowledge at inference time. As device-cloud collaborative inference makes it feasible to deploy small language models on edge devices, a new setting arises in which private documents remain on the device and public knowledge resides in the cloud. Privacy and policy constraints often forbid raw document exchange, creating
arXiv:2606.15199v1 Announce Type: new Abstract: Proactive warning is an important capability for edge intelligent services, where the system predicts whether a subject will successfully complete an incoming task under strict latency and privacy constraints. Such prediction depends on both long-term static attributes and short-term dynamic states derived from historical interaction logs. Recent Large Language Models (LLMs) offer strong long-context reasoning for constructing structured profiles f
arXiv:2606.15209v1 Announce Type: new Abstract: Targeted advertising systems can pair audiences selected by advertisers with ad units that expose visible user actions. When an interaction remains linked to the campaign that elicited it, the advertiser may receive an observation tied to a user rather than only an aggregate report. We model that channel as a noisy oracle for attribute inference. The model separates targeting predicates, exposure, interaction, and disclosure. These boundaries captu
arXiv:2606.15231v1 Announce Type: new Abstract: Multimodal large language models (MLLMs) have demonstrated impressive capabilities in many visual tasks, but they often struggle with factual grounding when confronted with complex, open-world scenarios. While recent multimodal deep search agents attempt to address this issue by utilizing external tools, the visual-native search paradigm remains underexplored. Existing methods primarily rely on simple images with explicit semantics and text-only ev
arXiv:2606.15258v1 Announce Type: new Abstract: Large language models (LLMs) are increasingly capable of mathematical problem solving and can even assist with research-level proofs, yet we still lack a scalable and reproducible way to measure step-level reasoning in long proofs across diverse sources. This evaluation gap limits trustworthy AI assistance in proof-certified scientific progress. Existing evaluations often emphasize final answers or rely on costly expert grading, while end-to-end pr
arXiv:2606.15291v1 Announce Type: new Abstract: Agentic AI opens new opportunities for automating Business Process (BP), enabling autonomous decision-making and dynamic adaptation. However, realising this potential requires BP entities and their interactions to be defined with formal precision. This paper presents a formal framework for Agentic BP analysis through the AGO methodology. AGO captures the modelling perspective in terms of who is acting (Agents), why it is carried out (Goals), and wh
arXiv:2606.15300v1 Announce Type: new Abstract: Advanced agents are increasingly demonstrating the potential to operate as autonomous engineers, creating a growing demand for evaluation benchmarks that capture the complexity of real-world development. Such environments typically involve both complex code and large-scale data (i.e., file system). However, existing benchmarks usually evaluate code-centric or data-centric capabilities in isolation, leaving a clear gap with real development scenario
arXiv:2606.15323v1 Announce Type: new Abstract: Diffusion models have demonstrated superior fidelity for medical image-to-image translation, but their extension to high-resolution 3D volumes is severely constrained by prohibitive computational cost and GPU memory requirements. Existing memory-efficient strategies often compromise global volumetric consistency or fine anatomical detail. In this work, we propose the Pixel Puzzling Diffusion Model (PPDM), a simple and effective framework for memory
arXiv:2606.14720v1 Announce Type: new Abstract: This study aims to enhance maritime security by using advanced Artificial Intelligence (AI) and Computer Vision (CV) techniques. For this purpose, it was designed and assessed intelligent object detection systems that can detect the presence of ships on the sea surface under different real-time environments. To achieve this goal, a maritime image dataset with 6,468 images was used, covering different weather conditions like cloudy, foggy, rainy, an
arXiv:2606.14723v1 Announce Type: new Abstract: We study multiple-choice video question answering on the ImplicitQA benchmark, where the correct answer is never explicitly shown but must be inferred from off-screen events, line-of-sight cues, causal structure, and cross-shot spatial layout. On this benchmark a single frontier video LLM already operates near its accuracy ceiling, and we observe that conventional self-consistency strategies -- majority voting across repeated samples of the same mo