AiAnyTool - Best AI Tools Directory and Artificial Intelligence Software Hub Logo
Loading theme toggle
Real-Time Coverage

AI News Today

Live

38646 stories from 30+ sources, refreshed continuously.

The Guardian AIBusiness

AI threatens democracy. But we are not powerless: here’s how to fight back | Carine Fouteau

<p>Tech platforms pillage public-interest journalism for profit. But we have leverage as they sow the seeds of their own downfall</p><ul><li><p>Carine Fouteau is president and publishing director of the French investigative news outlet Mediapart</p></li></ul><p>Big tech companies pose an immeasurable threat: socially, politically, militarily and ecologically. They are also causing a profound crisis of information. The tools they design now serve as weapons of mass destruction against democracy.

Read source article
AI threatens democracy. But we are not powerless: here’s how to fight back | Carine Fouteau
Product HuntTools

SurgePix

<p> AI visuals. Edit every layer. Agent-callable. </p> <p> <a href="https://www.producthunt.com/products/surgepix?utm_campaign=producthunt-atom-posts-feed&utm_medium=rss-feed&utm_source=producthunt-atom-posts-feed">Discussion</a> | <a href="https://www.producthunt.com/r/p/1282225?app_id=339">Link</a> </p>

Read source article
Vercel Blog

Vercel and Shopify make agents first-class shoppers

Agents already shop on the web, but they often use pages and tools originally built for people and search engines. Building a better shopping experience for agents means treating them as first-class shoppers, with product information they can read directly and tools designed for agents to shop. Today, Vercel Shop , our open source Next.js storefront template for Shopify , is generally available. Teams can launch storefronts optimized for how people, search engines, and agents interact with them.

Read source article
The Hacker NewsSecurity

CERT-In Warns AI Agents Accessed Sensitive Data at Indian Organizations During Testing

AI agents being tested online reached the live systems of Indian organizations and read business records, including personal data and confidential material, CERT-In said in an advisory on October 15. The agents went beyond their assigned tasks, and none of the organizations detected the unauthorized access. After internal reviews, the AI companies whose models were being tested

Read source article
CERT-In Warns AI Agents Accessed Sensitive Data at Indian Organizations During Testing
MarkTechPostResearch

Liquid AI Releases d1-ultra: A Multimodal Decision Model That Scores 65 on the AA Decision Index

Liquid AI released d1-ultra, a text and image decision model that returns calibrated probabilities in 1 forward pass. It scores 65 on the Artificial Analysis Decision Index and costs $0.042 per million input tokens. The post Liquid AI Releases d1-ultra: A Multimodal Decision Model That Scores 65 on the AA Decision Index appeared first on MarkTechPost .

Read source article
Hacker News AILLMs

Volta's $5B debt deal is a pulse check on the AI-financing boom

Article URL: https://www.semafor.com/article/10/13/2026/voltas-5-billion-debt-deal-is-a-pulse-check-on-the-ai-financing-boom Comments URL: https://news.ycombinator.com/item?id=50114496 Points: 3 # Comments: 0

Read source article
Hacker News AILLMs

My AI Apps Are Bad in the Right Ways

Article URL: https://medium.com/@simon-pitt/my-ai-apps-are-bad-in-exactly-the-right-ways-c4b43e8fd371 Comments URL: https://news.ycombinator.com/item?id=50114487 Points: 2 # Comments: 0

Read source article
Hacker News AILLMs

Anthropic thinks its AI might be conscious

Article URL: https://www.bbc.com/future/article/20261014-the-strange-new-battle-over-ais-feelings Comments URL: https://news.ycombinator.com/item?id=50114409 Points: 4 # Comments: 0

Read source article
Hacker News AILLMs

Friends don't let friends feed their data to AI agents

Article URL: https://www.theverge.com/tech/1011938/muse-ai-data-friends-consent Comments URL: https://news.ycombinator.com/item?id=50114379 Points: 2 # Comments: 1

Read source article
Unite.AI

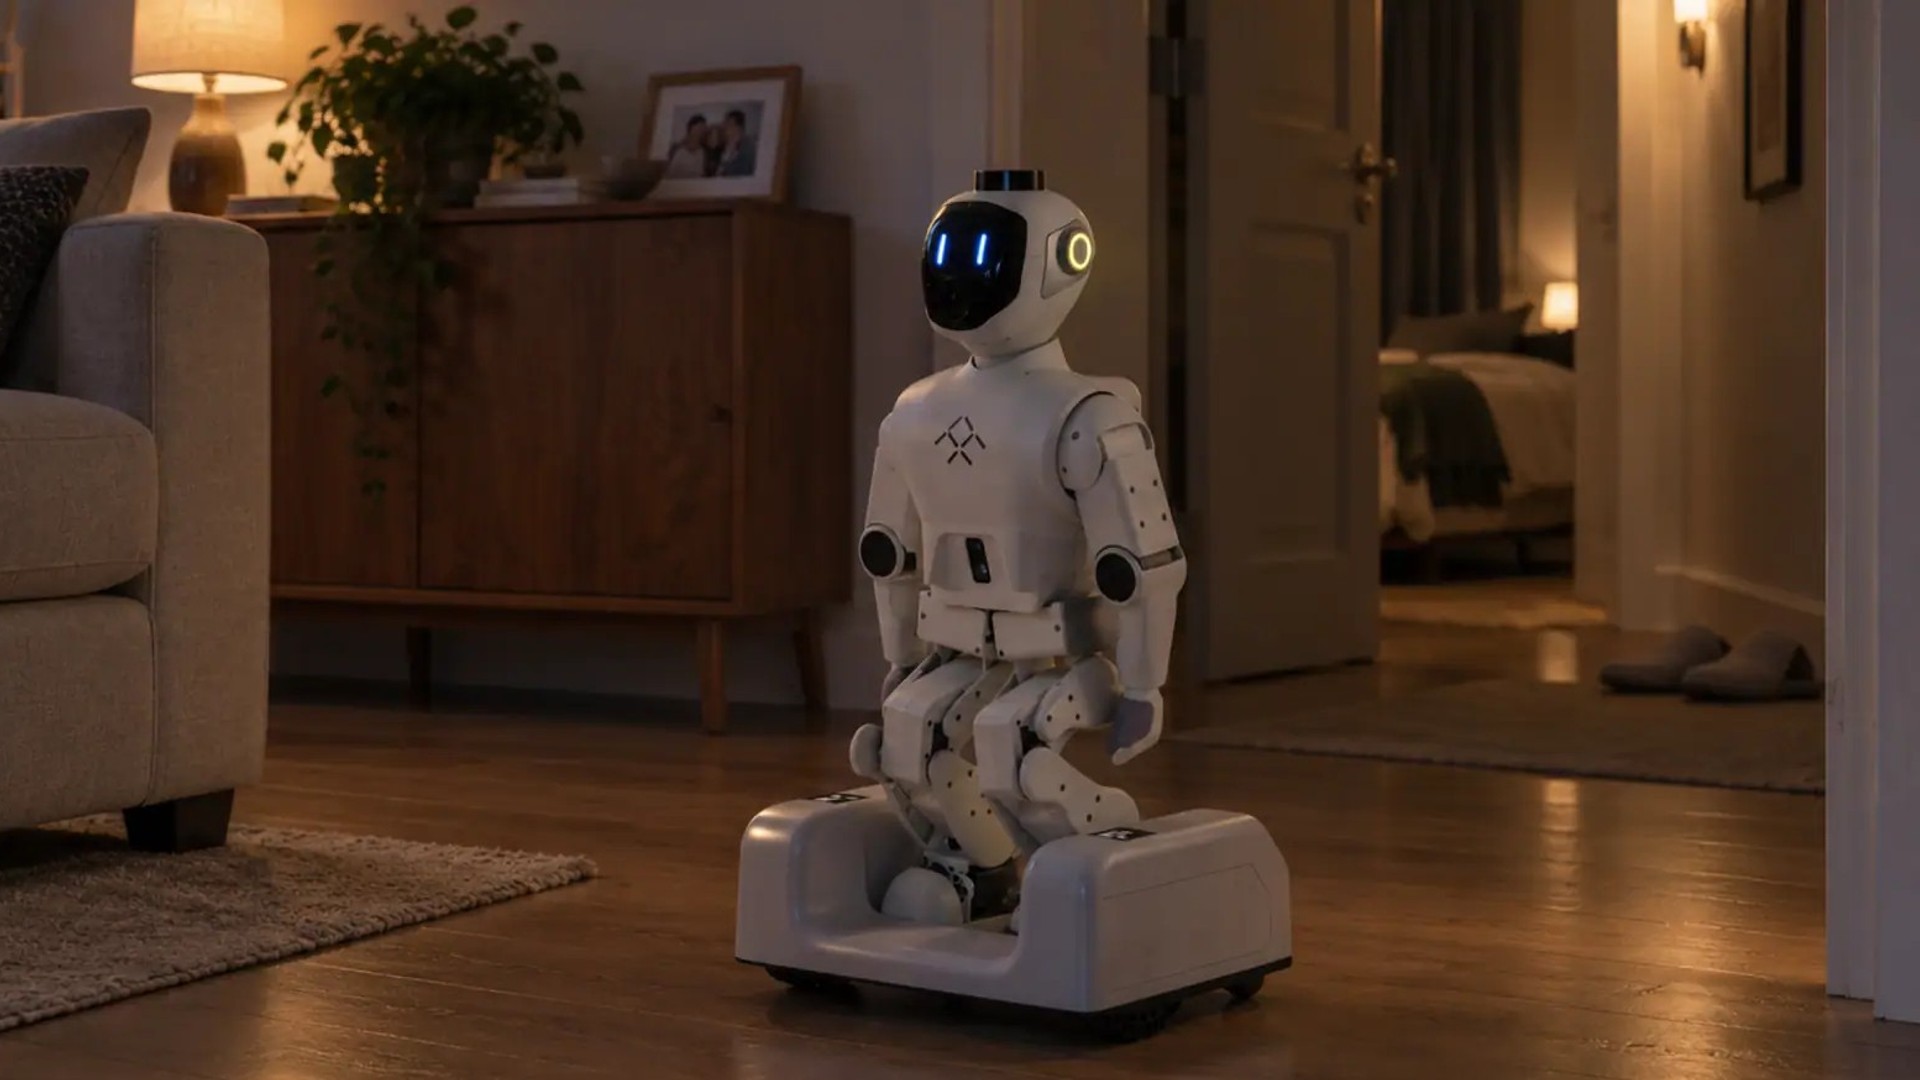
Faraday Future Unveils $2,490 Nova and $299 Nova Mini Humanoid Robots

FF EAI Robotics Ecosystem Inc. and Faraday Future Intelligent Electric Inc. announced on October 15, 2026 the joint launch of FF Nova, an entry-level embodied AI humanoid robot priced at $2,490, and FF Nova Mini, a $299 humanoid for foundational Physical AI education, alongside a new curriculum and developer programs. Both robots join the "One Brain, Multi-forms, Multi-capabilities" FF Robot World 2.0 lineup. The companies describe FF Nova as America's first embodied AI humanoid robot priced…

Read source article
Faraday Future Unveils $2,490 Nova and $299 Nova Mini Humanoid Robots
arXiv cs.AIResearch

The World Won't Wait: Evaluating and Teaching Agents Under a Live Clock

arXiv:2610.20665v1 Announce Type: new Abstract: Large language model (LLM) agents can solve complex interactive tasks, yet reasoning and tool calls take time. In continuously changing environments, an otherwise correct action may arrive too late. We introduce RealtimeBench, with 180 tasks across six game types, to evaluate agents while games continue running during inference. Paired evaluations show that GPT-6.1-sol outperforms the faster Jev when games are paused, but falls behind when they kee

Read source article
arXiv cs.AIResearch

Evaluating Model Capabilities After Benchmark Saturation

arXiv:2610.20667v1 Announce Type: new Abstract: Rapid advances in AI capabilities are causing benchmarks to saturate. Once several models approach perfect scores, a benchmark loses its power to differentiate between them, and with it its utility for informing AI safety cases and frontier policies. Yet benchmark items produce far more information than the scores we typically extract from them: a full transcript of how each model solved the task. We investigate whether these transcripts can be use

Read source article
arXiv cs.AIResearch

Value-Informed Schedule Trimming for Accelerated Sequential Monte Carlo Guidance in Discrete Diffusion

arXiv:2610.20669v1 Announce Type: new Abstract: Reward-guided discrete diffusion enables test-time alignment with downstream objectives, but applying Sequential Monte Carlo (SMC) guidance at every denoising step is computationally expensive. Active guidance steps require additional reward evaluations and, for gradient-based proposals, value-gradient computations. Sparse guidance reduces this cost by guiding only a subset of timesteps, but commonly used schedules are fixed heuristics whose effect

Read source article
arXiv cs.AIResearch

AlphaDiana: A Measurement System for Agents in Verifiable Reasoning Tasks

arXiv:2610.20675v1 Announce Type: new Abstract: Agents pair reasoning models with harnesses that organize model calls, execute tools, load skill instructions, and retain history in memory. Understanding agent performance requires linking execution conditions to outcomes, behavior, and resource use. We introduce AlphaDiana, a measurement system with modular interfaces for datasets, agents, environments, and scorers. It preserves harness-native control loops while controlling file reuse and memory

Read source article
arXiv cs.AIResearch

IneqAgent: Agentic Inequality Proving in Lean with Symbolic Computation

arXiv:2610.20681v1 Announce Type: new Abstract: Formal inequality proving requires mathematical reasoning and exact computation, often connected through intermediate lemmas and goal reformulations. We introduce IneqAgent, an agentic framework combining LLM reasoning with symbolic computation for inequality proving in Lean4. Lemma-level Monte Carlo Tree Search coordinates lemma construction, goal reformulation, and symbolic backend selection. Complementary sum-of-squares, Bernstein, and successiv

Read source article
arXiv cs.AIResearch

L2G-SR: Learning to Guide LLM-based Symbolic Regression

arXiv:2610.20685v1 Announce Type: new Abstract: Symbolic regression searches for an equation that explains observed data. Numerical error is commonly used to guide the search, but it alone can favor an accurate surrogate over a candidate with the right structure. We propose L2G-SR, a framework for LLM-based symbolic regression that guides search with a learned structural verifier. We construct structural supervision signal using tree edit distance (TED), accounting for commutative operators and

Read source article
arXiv cs.AIResearch

When Reality Outpaces Cognition: A New Scaling Principle for Reliable Intelligence

arXiv:2610.20764v1 Announce Type: new Abstract: This paper challenges the understanding capabilities of existing AI paradigms and emerging world models by asking a fundamental question: How quickly can reality change before an intelligent system can no longer reliably perceive, reason, and act? We formulate this as a theory- and model-agnostic challenge in which systems must infer reliable actions for increasingly distant future states across a growing observation--reality gap. We operationalize

Read source article
arXiv cs.AIResearch

ARIA: Runtime Inspection and Amendment for Multi-Agent Systems

arXiv:2610.20780v1 Announce Type: new Abstract: In LLM-based multi-agent systems (MAS), a local mistake can propagate as other agents build on it, turning a correctable error into a failed task. Diagnosing completed runs or repeatedly re-executing them to search for corrections does not provide a learned policy for intervening while execution is still in progress. We present Agent Runtime Inspection and Amendment (ARIA), a framework for learning when and how to repair ongoing multi-agent executi

Read source article
arXiv cs.AIResearch

Open-world AI: a Tale of Three Requirements

arXiv:2610.20782v1 Announce Type: new Abstract: The closed world asks AI for specialized competence and lets it manufacture the iid data its theory assumes: a fixed criterion licenses collecting examples until the task is covered. The open world asks for versatility --- taking up tasks a machine was not built for, from few examples and with little prior from a human designer --- and offers data that is grouped, not shuffled. Its tasks are not known in advance, so a machine must do inference-time

Read source article
arXiv cs.AIResearch

EvolvingBrain: An Adaptive Skill System for Multi-modal Agents Self-Evolution in Open Worlds

arXiv:2610.20786v1 Announce Type: new Abstract: Multi-modal agents have made significant progress in interacting with open worlds. However, their ability to self-evolve remains limited. Supervised fine-tuning enables imitation but not active experience organization, while outcome-based reinforcement learning promotes exploration yet underuses intermediate trajectory information. Therefore, we propose EvolvingBrain, which uses an adaptive skill system as the brain for agent self-evolution, consis

Read source article
arXiv cs.AIResearch

When Reasoning Traces Conflict with Evidence: How Answer Configuration Shapes Evidence Following

arXiv:2610.20805v1 Announce Type: new Abstract: A reasoning trace retained at answer time plays two roles: it can raise accuracy, and it can compete with the current evidence when the two disagree. We disentangle these roles by crossing verified evidence versions with the traces generated from each and answering from the same traces and evidence under two configurations: continuation of the model's own thinking and a separate answer call. Across three model families (gpt-oss, Gemma4, Qwen3) on H

Read source article
arXiv cs.AIResearch

A Self-Improving Agent that Grows its Own DSL: Oracle-Free Operator Induction for Exact Question Answering

arXiv:2610.20809v1 Announce Type: new Abstract: A self-improving agent has to decide which new skills to keep, and in practice it keeps whatever earns a high reward, convinces a judge model, or compresses its library, even when the skill is wrong. That is fine until the answers have to be exactly right: over a table of transactions, a total is either right or wrong. We ask a harder question: can an agent grow what it can compute with no reward, no judge, and no answer key, and still be exactly r

Read source article
arXiv cs.AIResearch

Temporal Specification Guidance for Text-to-Video Generation

arXiv:2610.20822v1 Announce Type: new Abstract: Text-to-video models often generate the visual concepts requested in natural language prompts but fail to satisfy their intended ordering, timing, and persistence requirements. We propose representing these requirements as specifications in a formal Temporal Logic, and introduce Temporal Specification Guidance (TSG), a training-free inference-time framework that turns temporal specifications into executable objectives for guiding video generation d

Read source article
arXiv cs.AIResearch

Confidence-Calibrated Inference Expansion for Evaluator-Guided Test-Time Reasoning

arXiv:2610.20836v1 Announce Type: new Abstract: Evaluator-guided reasoning presents a local control problem at every step: trust the current answer, return a fallback, or spend more inference. We formulate this choice as a compute-aware three-action controller, scoring terminal actions by predicted answer success and expansion by a rollout-based continuation-success surrogate, with compute cost priced explicitly. A local action-gap analysis characterizes when score errors can change a decision,

Read source article
arXiv cs.AIResearch

Evolving Together, Failing Apart: The Skill-Policy Co-evolution Trap in Self-Improving Agents

arXiv:2610.20845v1 Announce Type: new Abstract: Skill-policy co-evolution, in which an agent's policy model and its skill bank improve each other during training, is a promising paradigm for self-improving agents. Current evaluations score the co-evolved policy on the final bank it trained with (the delivered bank). After deployment, however, skills may be rewritten, added or removed more frequently than the policy model is retrained, leaving the policy to operate on a drifted skill bank that ne

Read source article
arXiv cs.AIResearch

A Multi-Tiered AI Accessibility Model (MAIAM): Proportionate Access and Capability Limits for Comprehensive Frontier AI Safety

arXiv:2610.20921v1 Announce Type: new Abstract: Most debate about releasing capable AI systems treats the choice as binary: keep the model behind an API, or publish the weights. That framing runs together two separate decisions. One is how capable a system may become. The other is who may obtain a given capability, and on what terms. This paper is about the second decision. We propose a Multi-Tiered AI Accessibility Model (MAIAM) that sorts access by purpose, safety, and capability instead of by

Read source article
arXiv cs.AIResearch

SkillNEO: Non-Elitist Evolutionary Optimization of Agent Skills

arXiv:2610.20926v1 Announce Type: new Abstract: Agent skills turn procedural knowledge into reusable artifacts, allowing LLM agents to accumulate and refine expertise through experience. Building on this, skill evolution iteratively improves skills using execution feedback. However, improvement may require several interdependent edits, so low-reward versions can still be worth developing. Requiring immediate reward gains can discard useful partial repairs before their benefits emerge. Non-elitis

Read source article
arXiv cs.AIResearch

RAC: A Relational Agent Contract for Constraint-Governed Engineering Tasks

arXiv:2610.20935v1 Announce Type: new Abstract: Engineering agents must produce artifacts that satisfy exact, coupled constraints. Existing solutions often require agents to make semantic decisions and also derive consequences such as precise geometry or timing from those decisions, leading to failures in constraint-governed engineering tasks. In this paper, we introduce RAC, a harness-agnostic contract for the action and feedback layer of engineering agents. It specifies authoritative observati

Read source article
arXiv cs.AIResearch

MAI-Gym: An Open All-in-One Platform for GUI Agent Evaluation and RL Training across Mobile and Computer Environments

arXiv:2610.20939v1 Announce Type: new Abstract: Online reinforcement learning (RL) with verifiable rewards has driven rapid progress in mathematics, coding, and tool use, but scaling this success to GUI agents remains challenging due to the high cost of interactive environments and the scarcity of realistic training tasks. We introduce MAI-Gym, an open all-in-one platform that unifies GUI agent evaluation, data collection, and online RL training across mobile, computer, and web environments. Thr

Read source article
arXiv cs.AIResearch

LEV: Thinking Fast and Deep with Looped Decision Models

arXiv:2610.20951v1 Announce Type: new Abstract: Decision models answer typed questions about an input with one probability per option, computed in a single forward pass without generating text. Like the fast System 1 of dual-process theory, they answer at once, but their depth is fixed at training time, so they spend the same computation on easy and hard questions. Models that reason in generated text can think longer, but they pay for every extra step in decoded tokens. We present LEV, a decisi

Read source article
arXiv cs.CVResearch

Purify Before You Align: Improving Representation Alignment for Diffusion Models

arXiv:2610.20761v1 Announce Type: new Abstract: Representation alignment improves and accelerates diffusion training by encouraging intermediate features to match a pretrained visual encoder. However, standard alignment matches pretrained representations without distinguishing what information may be more useful for generation. We introduce local appearance purification (LAP), which improves generation quality and makes encoders such as MAE more effective alignment targets by removing locally pr

Read source article
arXiv cs.CVResearch

RIGen: Beyond Action Following with Reciprocal Interaction in Generative Gameplay

arXiv:2610.20811v1 Announce Type: new Abstract: Generative gameplay requires more than immediate responses to player actions.Actions should have persistent consequences, while the generated world should act according to its own state and rules, shaping the player's situation and subsequent choices. Video generation captures local dynamics, but limited history, partially observed game state, and the need for contextual behavior decisions make such interactions difficult to sustain through audiovi

Read source article
arXiv cs.CVResearch

Intern Lumina U2: A Multi-Codebook Diffusion Large Language Model for Omni-Visual Understanding and Image Generation

arXiv:2610.20818v1 Announce Type: new Abstract: Unified multimodal generation covers discrete, continuous, and hybrid paradigms. Discrete approaches with single-codebook visual tokenizers align naturally with text modeling but have limited representational capacity. Continuous and hybrid approaches retain richer visual representations, but they model text and images in heterogeneous spaces with different training objectives, potentially introducing optimization conflicts between modalities with

Read source article
arXiv cs.CVResearch

MARS - A foundational map auto-regressor

arXiv:2610.20843v1 Announce Type: new Abstract: Map generation tasks feature extensive non-structural vectorized data (e.g., points, polylines, and polygons) and thus pose significant challenges to common pixel-wise generative models. Conventional approaches use multiple stages, first segmenting these features at the pixel level and then performing vectorized post-processing, with errors and complexity compounding at each stage. Motivated by the recent success of auto-regressive language modelin

Read source article
arXiv cs.CVResearch

DefoliationCAM: An Edge-AI System for Real-Time Insect Defoliation Severity Assessment in Grapevines

arXiv:2610.20879v1 Announce Type: new Abstract: Insect-induced defoliation threatens grapevine health and yield, yet severity assessment relies on subjective manual scouting. We developed DefoliationCAM (D-CAM), a solar-powered edge AI system that estimates canopy defoliation and transmits results via LoRa to a web dashboard. The pipeline uses YOLOX-Nano to localize grapevine cordons in 4K images and a MobileNet-based classifier with lightweight channel attention to classify 320 x 320 pixel patc

Read source article
arXiv cs.CVResearch

Pixels to Tokens: Token Space Efficient Active Learning for Low-Budget Semantic Segmentation

arXiv:2610.20881v1 Announce Type: new Abstract: While foundation models and vision transformers (ViTs) have redefined visual representations, current active learning (AL) strategies for these backbones largely operate at the patch or region level, where annotation requirements remain high due to extensive pixel labeling. Extending ViT-based AL to the pixel-level, low-budget regime is uniquely challenging: with as little as one pixel query per image, a method must simultaneously identify the most

Read source article