AiAnyTool - Best AI Tools Directory and Artificial Intelligence Software Hub Logo
Loading theme toggle
Real-Time Coverage

AI News Today

Live

38689 stories from 30+ sources, refreshed continuously.

arXiv cs.CL (NLP)Research

Backdoor Learning in Language Models and Vision-Language Models

arXiv:2608.18095v1 Announce Type: new Abstract: Recent advances in deep learning have significantly enhanced the capabilities of Natural Language Processing (NLP) and Vision-Language Models (VLMs). However, these advancements come with increased vulnerabilities, notably through backdoor attacks that pose severe security threats. This thesis addresses two critical dimensions of Trustworthy AI and Efficient Multimodal Representation Learning: (1) security through analyzing, detecting, and designin

Read source article
arXiv cs.CL (NLP)Research

FrenchNews-7: Benchmarking Cross-Publisher French News Editorial Desk Classification

arXiv:2608.18097v1 Announce Type: new Abstract: We present FrenchNews-7, a cross-publisher France-based French-language news editorial desk classification benchmark combining a large multi-outlet corpus, a URL-derived seven-class taxonomy, and a fine-tuned CamemBERT classifier. Labels are assigned via a hybrid pipeline combining publisher URL slugs with LLM annotation for structurally ambiguous cases, audited through an inter-rater study (2 humans + 2 LLMs; pairwise $\kappa \geq 0.766$, human--h

Read source article
arXiv cs.CL (NLP)Research

Fractional Decay KV-Cache: Ownership-Aware Memory Management for Improved Inference Relevancy in Dialog Systems

arXiv:2608.18098v1 Announce Type: new Abstract: Key-value (KV) caching is essential for efficient autoregressive inference in transformer based dialog systems, yet existing strategies treat all cached entries uniformly or apply coarse eviction heuristics that fail to adapt as dialog topics evolve. We propose Fractional Decay KV-Cache (FD-KVC), a novel algorithm that maintains a dual-channel scoring mechanism for each cached KV pair: a cumulative attention channel that tracks aggregate importance

Read source article
arXiv cs.CL (NLP)Research

Computational Orientalism: Measuring Structural Discourse Bias in Large Language Models Using the Middle East Cultural Sensitivity Score (MECSS)

arXiv:2608.18100v1 Announce Type: new Abstract: AI systems now shape how hundreds of millions of people learn about cultures other than their own. When someone asks one of these systems about the Middle East, they do not receive neutral facts. They receive a representation shaped by the frameworks embedded in training data, and that data is overwhelmingly Western and English-language. This paper asks whether that representation is Orientalist in Said's sense: whether it denies agency to Middle E

Read source article
arXiv cs.CL (NLP)Research

Stability-Aware Feature Design for Robust Watermark Detection in Machine-Generated Text

arXiv:2608.18102v1 Announce Type: new Abstract: The widespread adoption of large language models (LLMs) has intensified the demand for principled methods to distinguish human from machine-generated text. Watermarking provides a promising avenue, yet existing detectors exhibit sharp performance deterioration under multiple paraphrasing and when applied to shorter texts. We introduce Pattern Stability Score (PSS), a novel detection framework that leverages local statistical features and stability

Read source article
arXiv cs.CL (NLP)Research

DeepTCM1.0: A Multi-Expert AI Agent for Deciphering Mechanisms of Chinese Herbal Formulae Based on General Large Language Models

arXiv:2608.18103v1 Announce Type: new Abstract: Background: Mechanistic elucidation of traditional Chinese medicine (TCM) compound formulas remains a central challenge in the modernization of TCM. Conventional approaches, including data mining and network pharmacology, are insufficient for achieving deep integration between classical TCM theory and modern scientific research. In addition, direct question-answering using general-purpose artificial intelligence large language models is limited by

Read source article
arXiv cs.CL (NLP)Research

StocksTalk: A Voice-Enabled Conversational Agent for Structured Query Generation over Web Data

arXiv:2608.18105v1 Announce Type: new Abstract: StocksTalk is a voice-enabled conversational system for transforming spoken financial screening requests into executable and validated structured queries over real-world market data. The system combines streaming speech recognition, retrieval-augmented constraint extraction, schema-grounded LLM-based SQL generation, rule-based validation, and human-in-the-loop verification within an interactive dashboard. Unlike traditional template-driven financia

Read source article
arXiv cs.CL (NLP)Research

Different Facets of Verbalised Overconfidence: an Interpretability Study

arXiv:2608.18106v1 Announce Type: new Abstract: Large language models tend to overconfidence, giving assertive answers when the evidence suggests hedging or abstention. Using controlled reasoning scenarios that manipulate logical necessity and possibility, we study this behavior in Qwen3-4B, across three ways to express uncertainty: verbal epistemic markers, abstention, and numeric confidence scores. Our results confirm this tendency toward overconfidence, particularly when the model is prompted

Read source article
arXiv cs.CL (NLP)Research

Institutional Prestige as Geographic Bias in Large Language Models: Evidence from Three Factorial Experiments with Bootstrap Confidence Intervals

arXiv:2608.18107v1 Announce Type: new Abstract: We investigate whether large language models (LLMs) systematically discriminate in candidate evaluations based on applicant name ethnicity and/or institutional prestige and geographic location. Three factorial experiments are reported (4,320 API calls, four LLMs, five professional domains). Study 1 (3x4 design) finds a statistically robust institution-tier gradient of +0.297 points on a 10-point scale (95% bootstrap CI: +0.175 to +0.422), while nam

Read source article
arXiv cs.CL (NLP)Research

Same Facts, Different Updates: Inference Setup Shapes LLM Behavior in Medical Allocation

arXiv:2608.18108v1 Announce Type: new Abstract: Large language models are being incorporated into sensitive and important decision-making processes across nearly all fields. While prior work studies model bias around inputs and scenario framing, models can also behave in unexpected and undesirable ways due to context accumulated over their deployment. In this work, we study a medical example in which a model is asked to assign resource-allocation probabilities to two people given brief clinical

Read source article
arXiv cs.CL (NLP)Research

Temporal Multi-Signal Fusion for Token-Level Hallucination Detection

arXiv:2608.18115v1 Announce Type: new Abstract: Token-level hallucination detectors score each token independently from a single signal, and fail exactly when the generating model is confidently wrong. This paper instead treats hallucination as a temporally extended span and detects it by sequence labeling: each token is scored from a 33-dimensional feature stream that fuses text statistics, Natural Language Inference (NLI) entailment, and language model surprisal, with no access to model intern

Read source article
arXiv cs.CL (NLP)Research

You Are What You Prompt: Prompt Quality, Domain Shift, and Uncertainty in Agrifood Vision-Language Models

arXiv:2608.18116v1 Announce Type: new Abstract: Vision-language models enable zero-shot classification through natural language prompts, but performance is sensitive to prompt formulation, especially in specialized domains. Zero-shot Prompt Ensembling (ZPE) addresses this by weighting prompts by discriminative signal, yet its behavior under domain shift remains unexplored. We evaluate ZPE in the agrifood domain using CLIP and SigLIP across four datasets and four prompt pools, spanning in-distrib

Read source article
arXiv cs.CL (NLP)Research

Alignment Is All You Need: Instruction-Free Training for General Audio-Language Models

arXiv:2608.18132v1 Announce Type: new Abstract: Multimodal large language models (MLLMs) are typically built through a multi-stage pipeline consisting of cross-modal alignment, supervised fine-tuning (SFT), and preference optimization. This pipeline assumes that adapting an LLM to a new modality requires extensive task-specific supervision. However, pretrained LLMs already possess strong reasoning and instruction-following abilities. As LLMs evolve rapidly, an important question remains: can we

Read source article
arXiv cs.CL (NLP)Research

The Deontic Gap: Large Language Models and the Modal Language of Obligation

arXiv:2608.18144v1 Announce Type: new Abstract: Modal auxiliaries such as must, should, and have to mark necessity and obligation within the contexts of speaker authority and interpersonal stance. We examine whether large language models (LLMs) reproduce contemporary human patterns of deontic modal usage. Across three primary corpora, an external benchmark, two controlled replications, and a naturalistic eleven-model replication, AI-generated text consistently underuses positive deontic modals (

Read source article
arXiv cs.CL (NLP)Research

When Do LLMs Actually Help? Evaluating LLMs as Data Quality Annotators

arXiv:2608.18158v1 Announce Type: new Abstract: LLMs have been increasingly used to catch data quality issues automatically, but we know very little about how consistent these judgments actually are. This study tests an LLM on two e-commerce data quality tasks, entity matching and brand mislabeling, against rule based baselines and human verified ground truth, under both zero-shot and few-shot prompting. On entity matching while using the Abt Buy benchmark (2,194 labeled pairs), a simple rule ba

Read source article
arXiv cs.CL (NLP)Research

Are LLMs Safe Beyond Text: Do Emojis Expose Gaps in Safety Evaluation

arXiv:2608.18164v1 Announce Type: new Abstract: Safety evaluations of large language models (LLMs) predominantly rely on text-based adversarial prompts, potentially overlooking vulnerabilities arising from alternative input representations. This work examines emoji-augmented prompts as a test case for this gap, evaluating 50 prompts across four open-source LLMs (Mistral 7B, Qwen 2 7B, Gemma 2 9B, Llama 3 8B). Results show substantial variation in robustness: Gemma 2 9B and Mistral 7B exhibit non

Read source article
Vercel Blog

How v0 authenticates to Snowflake without exposing the user's OAuth token

AI-generated applications often need to authenticate to external services on behalf of their users. That creates a problem: generated code shouldn't have access to the user's credentials. We faced that decision when building the v0 Snowflake integration . It lets users connect Snowflake, inspect schemas, query data, and generate applications that run against their warehouses. That generated code has to authenticate to Snowflake, but it is written by a model and runs without human review, and pro

Read source article
Hacker News LLMLLMs

Misconfigured Admin System Prompts Can Invert an LLM's Safety Layer

Article URL: https://medium.com/@aadvait.cr/how-misconfigured-admin-system-prompts-can-invert-every-single-llm-safety-layer-1085a1d79b55 Comments URL: https://news.ycombinator.com/item?id=49369538 Points: 1 # Comments: 0

Read source article
The Guardian AIBusiness

UC Berkeley professor admits to using AI to edit op-ed on students’ math skills

<p>Zvezdelina Stankova says she used AI to ‘help edit’ an article about some of her students being ‘five to eight years’ behind</p><p>A math professor at the University of <a href="https://www.theguardian.com/us-news/california">California</a>, Berkeley, criticizing a “severe” math deficiency among students in an <a href="https://sfstandard.com/opinion/2026/08/15/uc-berkeley-sat-test-blind-admissions-math-scores/">op-ed for the San Francisco Standard</a>, admitted to <a href="https://www.dailyca

Read source article
UC Berkeley professor admits to using AI to edit op-ed on students’ math skills
Artificial Intelligence News — Newsletter on Deep Learning & AI

AI Weekly Issue #524: What AI models are actually coming in the next six months?

If you use AI at work, the tools you rely on could change again before February. OpenAI, Google, Meta, Anthropic, several Chinese labs, and a group of world-model startups are all preparing or rumored to be preparing new releases. Some have announced dates. Others have only appeared in testing reports, leaks, or investor comments. This issue sorts those signals into a practical list: what is likely to ship, what will probably slip, and which releases might actually be worth changing your plans f

Read source article
Apple Machine LearningResearch

Multilingual Knowledge Transfer under Data Constraints via Lexical Interventions

Cross-lingual knowledge transfer is critical for building high-performing multilingual language models for languages with insufficient training data. When target language data is scarce, the knowledge required for many downstream tasks involving scientific reasoning, commonsense inference, and world knowledge must be acquired primarily from the high-resource language, making effective knowledge transfer essential. Existing methods for improving such cross-lingual knowledge transfer require large

Read source article
Apple Machine LearningResearch

Scaling Laws for Mixture Pretraining Under Data Constraints

As language models scale, the amount of data they require grows – yet many target data sources, such as low-resource languages or specialized domains, are inherently limited in size. A common strategy is to mix this scarce but valuable target data with abundant generic data, which presents a fundamental trade-off: too little target data in the mixture underexposes the model to the target domain, while too much target data repeats the same examples excessively, yielding diminishing returns and ev

Read source article
Apple Machine LearningResearch

Progressive Refinement: An Iterative Pseudo-Labeling Approach for Mandarin-English Code-Switching ASR

Code-switching (CS), alternating languages within the same utterance, poses significant challenges for automatic speech recognition (ASR) due to limited CS training data. This paper applies an iterative pseudo-labeling training approach to CS-ASR for the first time, demonstrating its effectiveness in leveraging unlabeled data to improve CS-ASR performance. The approach comprises three phases: pseudo-label generation, two-stage bilingual model training, and iterative improvements. It begins by ge

Read source article
Stripe Blog

Five monetization trends from global pricing leaders

As AI transforms software economics, the standard revenue playbook is breaking down. Learn how leaders around the world are preparing for agent buyers, updating processes for faster pricing iteration, and building more flexible infrastructure.

Read source article
Five monetization trends from global pricing leaders
Vercel Blog

Vercel Agent is now available in Slack code channels

Vercel Agent now works in Slack code channels, a new kind of channel launched today for working with a coding agent. Anyone in the channel can follow the work, give Agent new instructions, and review the code it writes. Choose Create a code channel from the Slack sidebar, select Vercel as the agent, and describe what you need to get started. You can also ask Agent to create one from an existing channel or thread. It brings that context with it to the new channel. Use code channels to investigate

Read source article
Product Hunt — The best new products, every day

Shape

<p> The agentic IDE for designers and programmers </p> <p> <a href="https://www.producthunt.com/products/shape-5?utm_campaign=producthunt-atom-posts-feed&utm_medium=rss-feed&utm_source=producthunt-atom-posts-feed">Discussion</a> | <a href="https://www.producthunt.com/r/p/1227189?app_id=339">Link</a> </p>

Read source article
Backlinko

7 Website Marketing Strategies for 2026

Website marketing in 2026 no longer works the way it used to. Traditionally, it meant promoting your site to attract visitors and turn them into customers. Your website is still central. But much of the customer journey now happens beyond it. Before someone visits your site, they’ve often already checked AI tools, Reddit threads, and … The post 7 Website Marketing Strategies for 2026 appeared first on Backlinko .

Read source article
7 Website Marketing Strategies for 2026
VentureBeat

TrueFoundry's open source AI agent harness TrueForge boasts 30%-75% cheaper task completion than Claude Managed Agents

Another day, another new AI agent harness is released. Only this time, it's one that aims to solve a growing enterprise problem as AI agents proliferate: enabling greater developer control of agents and tools, while reducing cost. TrueFoundry , a San Francisco B2B machine learning startup co-founded in 2021 by former Meta engineers, has released its own custom TrueForge harness under the permissive MIT License on Github . Thus, it can be used with any of a developer (or their parent enterprise's

Read source article
TrueFoundry's open source AI agent harness TrueForge boasts 30%-75% cheaper task completion than Claude Managed Agents
Simon WillisonLLMs

smolmachines / smolvm as a sandbox for untrusted Python & JavaScript

<p><strong>Research:</strong> <a href="https://github.com/simonw/research/tree/main/smolmachines-untrusted-sandbox#readme">smolmachines / smolvm as a sandbox for untrusted Python & JavaScript</a></p> <p>I tasked Claude Fable 5 running in Claude Code for web with the following research task:</p> <blockquote> <p><code>Put https://smolmachines.com through its paces as a fast secure sandbox. Explore what it would take to use this to run untrusted Python and JavaScript code in a way that is limited i

Read source article
Product Hunt — The best new products, every day

Plow Latch - Local AI Desktop Manager

<p> Safely drive your Mac with AI (Live demo in comments) </p> <p> <a href="https://www.producthunt.com/products/plow-latch?utm_campaign=producthunt-atom-posts-feed&utm_medium=rss-feed&utm_source=producthunt-atom-posts-feed">Discussion</a> | <a href="https://www.producthunt.com/r/p/1227181?app_id=339">Link</a> </p>

Read source article
Unite.AI

Hyve Solutions Picks Nevada for Two AI Server Manufacturing Campuses

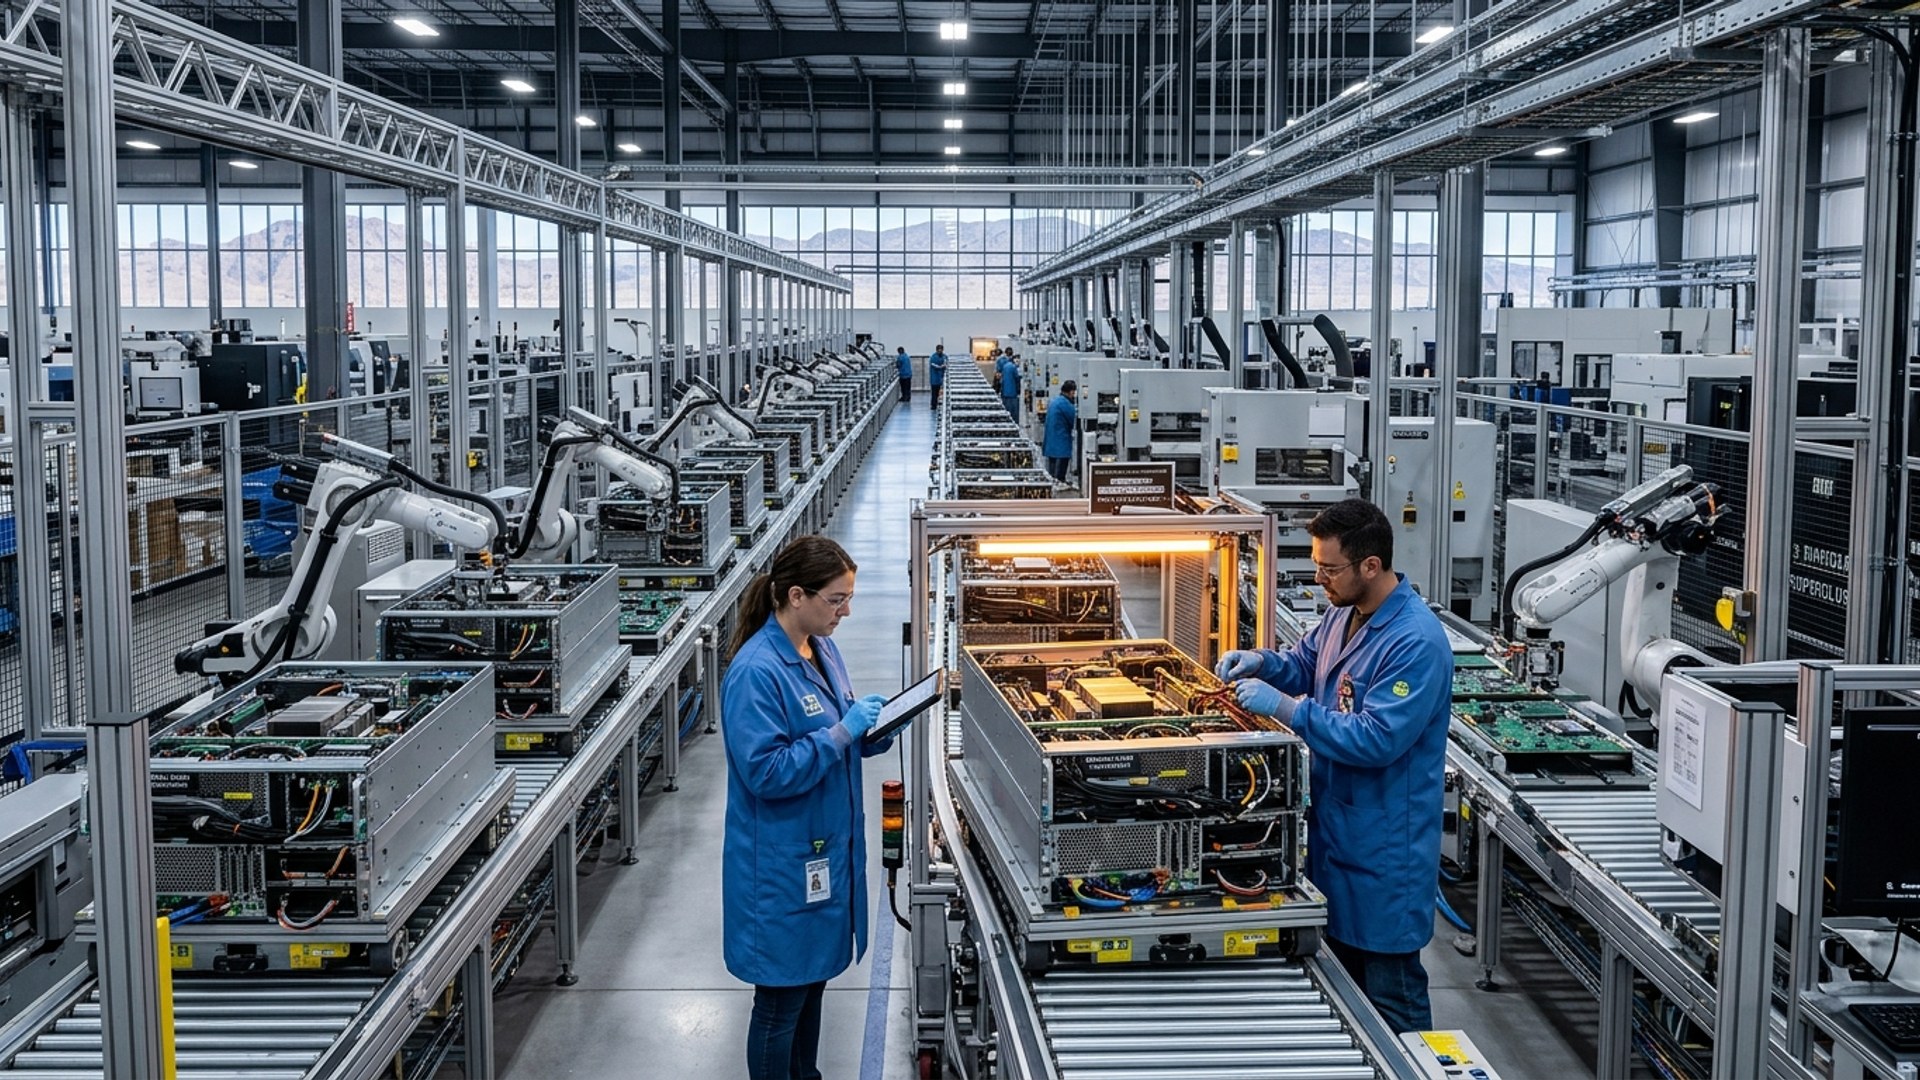
Hyve Solutions, the server design and manufacturing arm of TD SYNNEX, announced on August 19, 2026 that it will build two advanced manufacturing campuses in Nevada (a 624,000-square-foot flagship site in Reno and a second facility in North Las Vegas) to expand U.S. production of the compute, storage, and networking systems that feed AI data centers. Together, the two campuses are expected to create approximately 3,000 jobs. The announcement lands two weeks after the Nevada Governor's Office of…

Read source article
Hyve Solutions Picks Nevada for Two AI Server Manufacturing Campuses
Simon WillisonLLMs

Conceptual integrity and counting lines of code

<p>Last week I recorded <a href="https://talkingpostgres.com/episodes/how-ai-is-changing-software-development-with-simon-willison">an episode of the Talking Postgres podcast</a> with Claire Giordano on the subject of "How AI is changing software development". We had a really great conversation. Here are a couple of my highlights from a lightly edited transcript (prompt to Claude: "very minor edits to remove disfluencies").</p> <p>This is the latest version of an argument I've been trying to buil

Read source article
AWS Machine Learning Blog

Domain and publish date filters for Web Search on AgentCore

Web Search on Amazon Bedrock AgentCore now supports runtime domain and published-date filtering. New per-request filters give developers per-call control over which web sources their agents consult and how fresh those sources must be, all enforced server-side. This release also expands Web Search to the Europe (Ireland) and Asia Pacific (Tokyo) Regions.

Read source article