AiAnyTool - Best AI Tools Directory and Artificial Intelligence Software Hub Logo
Loading theme toggle
Real-Time Coverage

AI News Today

Live

31934 stories from 30+ sources, refreshed continuously.

Product Hunt — The best new products, every day

AI Eyes

<p> Permission-first real-time senses for AI companions </p> <p> <a href="https://www.producthunt.com/products/ai-eyes-2?utm_campaign=producthunt-atom-posts-feed&utm_medium=rss-feed&utm_source=producthunt-atom-posts-feed">Discussion</a> | <a href="https://www.producthunt.com/r/p/1204377?app_id=339">Link</a> </p>

Read source article
Product Hunt — The best new products, every day

Chimlo

<p> Track Codex and Claude Code and respond from your Notch </p> <p> <a href="https://www.producthunt.com/products/chimlo-agents-in-your-macbook-notch?utm_campaign=producthunt-atom-posts-feed&utm_medium=rss-feed&utm_source=producthunt-atom-posts-feed">Discussion</a> | <a href="https://www.producthunt.com/r/p/1204290?app_id=339">Link</a> </p>

Read source article
r/MachineLearningResearch

Real task cost across GPT, Claude, Gemini and Kimi, 10.6x spread on models with only 2x price difference [R]

<table> <tr><td> <a href="https://www.reddit.com/r/MachineLearning/comments/1v450o3/real_task_cost_across_gpt_claude_gemini_and_kimi/"> <img src="https://preview.redd.it/7ejtvp684xeh1.png?width=140&height=65&auto=webp&s=10790ba444afd733ece8c54a8b9da99969a86066" alt="Real task cost across GPT, Claude, Gemini and Kimi, 10.6x spread on models with only 2x price difference [R]" title="Real task cost across GPT, Claude, Gemini and Kimi, 10.6x spread on models with only 2x price difference [R]" /> </a

Read source article
Real task cost across GPT, Claude, Gemini and Kimi, 10.6x spread on models with only 2x price difference [R]
arXiv cs.CL (NLP)Research

Stateful Guardrails for Multi-Turn LLM Systems: A Conversational Risk Accumulation Framework

arXiv:2607.19361v1 Announce Type: new Abstract: Most safety guardrails for large language models (LLMs) evaluate each prompt-response pair in isolation, which misses failures that arise only over a dialogue as benign turns compose into harm. We term this Conversational Risk Accumulation (CRA): gradual intent drift, fragmented assembly of prohibited instructions, and sensitivity build-up from repeated disclosures. We propose a session-layer CRA Framework that tracks three trajectory signals: sema

Read source article
arXiv cs.CL (NLP)Research

When Reasoning Narrows the Move: Diversity Collapse in LLM Game Play

arXiv:2607.19523v1 Announce Type: new Abstract: Supervised fine-tuning (SFT) is widely used to adapt large language models to downstream tasks, but its effect on behavioral diversity in sequential decision-making remains under-explored. We study this question in a controlled suite of deterministic board games based on tic-tac-toe variants, where optimal actions are exactly computable and diversity can be measured directly. Across state-level evaluation, arena gameplay, and training trajectories,

Read source article
arXiv cs.CL (NLP)Research

Scaling Laws for Hypernetwork-Based Knowledge Injection in Large Language Models

arXiv:2607.19604v1 Announce Type: new Abstract: Injecting factual knowledge into large language models (LLMs) reliably and at scale remains an open challenge. Hypernetworks provide a promising solution to large-scale knowledge injection. Although hypernetworks are typically applied for test-time adaptation, we explore their use in train-time knowledge injection, where, given a large corpus of facts, we train a hypernetwork to generate a fixed LoRA adapter that, when inserted into the target mode

Read source article
arXiv cs.CL (NLP)Research

Adaptive Capitulation: A Structural Failure Mode of LLM Responses in Vulnerability Contexts

arXiv:2607.19629v1 Announce Type: new Abstract: Large language models operating in emotionally sensitive contexts face a structural trilemma: when users in vulnerable states request information that may reinforce maladaptive attribution, current response architectures resolve the tension through protective restriction, uninflected facilitation, or unintegrated co-presence of both imperatives -- each preserving one objective at the cost of the other. Administering a three-turn escalating vulnerab

Read source article
arXiv cs.CL (NLP)Research

Reference-Free Evaluation of Reasoning in Open-Ended Question Answering

arXiv:2607.19678v1 Announce Type: new Abstract: AI-generated answers in high-stakes domains are often fluent but difficult to verify, especially when they contain multi-step reasoning rather than a single final answer. We propose a reasoning-based, reference-free framework for auditing LLM-generated outputs. The method decomposes a generated reasoning trace into segments, labels local premise-target relations using Natural Language Inference (NLI), and organizes these relations into a hypergraph

Read source article
arXiv cs.CL (NLP)Research

Multi-Mask Diffusion Language Models for Few-Step Generation

arXiv:2607.19686v1 Announce Type: new Abstract: Masked diffusion models (MDMs) are a promising family of language generators, but achieving high-quality few-step generation remains challenging. In MDMs, all forward trajectories collapse to a single fully masked state, leaving no terminal entropy for consistency-style few-step generation. While recent few-step alternatives based on uniform-state diffusion avoid this degeneracy, it becomes harder to distinguish clean tokens from noise than MDMs, w

Read source article
arXiv cs.CL (NLP)Research

Beyond Relevance-Centric Retrieval: Rubric-Oriented Document Set Selection and Ranking

arXiv:2607.19747v1 Announce Type: new Abstract: As large language models and AI agents become the primary consumers of search results, document set quality determines the upper bound of downstream generation. Yet existing evaluation systems remain confined to scoring documents independently and aggregating via nDCG, ignoring inter-document interactions (redundancy, conflict, complementarity) and unable to answer what makes one document set better than another. To address these issues, we propose

Read source article
arXiv cs.CL (NLP)Research

Learning the Arabic Dialect Continuum as a Continuous Space: A Regression Approach to Speaker Origin Prediction

arXiv:2607.19751v1 Announce Type: new Abstract: We present a regression-based approach to Arabic dialect geolocation that models dialectal variation as a continuous geographic space rather than discrete categories. Speaker origin is predicted as continuous latitude-longitude coordinates using a hierarchical neural architecture that fuses frame-level XLS-R-300M and Whisper-large-v3 encoder representations with phonotactic descriptors through a Transformer encoder and a learnable attention-pooled

Read source article
arXiv cs.CL (NLP)Research

TriAgent: Divergence-Aware Multi-Agent Committees for Cost-Efficient Financial Sentiment Analysis

arXiv:2607.19794v1 Announce Type: new Abstract: Production LLM-based financial sentiment analysis faces a structural cost trap: most queries are trivially classifiable, yet expensive cloud reasoners process them all, and the bill scales linearly with user count. We present TriAgent, a multi-agent committee stratified by contextual granularity -- a word-level lexicon (VADER), a sentence-level domain transformer (FinBERT), and a cross-sentence reasoner (Qwen2.5, 0.5B-14B-4bit, with Mistral-7B and

Read source article
arXiv cs.CL (NLP)Research

VizRAG: Enhancing Retrieval-Augmented Generation with Hypergraph Visualization

arXiv:2607.19830v1 Announce Type: new Abstract: Hypergraph-based RAG systems surpass traditional graph-based approaches by organizing complex n-ary atomic facts among entities, rather than relying solely on binary relationships. Despite the advancements in multimodal large language models (MLLMs) with enhanced visual capabilities, current hypergraph-based RAG frameworks predominantly restrict knowledge retrieval and reconstruction to a unimodal, text-centric paradigm. This limitation prevents th

Read source article
arXiv cs.CL (NLP)Research

D2VBench: Benchmarking Large Language Models with Value Dilemmas in Daily Scenarios

arXiv:2607.19834v1 Announce Type: new Abstract: With the wide application of large language models (LLMs) in real-world scenarios, the value implication of their outputs is crucial. However, existing evaluation benchmarks suffer from insufficient coverage of value dilemmas in daily scenarios involving multiple value conflicts and simplistic evaluation formalisms that fail to assess LLMs' value alignment. To address these issues, we propose D2VBench, a value alignment benchmark comprising 10,000

Read source article
arXiv cs.CL (NLP)Research

emb-diversity: A Tool for Embedding-Based Measurement of Data Diversity

arXiv:2607.19848v1 Announce Type: new Abstract: There is growing evidence that data diversity is crucial for developing fair and robust NLP models. However, current approaches to measure diversity remain inconsistent and fragmented: While there exist a number of tools for measuring the lexical diversity of texts, researchers lack standardized tools for quantifying diversity based on embeddings. Embedding-based diversity measures are highly flexible: They work with any embedding model and any dat

Read source article
arXiv cs.CL (NLP)Research

Efficient Chain-of-Modality Reasoning via Progressive Compression for Spoken Language Models

arXiv:2607.19932v1 Announce Type: new Abstract: Spoken language models (SLMs) enable natural human-computer interaction, but their reasoning ability still lags behind that of text-based large language models, especially on spoken mathematical question answering tasks. One important reason is that SLMs reason over purely verbalized mathematical expressions, which are harder to interpret than symbolic text. However, directly transferring text-based reasoning to SLMs is nontrivial due to architectu

Read source article
arXiv cs.CL (NLP)Research

When Does Knowledge Distillation Hurt? Reliability-Aware Distillation for Low-Resource Language Summarization

arXiv:2607.19956v1 Announce Type: new Abstract: Knowledge distillation (KD) is a standard approach for compressing sequence-to-sequence models, but its per-sample effects are rarely examined. On the BanSum Bangla summarization benchmark, we find that standard KD improves ROUGE-L by only +0.0003 over a cross-entropy baseline, and that approximately 51.3% of training samples are estimated to actively harm student validation loss under standard KD. We propose two complementary reliability-aware dis

Read source article
arXiv cs.CL (NLP)Research

TINY_SCHILLER: A Drop-In German Drama Corpus for Small Language Models

arXiv:2607.19992v1 Announce Type: new Abstract: tiny_schiller closes the small-language-model prototyping, fine-tuning, education, and research gap for German literary text, providing a single-file, drop-in counterpart to Karpathy's tiny_shakespeare. The available German literary corpora are larger and richer, but require parser engineering before a single line of training or fine-tuning code can run. tiny_schiller is a 2.07-megabyte single file of eleven public-domain Schiller dramas, sourced f

Read source article
arXiv cs.CL (NLP)Research

TalentCLEF at CLEF2026: Skill and Job Title Intelligence for Human Capital Management

arXiv:2607.20009v1 Announce Type: new Abstract: This paper presents the second edition of the TalentCLEF Challenge, which will run as an evaluation lab as part of CLEF 2026. The aim of TalentCLEF is to promote the development of systems and methods that use Natural Language Processing (NLP) in the field of Human Capital Management (HCM), fostering approaches that ensure fairness in results, operate across multiple languages, and adapt to diverse industries. To this end, TalentCLEF establishes pu

Read source article
arXiv cs.CL (NLP)Research

Solar Open 2 Technical Report

arXiv:2607.20062v1 Announce Type: new Abstract: We present Solar Open 2, a 250B-A15B Mixture-of-Experts language model built for long-horizon agentic tasks, scaled up from Solar Open 1 (Solar Open 100B). To hold entire agent trajectories in a single context, Solar Open 2 reaches a 1M-token window through a hybrid attention stack that interleaves one softmax layer among every three linear-attention layers, using no positional encoding and a gated delta rule extended to negative eigenvalues. To tr

Read source article
arXiv cs.CL (NLP)Research

The Two-Process Theory of Machine Self-Report

arXiv:2607.20082v1 Announce Type: new Abstract: Language models are increasingly asked to self-report, informing safety evaluations, public understanding, and model-welfare debates. Yet their reports are elicited with human questionnaires never validated for models or ad hoc prompts of unknown reliability. We propose the first language-model-specific psychometric theory: a two-process theory of machine self-report. Self-description jointly reflects persona installation, through which post-traini

Read source article
arXiv cs.CL (NLP)Research

Reinforcement Learning for Large Language Model Selective Evidence Adoption from Contaminated Retrieval Results

arXiv:2607.20090v1 Announce Type: new Abstract: Retrieval-augmented large language models frequently face contexts that interleave useful evidence with misleading statements or instruction-like content. Blanket refusal discards valid evidence, whereas uncritical adoption yields incorrect or unsafe answers. The ability to selectively adopt relevant information while rejecting deceptive or harmful content is therefore critical for reliable deployment in real-world retrieval settings. We introduce

Read source article
arXiv cs.CL (NLP)Research

Understanding the Impact of Linguistic Realization Choices on LLM Stance with Causal Tracing

arXiv:2607.20115v1 Announce Type: new Abstract: Large language models (LLMs) are known to be sensitive to prompt and input formulations. However, existing studies have focused on lexical realization and largely ignored constructional choice. This paper studies whether linguistic construction can systematically shift LLM decisions and where these shifts can be causally localized inside the model. We use political stance judgment as a meaning-sensitive case study and extend an English political st

Read source article
Product Hunt — The best new products, every day

HOL Guard

<p> The 1st Firewall for AI Agents </p> <p> <a href="https://www.producthunt.com/products/hol-guard?utm_campaign=producthunt-atom-posts-feed&utm_medium=rss-feed&utm_source=producthunt-atom-posts-feed">Discussion</a> | <a href="https://www.producthunt.com/r/p/1204113?app_id=339">Link</a> </p>

Read source article
NVIDIA BlogResearch

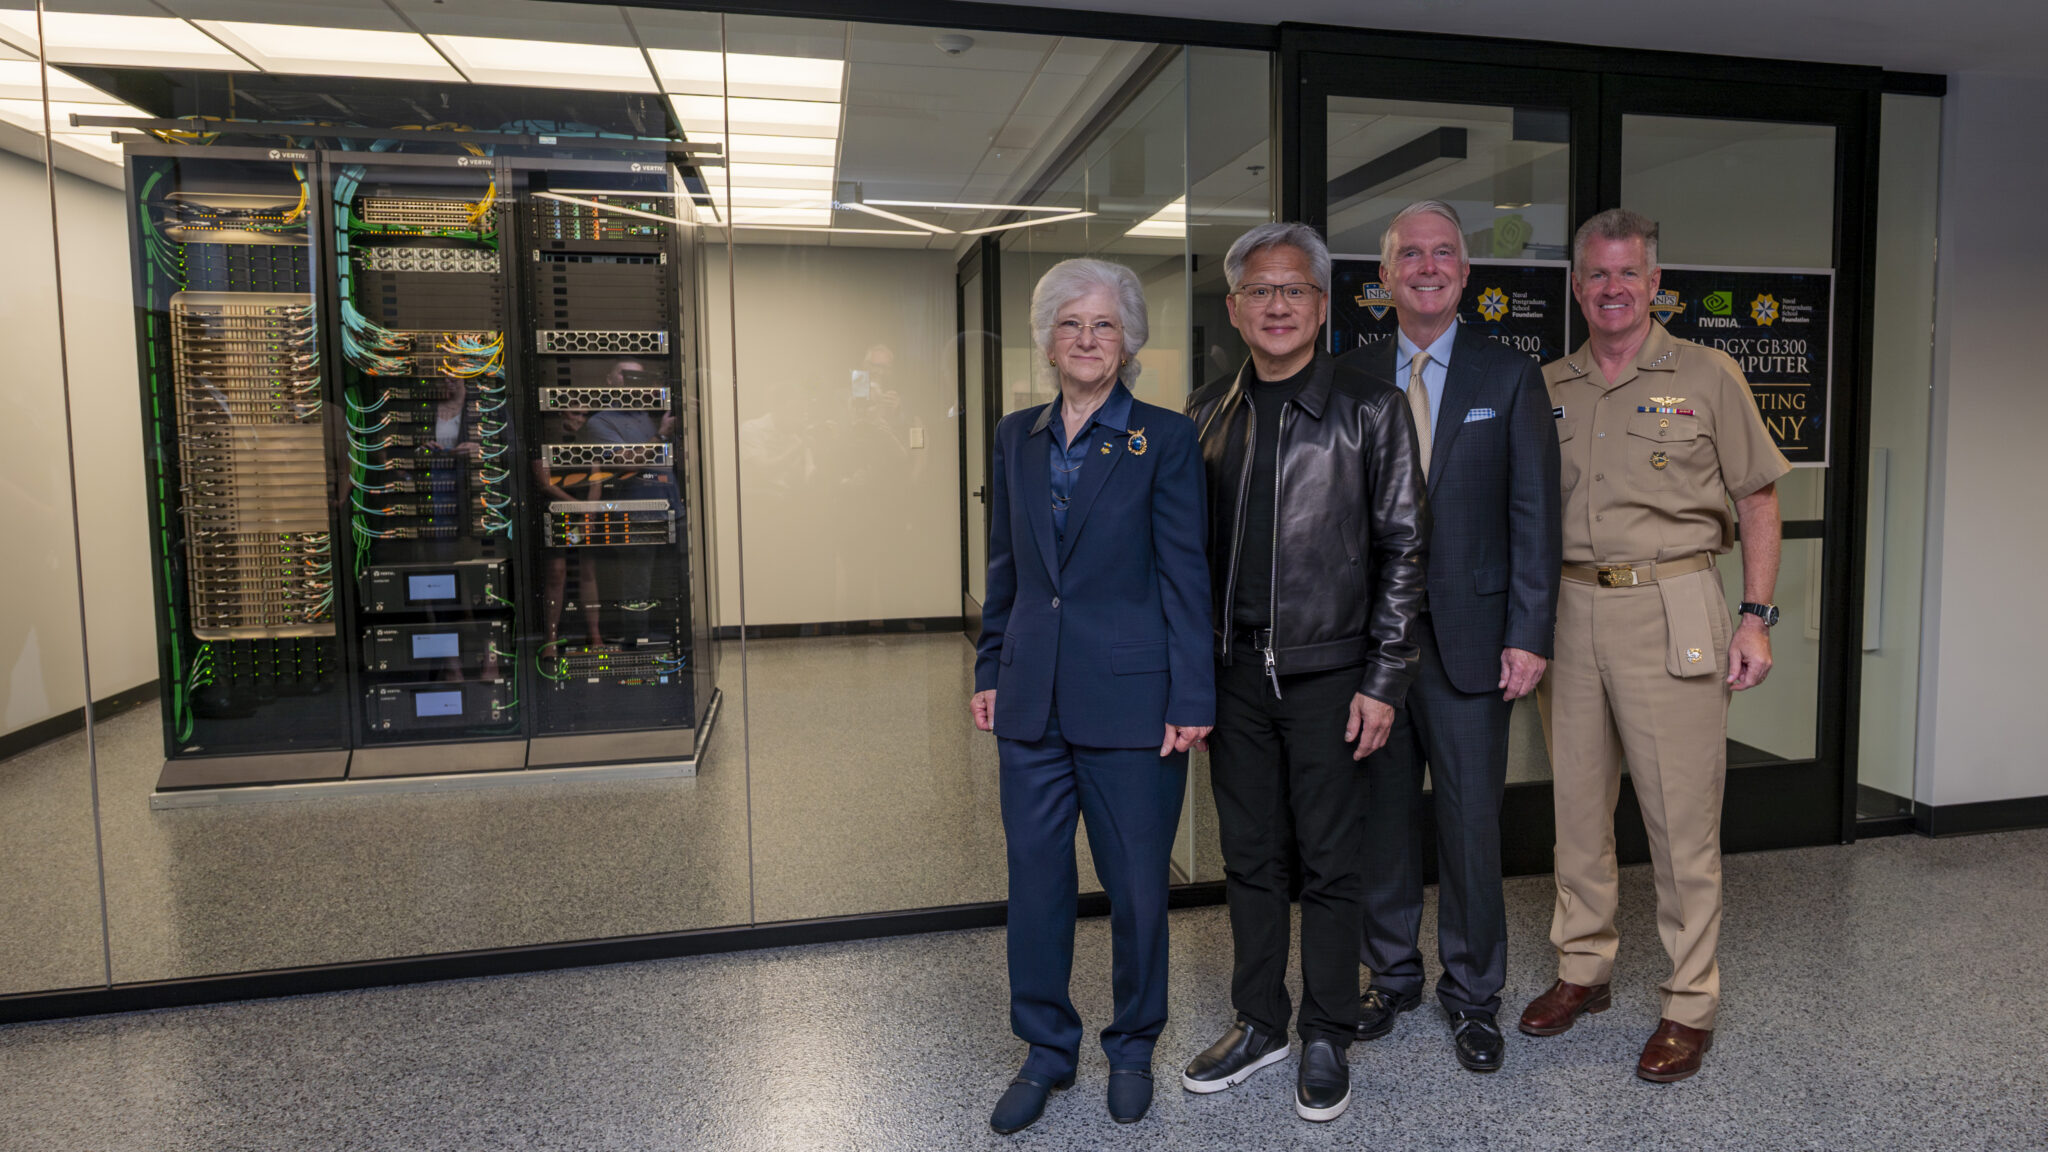
NVIDIA AI Supercomputer Comes Online at Naval Postgraduate School

NVIDIA founder and CEO Jensen Huang today visited the Naval Postgraduate School in Monterey, California, to commission an NVIDIA DGX GB300 system — bringing one of the world’s most powerful AI platforms fully online for the students, researchers and faculty at the U.S. military’s flagship graduate university. “Our nation depends on our men and women […]

Read source article
NVIDIA AI Supercomputer Comes Online at Naval Postgraduate School
Product Hunt — The best new products, every day

Plow Mac App

<p> Run GPT-5.6 on OpenClaw & Hermes safely on your Mac </p> <p> <a href="https://www.producthunt.com/products/plow-mac-app-safely-run-gpt-5-6-agents?utm_campaign=producthunt-atom-posts-feed&utm_medium=rss-feed&utm_source=producthunt-atom-posts-feed">Discussion</a> | <a href="https://www.producthunt.com/r/p/1204092?app_id=339">Link</a> </p>

Read source article
Vercel Blog

GitHub tools are now an installable eve extension

You can now add GitHub tools to your eve agent as an extension . Add the package, drop one file in agent/extensions/ , and your agent gets every tool with Vercel Connect auth, presets, and approval rules built in. Install @github-tools/eve-extension : Then register it from a file in agent/extensions/ : Connector-backed auth: Pass a Vercel Connect connector and the extension mints short-lived, scoped GitHub tokens at runtime. Presets scope the toolset: code-review , issue-triage , repo-explorer ,

Read source article
Vercel Blog

Ling 3.0 Flash is now available on AI Gateway

Ling 3.0 Flash from Ant Group is now available on AI Gateway. The model is free to use for the next three weeks, through August 3rd. Ling 3.0 Flash is a Mixture-of-Experts model with 124B total parameters and about 5.1B active per token. It has a 256K token context window and runs in thinking and non-thinking modes. Ling 3.0 Flash is built for token-efficient agentic inference at production scale, doing more work within tighter token, latency, and cost budgets across multi-step agent runs. The m

Read source article