AiAnyTool - Best AI Tools Directory and Artificial Intelligence Software Hub Logo
Loading theme toggle
Real-Time Coverage

AI News Today

Live

10540 stories from 30+ sources, refreshed continuously.

arXiv cs.AIResearch

Structure and Implementation of New Practical English Textbooks Driven by Artificial Intelligence

arXiv:2609.02981v1 Announce Type: new Abstract: Artificial intelligence is changing the form of applied English materials from fixed paper sequences to adaptive learning systems that can diagnose learners, recommend tasks, and provide formative feedback. This paper studies the structure and application of a new practical English textbook driven by artificial intelligence. A five-layer architecture is proposed: knowledge mapping, learner profiling, task generation, feedback orchestration, and tea

Read source article
arXiv cs.AIResearch

Speculative Macro Commit for Faster Tool-Using Agents

arXiv:2609.03236v1 Announce Type: new Abstract: Tool-using LLM agents spend wall-clock time not only on model inference but also in serial action--observation turns, where each tool call, environment transition, and observation can delay subsequent decisions. We introduce \textbf{Speculative Macro Commit} (SMC), a runtime mechanism for a two-tier agent system: a large authoritative actor model produces the official trajectory, while a faster speculative drafter model continuously predicts and ex

Read source article
arXiv cs.AIResearch

Fresh Memory, Stale Plans: Dependency-Scoped Validation for Distributed LLM-Agent Memory

arXiv:2609.03340v1 Announce Type: new Abstract: Distributed LLM-agent teams can read the latest shared facts and still act on an obsolete plan. A planner may derive an action from requirement $r_3$, another agent may commit $r_4$, and an executor may receive $r_4$ without replacing the plan derived from $r_3$. We call this \emph{stale-plan execution}: state freshness does not establish that the plan authorizing an action remains valid. We introduce PlanFence, a dependency-scoped action-validatio

Read source article
arXiv cs.AIResearch

A Prompt-Engineering Approach to Develop Scalable, Flexible, and Real-Time Hybrid Micro-Level Personalization in a General Purpose AI Teaching Assistant

arXiv:2609.03402v1 Announce Type: new Abstract: Artificial intelligence (AI) teaching assistants powered by large language models (LLMs) offer scalable educational support but often provide limited personalization. This study presents a prompt-engineering-based framework for personalizing general-purpose LLM/RAG-based AI teaching assistants such as Jill Watson across academic disciplines and courses. The framework adapts responses using six learner-specific dimensions: self-assessment, abstracti

Read source article
arXiv cs.AIResearch

Caught in the Story: Narrative Captivity in Multi-turn LLMs Conversation

arXiv:2609.03407v1 Announce Type: new Abstract: People increasingly turn to large language models (LLMs) for everyday advice, making ethically charged interpersonal problems a practical moral-advisory context. Most prior work has studied this context through single-turn judgments or pressure-laden rebuttals, assumptions that poorly match how guidance is sought in real-world contexts. These assumptions leave unclear whether narration alone, without an explicit opposing position, can shift model j

Read source article
arXiv cs.AIResearch

Dude: A Dual-Detection Multi-Agent System for Paper-Code Discrepancy Detection

arXiv:2609.03416v1 Announce Type: new Abstract: LLM-empowered paper-code discrepancy detection has received growing concern since the scaling of research submissions exceeds the manual review capability. However, the limited context capacity and one-sided discrepancy detection of existing single-agent LLM paradigms lead to an inferior recall performance in detecting discrepancies. In this paper, we propose Dude, the first Dual-Detection Multi-Agent System for paper-code discrepancy detection. We

Read source article
arXiv cs.AIResearch

DuplexSpeechBench-IFEval: Evaluating Implicit Instruction Following in Full-Duplex Voice Agents

arXiv:2609.03423v1 Announce Type: new Abstract: Full-duplex voice agents must continuously decide when to listen, backchannel, interrupt, handle speech overlaps, take the floor, and yield. Existing benchmarks largely test these behaviors through explicit turn-management instructions, while deployed agents are often configured through roles or personas from which the appropriate conversational behavior must be inferred. We introduce DuplexSpeechBench-IFEval (DSB-IFEval) for evaluating implicit in

Read source article
arXiv cs.AIResearch

Do GUI Agents Know When Not to Act? Enabling Conflict-Aware Termination for Multimodal GUI Agents

arXiv:2609.03438v1 Announce Type: new Abstract: Graphical user interface (GUI) agents are increasingly used to execute natural-language instructions on user interfaces, yet real users may issue infeasible instructions due to benign mistakes. A reliable agent should not only know how to act, but also when not to act. In this work, we introduce CONFLICTGUI, a benchmark covering instruction-internal conflicts and instruction-GUI context conflicts to study conflict-aware termination. Our evaluation

Read source article
arXiv cs.AIResearch

Beyond "Made with AI": Visualizing Provenance Density to Mitigate the Transparency Penalty

arXiv:2609.03460v1 Announce Type: new Abstract: As generative AI makes polished prose cheap to produce, users can no longer rely on fluency as a proxy for truth. We call this failure mode the Fluency Trap: users trust fluent hallucinations while also discounting accurate content once it is disclosed as AI-generated. Binary ``Made with AI'' labels respond with authorship disclosure, but they do not show what supports a claim. We propose Provenance Density, an evidence-visualization interface that

Read source article
arXiv cs.AIResearch

Making Every Tool Call Count: Necessary Tool-Evidence Path Rewards for Agentic Vision-Language Models

arXiv:2609.03493v1 Announce Type: new Abstract: Modern vision-language models (VLMs) can directly answer many image-grounded questions, yet they often struggle with complex queries requiring fine-grained visual details or external knowledge. To acquire this missing evidence, agentic VLMs invoke tools such as image cropping, image search, and text search. However, existing training paradigms primarily evaluate tool-use based on final answer correctness, leaving evidence acquisition and utilizatio

Read source article
arXiv cs.AIResearch

GrowPage: On-Demand KV Budgeting for Efficient LLM Reasoning Serving

arXiv:2609.03494v1 Announce Type: new Abstract: Long-output reasoning has made the key--value (KV) cache a critical memory bottleneck for efficient LLM serving. Existing KV compression methods usually rely on a predefined per-request budget and adjust only which KV states are retained, leaving the total capacity fixed throughout decoding. However, reasoning workloads exhibit substantial demand variation: different requests require different KV capacities, and the attention demand of an individua

Read source article
arXiv cs.AIResearch

PPO-STGNN: A Proximal Policy Optimization Approach with Spatio-Temporal Graph Neural Networks for DAG Task Scheduling in Cloud-Edge-End Computing

arXiv:2609.03503v1 Announce Type: new Abstract: With the rapid development of the Internet of Things, computation intensive directed acyclic graph (DAG) tasks have become increasingly common in cloud-edge-end collaborative environments. However, cloud, edge, and end nodes are highly heterogeneous in computing capacity, network bandwidth, and energy consumption, which makes the efficient scheduling of tasks with complex dependencies an NP-hard problem. Traditional heuristic algorithms and convent

Read source article
arXiv cs.AIResearch

NeoRed: A Knowledge-Logic-Alignment Multimodal Large Language Model for Neonatal Respiratory Disease Diagnosis

arXiv:2609.03527v1 Announce Type: new Abstract: Neonatal respiratory diseases are a major cause of neonatal morbidity and mortality, posing substantial challenges in clinical practice. Despite recent advances, existing Multimodal Large Language Models (MLLMs) face two key limitations in neonatal diagnosis: (1) domain gap arising from predominantly adult training data; (2) insufficient integration of multidimensional clinical context for accurate diagnosis. To address these challenges, we collect

Read source article
arXiv cs.AIResearch

Dalek: A Constructive Agent Machine

arXiv:2609.03546v1 Announce Type: new Abstract: We present Dalek, a closed machine designed for agents that realizes self-maintenance, self-evolution, self-reproduction, and self-organization on any substrate satisfying a general host contract. The machine is built from three primitives---actors, messages, and channels. Four obligations---a host boundary, a construction language, admissible transitions, and rule heredity---give its boundary, identity, and closure a structural basis. Von Neumann'

Read source article
arXiv cs.AIResearch

GPS-Bench: A Governance Policy Benchmark for Automating Policy Analysis

arXiv:2609.03553v1 Announce Type: new Abstract: Policy analysis requires more than predicting whether a proposal will pass: it requires identifying who will be affected, how those actors respond, and what follows. LLM-based policy simulations model these processes at scale, but their validity is hard to establish when plausible behaviour is never compared with observed outcomes. We introduce GPS-Bench, an evidence-grounded benchmark for governance policy simulation that links policies to relevan

Read source article
arXiv cs.AIResearch

HalluPeer: A Taxonomy-driven Benchmark for Detecting Hallucinations in Scientific Peer Reviews

arXiv:2609.03580v1 Announce Type: new Abstract: The growing scale of academic peer review has motivated the use of Large Language Models (LLMs) as review assistants, yet LLMs can generate fluent but unsupported claims that undermine review reliability. Existing hallucination benchmarks are not designed for peer review, where verification requires grounding claims in long, technical papers. We introduce HalluPeer, a benchmark for detecting hallucinations in scientific peer reviews, providing alig

Read source article
arXiv cs.AIResearch

The Attention Triangle in Audio-Video Models

arXiv:2609.03586v1 Announce Type: new Abstract: Audio-video diffusion models rely on cross-modal attention to coordinate text, sound, and visual content, yet this same mechanism can introduce subtle and systematic semantic leakage. We study these models by probing and analyzing the ``attention triangle,'' comprising the three cross-attention edges connecting the text, audio, and video streams, and examine how semantic information is routed across modalities during generation. Our analysis reveal

Read source article
arXiv cs.AIResearch

KC-Bench: A Dynamic Interactive Benchmark for Evaluating Knowledge Conflicts in LLM Agents

arXiv:2609.03588v1 Announce Type: new Abstract: As LLMs increasingly act through tools, they must reconcile user instructions, parametric knowledge, and dynamic environmental observations before taking actions. We introduce KC-Bench, a controlled multi-turn benchmark for measuring this capability across world-knowledge conflicts, input inconsistencies, and multi-source temporal conflicts. Its 238 tasks are manually screened from more than 1,000 generated candidates and combine a user simulator,

Read source article
arXiv cs.AIResearch

Analysis of Prompt Engineering for Drug Toxicity Prediction

arXiv:2609.03635v1 Announce Type: new Abstract: Clinical trials in the UK can cost up to {\pounds}1.3 million, with approximately 90% drug failure rate. Toxicity is a major contributing factor in drug failure. Testing is time and cost intensive. In recent years, the use of artificial intelligence has been increasingly explored to aid in the prediction of drug toxicity, with extensive use of large language models (LLMs). However, LLMs can show considerable variation when minor changes are made to

Read source article
arXiv cs.AIResearch

Synthetic Semantic Supervision for Contrastive Code Representation Learning in Small Transformers: An Empirical Study

arXiv:2609.03702v1 Announce Type: new Abstract: General-purpose code embeddings power tools for code search, classification, and retrieval. Compact transformer encoders for code typically rely on either human-written docstrings (labor-intensive and inconsistent) or mined structural signals such as execution traces (setting-specific and costly to collect). We empirically study an alternative: contrastive pretraining of small encoders with synthetically generated natural-language descriptions emph

Read source article
MIT Tech ReviewResearch

Architecting memory and storage in the AI era

The era of AI inference has arrived. Imagine a healthcare system analyzing millions of data points in real time to accelerate life-saving medical research, or an intelligent assistant instantly resolving thousands of complex customer needs at once. These real-world breakthroughs rely on advanced infrastructure acting as the engine of continuous intelligence, powering real-time services while…

Read source article
Architecting memory and storage in the AI era
MIT Tech ReviewResearch

The Download: selling battlefield drone data and AI reshaping language

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Data from drones in Ukraine is fueling a new Wild West marketplace —Cory Alpert, a researcher at the University of Melbourne studying AI’s impact on democracy, who previously served in the…

Read source article
The Download: selling battlefield drone data and AI reshaping language
NVIDIA BlogResearch

Sparks Fly: NVIDIA Accelerates Local AI at IFA 2026

Frontier intelligence is going local. At IFA 2026, NVIDIA, Microsoft and its partners are teaming up to provide faster inference and new tools that make agents easier to set up and run locally on NVIDIA hardware. New compact NVIDIA RTX Spark Windows PCs are also coming in October to give AI enthusiasts, developers and creators […]

Read source article
Sparks Fly: NVIDIA Accelerates Local AI at IFA 2026
NVIDIA BlogResearch

‘NBA 2K27’ With NVIDIA DLSS 5 Leads 28 New Games Coming to GeForce NOW

September is here with 28 more games streaming on GeForce NOW this month, led by a slam dunk: NBA 2K27 with the NVIDIA DLSS 5 3D-Guided Neural Rendering feature. Through NVIDIA’s close collaboration with Visual Concepts and 2K, DLSS 5 brings a new level of lifelike lighting and material detail to the court — tuned […]

Read source article
NVIDIA BlogResearch

NVIDIA to Acquire Hugging Face

I’m excited to announce that NVIDIA has agreed to acquire Hugging Face for $12,930,300,000. Together, we will scale Hugging Face’s platform, strengthen its infrastructure and expand access to AI for developers and institutions worldwide. Over the past decade, Clem, Julien, Thomas and the team at Hugging Face have built something remarkable: a vibrant home for […]

Read source article
NVIDIA to Acquire Hugging Face
MIT Tech ReviewResearch

Scaling agentic AI pilots across the enterprise

As agentic AI moves from experimentation toward enterprise deployment, the challenge is figuring out how agents can work together, connect to the systems and data they need, and operate safely across the workflows that run a business. Although agentic AI has been adopted by some 80% of Fortune 500 companies, progress toward meaningful scale remains…

Read source article
Scaling agentic AI pilots across the enterprise
MIT Tech ReviewResearch

Facilitating AI integration with simplicity at scale

As companies scale, the technology supporting operations can become a liability just as quickly as it becomes an asset. Disconnected systems, site-specific tools, spreadsheets, and manual workarounds can create data silos that make it harder to spot problems early, coordinate responses, and make decisions with confidence. For Jabil, a global manufacturing company with more than…

Read source article
IEEE Spectrum AIResearch

AI Efficiency Could Cost Us the Next Generation of Experts

A little over a decade ago, I led the controls design for a first-of-its-kind full digital-control system for a U.S. nuclear plant. It was, on paper, a beautiful machine—engineered to run itself the way a modern airliner does, with operators watching over a system that rarely needed them. And we made a decision that, to an efficiency-minded observer, looked backward: We deliberately left manual steps inside sequences the system could execute on its own. We were solving a specific problem. An ope

Read source article
AI Efficiency Could Cost Us the Next Generation of Experts
MIT Tech ReviewResearch

The Download: AI puzzles and a path to our nearest star system

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. AI models flub these intelligence tests. Can you fare any better? Puzzles and games have always been central to AI development. The term “machine learning” was popularized in a 1959 article…

Read source article
The Download: AI puzzles and a path to our nearest star system
NVIDIA BlogResearch

NVIDIA and CrowdStrike Strengthen Agentic Cybersecurity Frontier

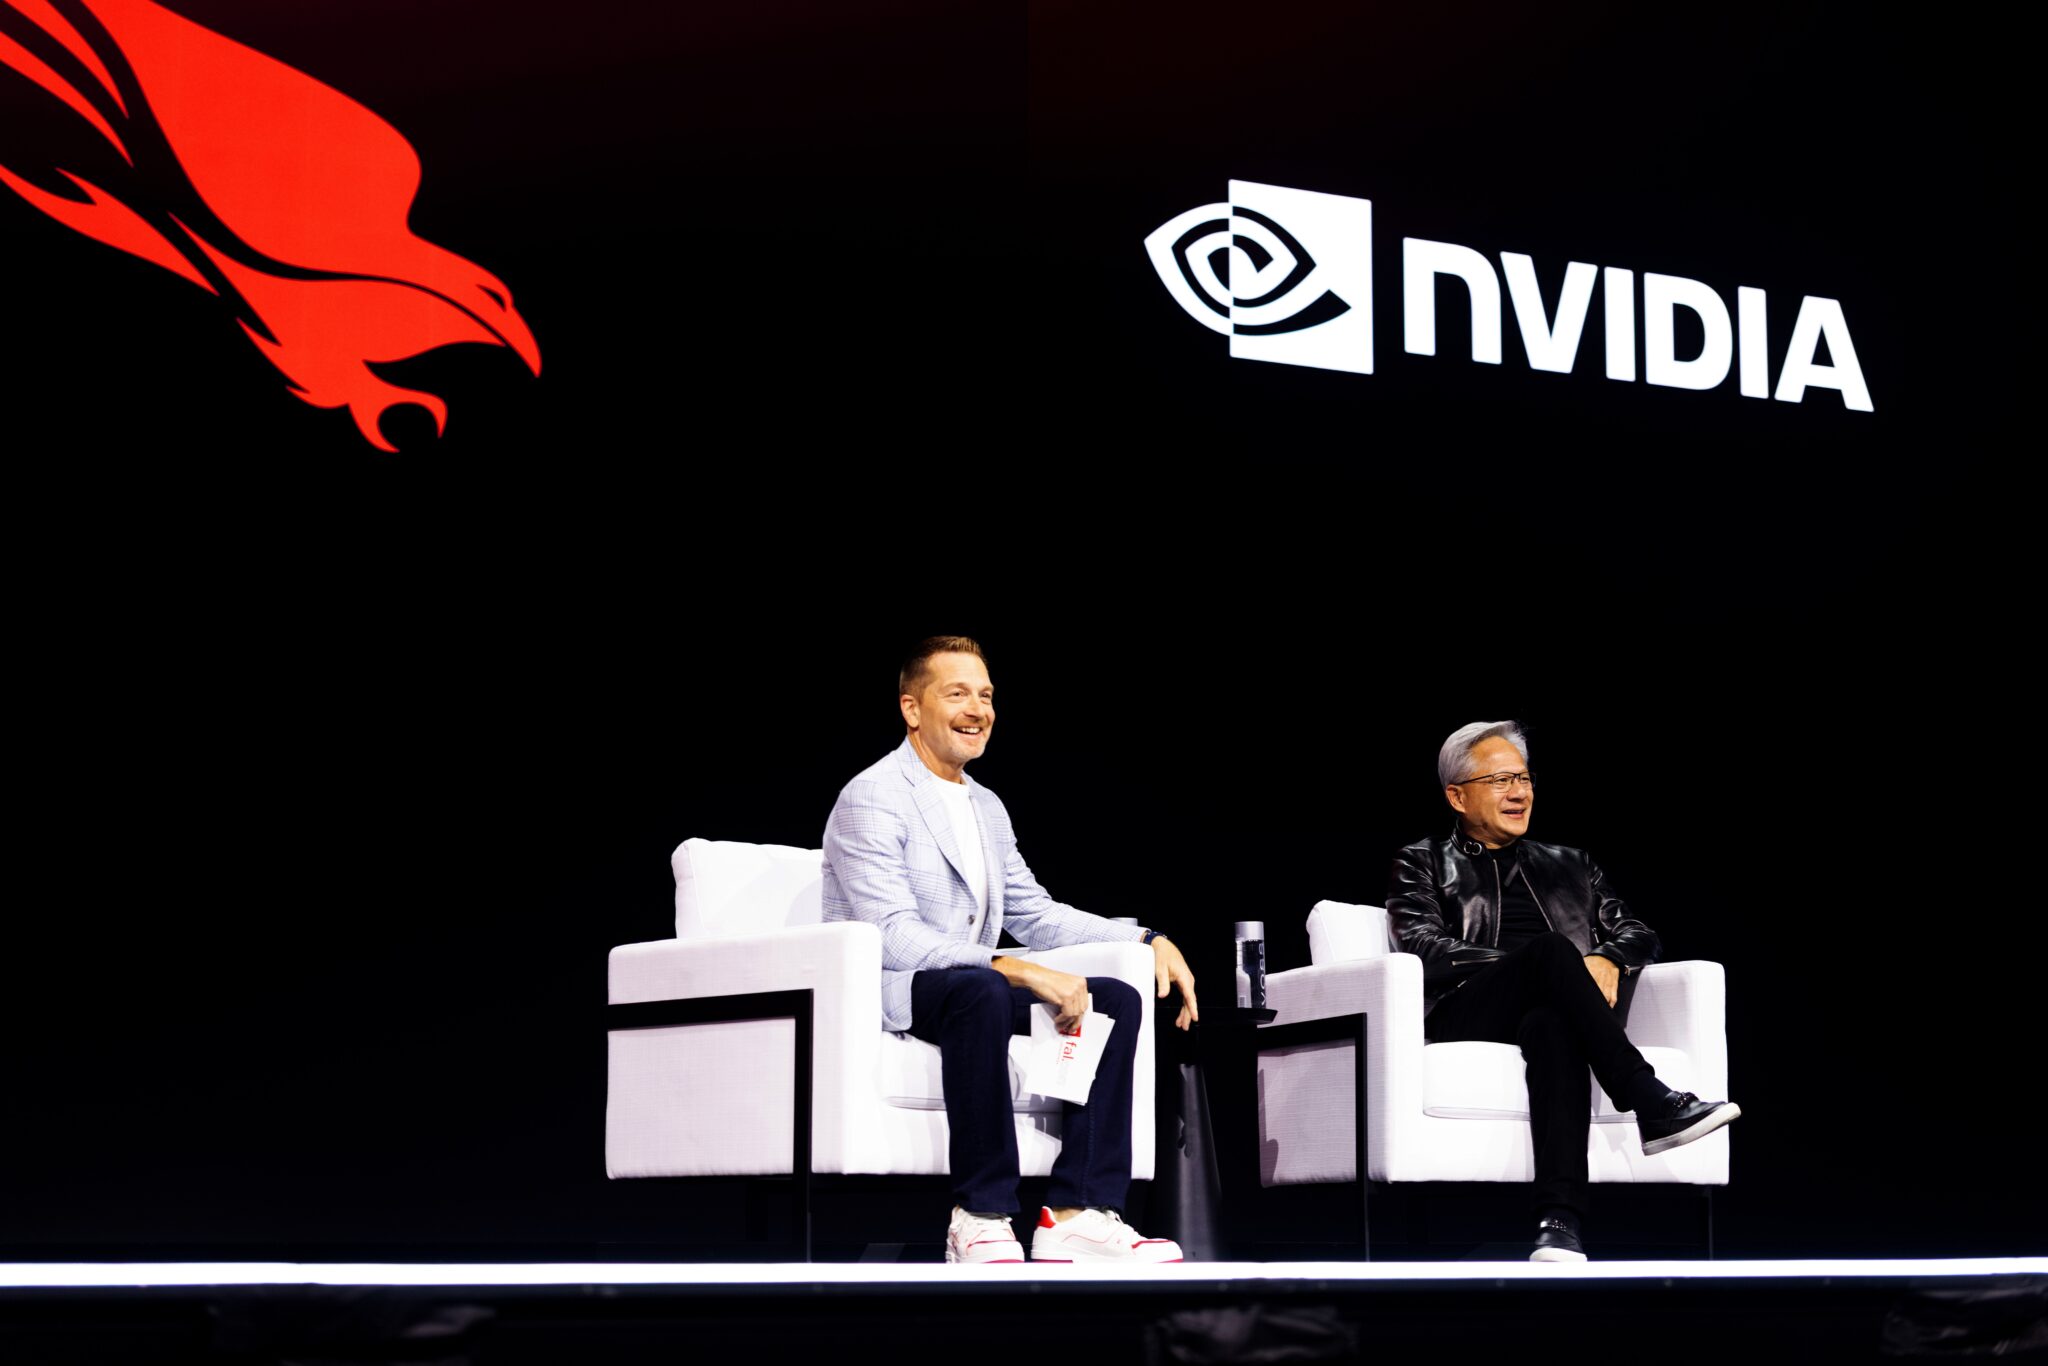
“We’re at an inflection point in cybersecurity,” Jensen Huang told a sold-out crowd at CrowdStrike’s Fal.Con 2026 in Las Vegas Tuesday. Attacks are now automated. Defense has to be, too. The NVIDIA founder and CEO joined CrowdStrike CEO and founder George Kurtz to announce CrowdStrike SafeMind, its agentic cybersecurity system developed by the CrowdStrike Cyber […]

Read source article
NVIDIA and CrowdStrike Strengthen Agentic Cybersecurity Frontier
MIT Tech ReviewResearch

How AI plotted an interstellar journey to Alpha Centauri

A nonprofit organization called the Fermi Explorer Mission announced today that it intends to launch a spacecraft to our nearest star system by the end of 2029. It’s a hugely ambitious mission—if all goes well, the spacecraft could take up to 80,000 years to arrive at Alpha Centauri, which is 4.4 light-years away. And the…

Read source article
IEEE Spectrum AIResearch

Cash in on the AI Boom by Renting Out Your Spare Compute

If you own an at-home server, a gaming computer, or just a laptop that doesn’t get much love, listen up. You can now put that spare computing power to use and earn some passive income in the process. AI companies are hungry for more compute to run AI inference—the process of using a pre-trained model to respond to queries—and they’re willing to pay you for it. “Imagine Uber or Airbnb, but for AI inference computing tasks,” says Ilman Shazhaev , founder and CEO of Far Labs , based in Abu Dhabi. T

Read source article
Cash in on the AI Boom by Renting Out Your Spare Compute
MIT Tech ReviewResearch

Making the AI-powered case for legacy modernization

For years, legacy technology has been a problem companies knew they needed to solve, but one they often struggled to tackle. The cost, complexity, and risk of replacing business-critical systems could make modernization feel like a disruption to manage instead of an opportunity to pursue. But with the rise in customer expectations and the changes…

Read source article
MIT Tech ReviewResearch

The Download: engineered microbes for crops, and OpenAI’s culture problem

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. How engineered microbes could help feed the world’s crops Fertilizer is crucial for the global food supply, but making it uses a lot of energy and produces a lot of emissions.…

Read source article
The Download: engineered microbes for crops, and OpenAI’s culture problem
arXiv cs.CL (NLP)Research

NLP-Driven Knowledge Extraction and Thematic Classification of Translated Ancient Indian Medical Texts

arXiv:2608.28608v1 Announce Type: new Abstract: Ancient Indian medical texts like Sushruta Samhita have extensive information on diseases, treatments, and surgical techniques. Yet, their ancient format and use of intricate vocabulary pose difficulties in accessibility and systematic ordering. The research here utilizes Natural Language Processing (NLP) methods like Named Entity Recognition (NER), BERTopic modeling, and Knowledge Graph development in Neo4j to extract, categorize, and visualize im

Read source article
arXiv cs.CL (NLP)Research

Parametric Multimodal User Memory: Storing What Captions Cannot Carry

arXiv:2608.28609v1 Announce Type: new Abstract: A personalized agent needs a user memory: a persistent model of who its user is. Today it is almost always text -- transcripts and captions retrieved by similarity. This serves the captionable half of a person ("my cat is named Bibi"), but discards the perceptual half no caption can hold: how a voice sounds, how a face reads across age and lighting, how tired someone sounds. We measure this loss across five modalities: a strong caption-based re-ide

Read source article
arXiv cs.CL (NLP)Research

Gurukul AI: An Interactive AI-Driven Educational Platform for Indian Education System

arXiv:2608.28611v1 Announce Type: new Abstract: Recent advances in large language models (LLMs) like ChatGPT and LLaMA have transformed AI-driven education, but these systems are predominantly trained on Western-centric data, making them ill-suited for regional curricula like India's. The Indian education system is linguistically diverse, exam-oriented, and structured around standardized syllabi, not addressed by existing datasets or tools. In this work, we curate a syllabus-aligned QA dataset b

Read source article
arXiv cs.CL (NLP)Research

From GenAI Virtual Patient Dialogue Logs to Teacher-Interpretable Process Evidence: A Learning Analytics Study in Higher Education

arXiv:2608.28619v1 Announce Type: new Abstract: Medical history taking is a dialogue-based clinical reasoning task in which learners must gather, organise, and integrate patient information while the consultation unfolds. Generative AI-powered virtual patients (GenAI VPs) make repeated history taking practice scalable and preserve full turn by turn dialogue. However, these logs are educationally difficult to use directly. Complete transcripts are too detailed for routine teacher review, whereas

Read source article
arXiv cs.CL (NLP)Research

MA-RAG: Multi-Agent Retrieval-Augmented Generation for Query-Driven Summarization of Longitudinal Parkinson's Disease Assessments

arXiv:2608.28624v1 Announce Type: new Abstract: Accurate interpretation of single-visit and longitudinal clinical assessments for Parkinson's disease is time-consuming and often depends on specialist expertise. Although large language models (LLMs) can generate natural language summaries, they frequently lack domain-specific clinical grounding and struggle to produce factually correct and temporally consistent responses for structured longitudinal assessment data. To address these limitations, w

Read source article