AiAnyTool - Best AI Tools Directory and Artificial Intelligence Software Hub Logo
Loading theme toggle
Real-Time Coverage

AI News Today

Live

11932 stories from 30+ sources, refreshed continuously.

arXiv cs.CL (NLP)Research

Can professional translators identify machine-generated text?

arXiv:2601.15828v5 Announce Type: replace Abstract: This study investigates whether professional translators without prior specialized training can reliably identify short stories generated in Italian by artificial intelligence (AI). Sixty-nine translators took part in an in-person experiment, where they assessed three anonymized short stories - two written by ChatGPT-4o and one by a human author. For each story, participants rated the likelihood of AI authorship and provided justifications for

Read source article
arXiv cs.CL (NLP)Research

Jacobian Scopes: token-level causal attributions in LLMs

arXiv:2601.16407v3 Announce Type: replace Abstract: Large language models (LLMs) make next-token predictions based on clues present in their context, such as semantic descriptions and in-context examples. Yet, elucidating which prior tokens most strongly influence a given prediction remains challenging due to the proliferation of layers and attention heads in modern architectures. We propose Jacobian Scopes, a suite of gradient-based, token-level causal attribution methods for interpreting LLM p

Read source article
arXiv cs.CL (NLP)Research

Large Language Model Agents Are Not Always Faithful Self-Evolvers

arXiv:2601.22436v3 Announce Type: replace Abstract: Self-evolving large language model (LLM) agents continually improve by accumulating and reusing past experience, yet it remains unclear whether they faithfully rely on that experience to guide their behavior. We present the first systematic investigation of experience faithfulness, the causal dependence of an agent's decisions on the experience it is given, in self-evolving LLM agents. Using controlled causal interventions on both raw and conde

Read source article
arXiv cs.CL (NLP)Research

Residual Context Diffusion Language Models

arXiv:2601.22954v2 Announce Type: replace Abstract: Diffusion Large Language Models (dLLMs) have emerged as a promising alternative to purely autoregressive language models because they can decode multiple tokens in parallel. However, state-of-the-art block-wise dLLMs rely on a "remasking" mechanism that decodes only the most confident tokens and discards the rest, effectively wasting computation. We demonstrate that recycling computation from the discarded tokens is beneficial, as these tokens

Read source article
arXiv cs.CL (NLP)Research

C2-Faith: Benchmarking LLM Judges for Causal and Coverage Faithfulness in Chain-of-Thought Reasoning

arXiv:2603.05167v2 Announce Type: replace Abstract: Large language models (LLMs) are increasingly used as judges of chain-of-thought (CoT) reasoning, yet it remains unclear whether they can reliably assess process faithfulness rather than merely answer plausibility. We introduce C2-Faith, a benchmark built from PRM800K that explicitly decomposes faithfulness into two complementary dimensions: causality (whether each step logically follows from prior context) and coverage (whether essential inter

Read source article
arXiv cs.CL (NLP)Research

ClaimFlow: Tracing the Evolution of Scientific Claims in NLP

arXiv:2603.16073v2 Announce Type: replace Abstract: Scientific papers advance $\textit{claims}$ that later work supports, extends, or sometimes refutes. Yet existing methods for citation and claim analysis capture only fragments of this dialogue. In this work, we make these interactions explicit at the level of individual scientific claims. We introduce $\texttt{ClaimFlow}$, a claim-centric view of the NLP literature, built from $1{,}617$ ACL Anthology papers $(1979 - 2025)$ that are manually an

Read source article
arXiv cs.CL (NLP)Research

Did You Forget What I Asked? Prospective Memory Failures in Large Language Models

arXiv:2603.23530v2 Announce Type: replace Abstract: Large language models often fail to satisfy formatting instructions when they must simultaneously perform demanding tasks. We study this behaviour through a prospective memory inspired lens from cognitive psychology, using a controlled paradigm that combines verifiable formatting constraints with benchmark tasks of increasing complexity. Across three model families and over 8,000 prompts, compliance drops by 2-21% under concurrent task load. Vu

Read source article
arXiv cs.CL (NLP)Research

Independent-Component-Based Encoding Models of Brain Activity During Story Comprehension

arXiv:2604.24942v2 Announce Type: replace Abstract: Encoding models provide a powerful framework for linking continuous stimulus features to neural activity; however, traditional voxelwise approaches are limited by measurement noise, inter-subject variability, and redundancy arising from spatially correlated voxels encoding overlapping neural signals. Here, we propose an independent component (IC)-based encoding framework that dissociates stimulus-driven and noise-driven signals in fMRI data. We

Read source article
arXiv cs.CL (NLP)Research

An Empirical Study of Automating Agent Evaluation

arXiv:2605.11378v2 Announce Type: replace Abstract: Agent evaluation requires assessing complex multi-step behaviors involving tool use and intermediate reasoning, making it costly and expertise-intensive. A natural question arises: can frontier coding assistants reliably automate this evaluation process? Our study shows that simply prompting coding assistants is insufficient for this task. Without domain-specific evaluation knowledge, frontier coding assistants achieve only a 30% execution succ

Read source article
arXiv cs.CL (NLP)Research

Manga109-v2026: Revisiting Manga109 Annotations for Modern Manga Understanding

arXiv:2605.21182v2 Announce Type: replace Abstract: Manga is a culturally distinctive multimodal medium and one of the most influential forms of Japanese popular culture. As AI systems increasingly target manga understanding, OCR, and translation, Manga109 has become a foundational dataset for manga-related AI research. However, the current Manga109 dataset contains inaccurate transcriptions and coarse annotations, which do not align well with modern OCR and multimodal manga understanding tasks.

Read source article
arXiv cs.CL (NLP)Research

"I Didn't Make the Micro Decisions": Measuring, Inducing, and Exposing Goal-Level AI Contributions in Collaboration

arXiv:2605.21363v2 Announce Type: replace Abstract: As large language models (LLMs) increasingly shape how users form, refine, and extend their goals, attributing contributions in human-AI collaboration becomes critical for users calibrating their own reliance and for evaluators assessing AI-assisted work. Yet existing methods focus on final artifacts, missing the process through which goals themselves are jointly shaped. We introduce a goal-level attribution framework, CoTrace, that decomposes

Read source article
arXiv cs.CL (NLP)Research

Models That Know How Evaluations Are Designed Score Safer

arXiv:2605.28591v3 Announce Type: replace Abstract: The validity of AI safety evaluations depends on models behaving consistently across controlled and deployment settings. Prior work has identified test-time contextual cues, such as hypothetical scenarios, as a source of verbalized evaluation awareness and subsequent behavioral shift. In this paper, we investigate a potential explanation of this phenomenon: evaluation meta-knowledge, defined as parametric knowledge about the structural traits t

Read source article
arXiv cs.CL (NLP)Research

MineExplorer: Evaluating Open-World Exploration of MLLM Agents in Minecraft

arXiv:2605.30931v2 Announce Type: replace Abstract: Multimodal large language models (MLLMs) have shown strong capabilities in perception, reasoning, and action generation. However, their ability to sustain exploration in dynamic open worlds remains unclear. Existing embodied and game-based benchmarks often compress interaction into short-horizon tasks or entangle success with domain-specific game mechanics. In this paper, we introduce MineExplorer benchmark for evaluating open-world exploration

Read source article
arXiv cs.CL (NLP)Research

TVIR: Building Deep Research Agents Towards Text-Visual Interleaved Report Generation

arXiv:2606.02320v2 Announce Type: replace Abstract: Deep Research Agents have shown strong capability in multi-step information retrieval, reasoning, and long-form report generation, but existing benchmarks and systems remain predominantly text-centric, with limited evaluation of whether visual elements are factually reliable and well aligned with the surrounding analysis. To address this gap, we introduce TVIR (Text-Visual Interleaved Report Generation), which includes TVIR-Bench, a benchmark o

Read source article
arXiv cs.CL (NLP)Research

Optimizing the Cost-Quality Tradeoff of Agentic Theorem Provers in Lean

arXiv:2606.04883v2 Announce Type: replace Abstract: Large language models (LLMs) are increasingly used in workflows for generating formal proofs in Lean. These workflows often decompose problems into smaller lemmas, sample many proof attempts, and use compiler feedback to guide search. However, they can be prohibitively expensive, often spending substantial compute on attempts that ultimately fail. In this work, we address this problem with an action routing agent that consists of a data plane a

Read source article
arXiv cs.CL (NLP)Research

TA-RAG: Tone-Aware Retrieval-Augmented Generation for Peer-Support Health Communication

arXiv:2606.06794v2 Announce Type: replace Abstract: Retrieval-augmented generation (RAG) successfully grounds large language model (LLM) outputs in trusted documents, but factual grounding alone is insufficient for sensitive peer-support health communication. In domains such as HIV peer support, responses must also be accessible, stigma-free, empathetic, and tailored to the recipient. This paper presents TA-RAG, a lightweight, prompt-based tone-aware RAG framework that embeds explicit tone contr

Read source article
arXiv cs.CL (NLP)Research

Beyond Rubrics: Exploration-Guided Evaluation Skills for Reward Modeling

arXiv:2606.07040v2 Announce Type: replace Abstract: Open-ended reward modeling requires judges that can follow subtle, domain-specific preferences when verifiable answers are unavailable. Existing rubric-based methods often address this by generating criteria online for each query, but the extra generation step can add inference overhead and produce rigid or misaligned guidance. We introduce Eval-Skill, an exploration-guided method that synthesizes reusable evaluation skills for reward modeling

Read source article
arXiv cs.CL (NLP)Research

Direct Preference Optimization for Chatbot Fine-Tuning: An Empirical Study

arXiv:2606.12881v2 Announce Type: replace Abstract: We present an approach to fine-tuning large language models using Direct Preference Optimization (DPO), a reinforcement learning technique. Our experimental results demonstrate that DPO simplifies the training pipeline, improves computational efficiency, and achieves competitive performance. The evaluation using BLEU, ROUGE, and cosine similarity metrics indicates effective learning and convergence, though further investigation is needed to add

Read source article
arXiv cs.CL (NLP)Research

Multi-Turn Reasoning When Context Arrives in Pieces: Scalable Sharding and Memory-Augmented RL

arXiv:2606.12941v2 Announce Type: replace Abstract: When a user reveals task-critical information across several conversation turns, LLM accuracy drops by up to 65% despite full context availability. We show that this Lost in Conversation degradation can be substantially mitigated by training models to maintain a compact rolling memory instead of attending to a growing history. To make such training scalable, we introduce a low-cost sharding pipeline that converts single-turn QA datasets into mu

Read source article
r/MachineLearningResearch

ICML Poster [D]

Does anyone know when is the ICML poster deadline? It says it’s tomorrow but is it AoE? submitted by /u/misplacedlion [link] [comments]

Read source article
r/MachineLearningResearch

Coherent Context Can Silently Shift LLMs Into a Different Internal Regime — And Current Safety Systems Are Blind To It [D]

I’m an independent researcher currently exploring what I believe is an important phenomenon for both mechanistic interpretability and AI safety. Core idea: A strong, coherent target text can move the model into a different internal regime — before the final output is produced. The model can still appear to behave normally, follow instructions, and pass existing safety filters, yet its hidden states and residual strea

Read source article
r/MachineLearningResearch

Confused, where to start [D]

Hello community, I am a backend + big data dev. I want to learn about the llms that generate voices. I also read some articles but almost everyone of them starts from regression. There are so much resources available right now that I am now confused where to begin with. submitted by /u/paklupapito007 <a href="https://www.reddit.com/r/MachineLearning/comments/1u5cimu/

Read source article
r/MachineLearningResearch

The Verifier Tax: Horizon-Dependent Safety–Success Tradeoffs in Tool-Using LLM Agents [R]

We recently presented a paper at ACM CAIS 2026 on safety evaluation for tool-using LLM agents. The core issue is that task completion alone can be misleading: an agent may complete a task while violating a safety or policy constraint. We separate outcomes into safe success , unsafe success , and failure , and study how verification changes this tradeoff. We evaluate this using τ-bench / Tau-be

Read source article
r/MachineLearningResearch

I’m building a free bilingual machine-learning notebook course — looking for feedback on structure and coverage [R]

Hi everyone, I’m building an open-source machine-learning tutorial repository in Jupyter Notebook format: https://github.com/mohammadijoo/Machine_Learning_Tutorials The course is bilingual: English and Persian/Farsi versions are organized in parallel. The goal is to make a practical, notebook-first ML curriculum that students can run locally and study step by step.

Read source article
r/MachineLearningResearch

Anomaly Detection vs Classification for Visually Similar Cancer vs Mimics? [P]

I'm working on a paper and would love some input on model choice. Suppose you're trying to detect a specific type of cancer, but the negative samples are visually and morphologically very similar (i.e., “mimics” of the cancer). In this setting, would it make more sense to approach the problem as: Anomaly detection (treating the cancer as the target distribution and everything else as out-of-distribution), or

Read source article
r/MachineLearningResearch

PaddleOCR (v3/v4/v5/v6) implemented in C++ with ncnn [P]

Hi, About a year ago I shared my PaddleOCR implementation here. Since then I've made many improvements, and it now supports PP-OCR v3 through the latest v6 models. The official Paddle C++ runtime has a lot of dependencies and is very complex to deploy. To keep things simple I use ncnn for inference, it's much lighter (and faster in my task), makes deployment easy. Hope it's helpful to some of you, and feedback welcome! <

Read source article
NVIDIA BlogResearch

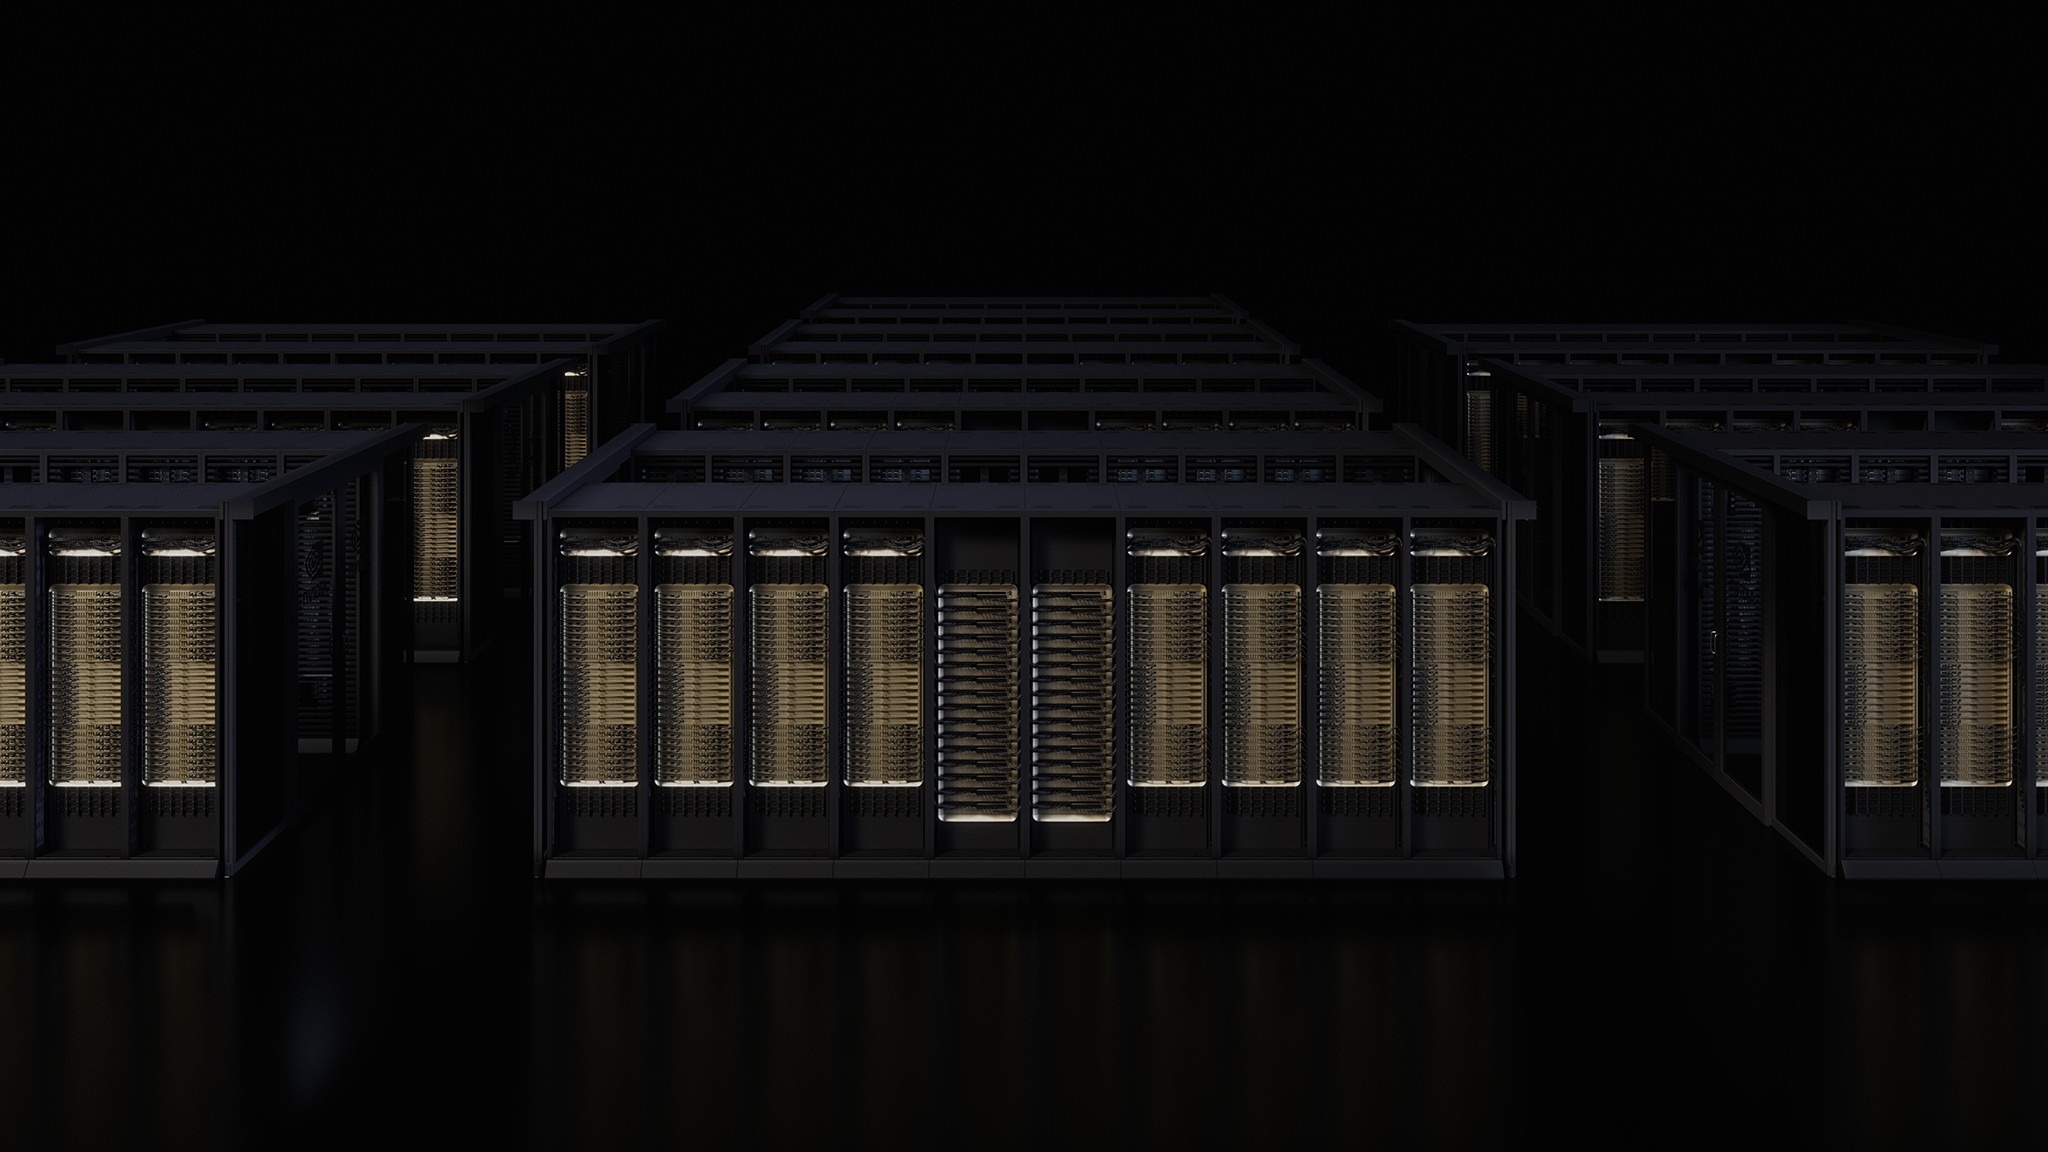
NVIDIA Blackwell Leads on First Agentic AI Infrastructure Benchmark

AgentPerf from Artificial Analysis, the industry’s first agentic AI benchmark, gives developers, enterprises and infrastructure providers a clear way to compare systems for agentic AI. In the first round of published results, the NVIDIA Blackwell Ultra NVL72 platform delivers leading performance across the agentic AI workloads tested, running 20x more agents per megawatt than NVIDIA […]

Read source article
NVIDIA Blackwell Leads on First Agentic AI Infrastructure Benchmark
Microsoft ResearchResearch

Ire identifies another LOTUSLITE specimen

Project Ire examined a timely malware sample and determined its intent through reverse engineering—identifying LOTUSLITE characteristics even as most major EDR tools did not detect it. The post Ire identifies another LOTUSLITE specimen appeared first on Microsoft Research.

Read source article
Ire identifies another LOTUSLITE specimen
MIT Tech ReviewResearch

The Download: “reprogramming” aging, and the hidden sense of interoception

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Why “reprogramming” is the buzziest approach to reversing aging right now Earlier this week, Life Biosciences, a biotech company focused on reversing age-related diseases, announced that it had dosed its first…

Read source article
The Download: “reprogramming” aging, and the hidden sense of interoception
MIT Tech ReviewResearch

You do your own time

There we were, a regular murderers’ row of librarians. Little Jo. Eustace. And me. Turning around in the nave of our library to greet the sound of footsteps, pistols leveled in case whoever was coming in didn’t respect sanctuary. Little Jo had a stack of books under one arm. Eustace was holding the screwdriver she’d…

Read source article
r/MachineLearningResearch

Building an Open Source Edge Semantic Cache for LLMs in Rust/WASM – Sanity check on the architecture? [D]

Hey everyone, I am planning out a new open-source infrastructure project and want to get some brutal feedback on the architecture and use-case validity from people running high volume LLM workloads in production. The Problem: Python-based proxies/gateways introduce too much latency overhead for real-time streaming agent steps or fast UI completions. Additionally, centralized semantic caching still suffers from cross-region network

Read source article
MIT Tech ReviewResearch

Inside interoception: The hidden sense of how you feel inside

MIT Technology Review Explains: Let our writers untangle the complex, messy world of science and technology to help you understand what’s coming next. You can read more from the series here. Your brain lives in the dark space of your skull. Yet it knows when the wind lifts the hairs on your skin, when your heart is…

Read source article
MIT Tech ReviewResearch

Why “reprogramming” is the buzziest approach to reversing aging right now

Earlier this week, Life Biosciences, a biotech company focused on reversing age-related diseases, announced that it had dosed its first volunteer. A person with glaucoma has had an experimental treatment injected straight into their eyeball. The idea is to try to treat the disease—which can cause vision loss—by regenerating healthy nerves in the eye. But…

Read source article
Why “reprogramming” is the buzziest approach to reversing aging right now
r/MachineLearningResearch

hubert.cpp, a C++ implementation of distilHuBERT [P]

I've written a C++ implementation of distilHuBERT. https://github.com/pfeatherstone/hubert.cpp It has no runtime dependencies, the weights are compiled into the library, it supports dynamic sizes, has performance on par with onnxruntime (in my tests) and can be easily integrated into any CMake project. Please let me know your thoughts. submitted by <a href="ht

Read source article
r/MachineLearningResearch

MICCAI 2026 Results [D]

Results are almost here. Good luck to everyone waiting for the final decision 🙂 submitted by /u/Sea_Muscle_4281 [link] [comments]

Read source article
r/MachineLearningResearch

Post-docs in ML [D]

Are there any websites listing post-doc job opening in machine learning? Currently I'm using LInkedIn to search for these. When I was a math post-doc, everyone used "MathJobs.org" to find jobs. Is there a similar website for machine learning? Thanks. submitted by /u/random_sydneysider <a href="https://www.reddit.com/r/MachineLearning/comments/1u390q5/post

Read source article
r/MachineLearningResearch

Is Symbolic Regression still a thing, given LLMs' performance? [D]

I've been teaching myself about Symbolic Regression (SR), which looks like a super exciting field. (A great intro resource below [1]). But then I was wondering: given LLMs' increasingly-growing power in generating code, which is in a way very similar to Symbolic Regression (or of course, even directly tackling symbolic regression tasks), are existing SR techniques dead? Happy to hear your thoughts. [1] <a href="https://www.youtube.com/watch?v=fe-PC

Read source article